

A State-Decomposition-Based Privacy-preserving Distributed Riemannian Gradient Tracking Algorithm Over Directed Networks
-
摘要: 主要研究了有向网络下考虑信息隐私安全的黎曼优化问题, 其中每个智能体在Stiefel流形约束下致力于最小化局部非凸目标函数的总和. 现有大多数分布式黎曼优化算法仅考虑无向网络, 同时也无法在窃听攻击下有效保护个体梯度的隐私信息. 针对这些局限, 提出一种基于状态分解的隐私保护分布式黎曼梯度跟踪算法, 命名为SD-DRGT算法. SD-DRGT算法将与梯度密切相关的状态变量分解为两个子状态: 一个公共子状态, 用于在每次迭代中与邻居智能体进行信息交换; 一个私有子状态, 用于确保局部梯度相关信息的更新, 且从未共享在网络系统. 此外, SD-DRGT算法通过引入推拉机制, 很好地适用于有向网络. 理论分析证明, SD-DRGT算法能够实现全局收敛性, 并以次线性速率收敛到稳定点. 数值实验表明, SD-DRGT算法在实现隐私保护的同时, 能够保持与未涉及隐私保护策略的相关方法类似的收敛性能.Abstract: This paper primarily investigates the Riemannian optimization problem over directed networks considering information privacy preservation, where each agent aims to minimize the sum of local non-convex objective functions subject to the constraint of a Stiefel manifold. Most existing distributed Riemannian optimization algorithms only consider undirected networks and are unable to effectively preserve the privacy information of individual gradients under eavesdropping attacks. To address these limitations, we propose a state-decomposition-based privacy-preserving distributed Riemannian gradient tracking algorithm, named the SD-DRGT algorithm. The SD-DRGT algorithm decomposes the state variable, which is closely related to the gradient, into two sub-states: A public sub-state, used for information exchange with neighboring agents at each iteration; And a private sub-state, used to ensure the update of local gradient-related information, which is never shared within the network system. Furthermore, by introducing a push-pull mechanism, the SD-DRGT algorithm is well-suited for directed networks. Theoretical analysis proves that the SD-DRGT algorithm achieves global convergence and converges to a stationary point at a sublinear rate. Numerical experiments demonstrate that the SD-DRGT algorithm maintains similar convergence performance comparable to relevant methods that do not employ privacy-preserving strategies, while simultaneously ensuring privacy preservation.
-
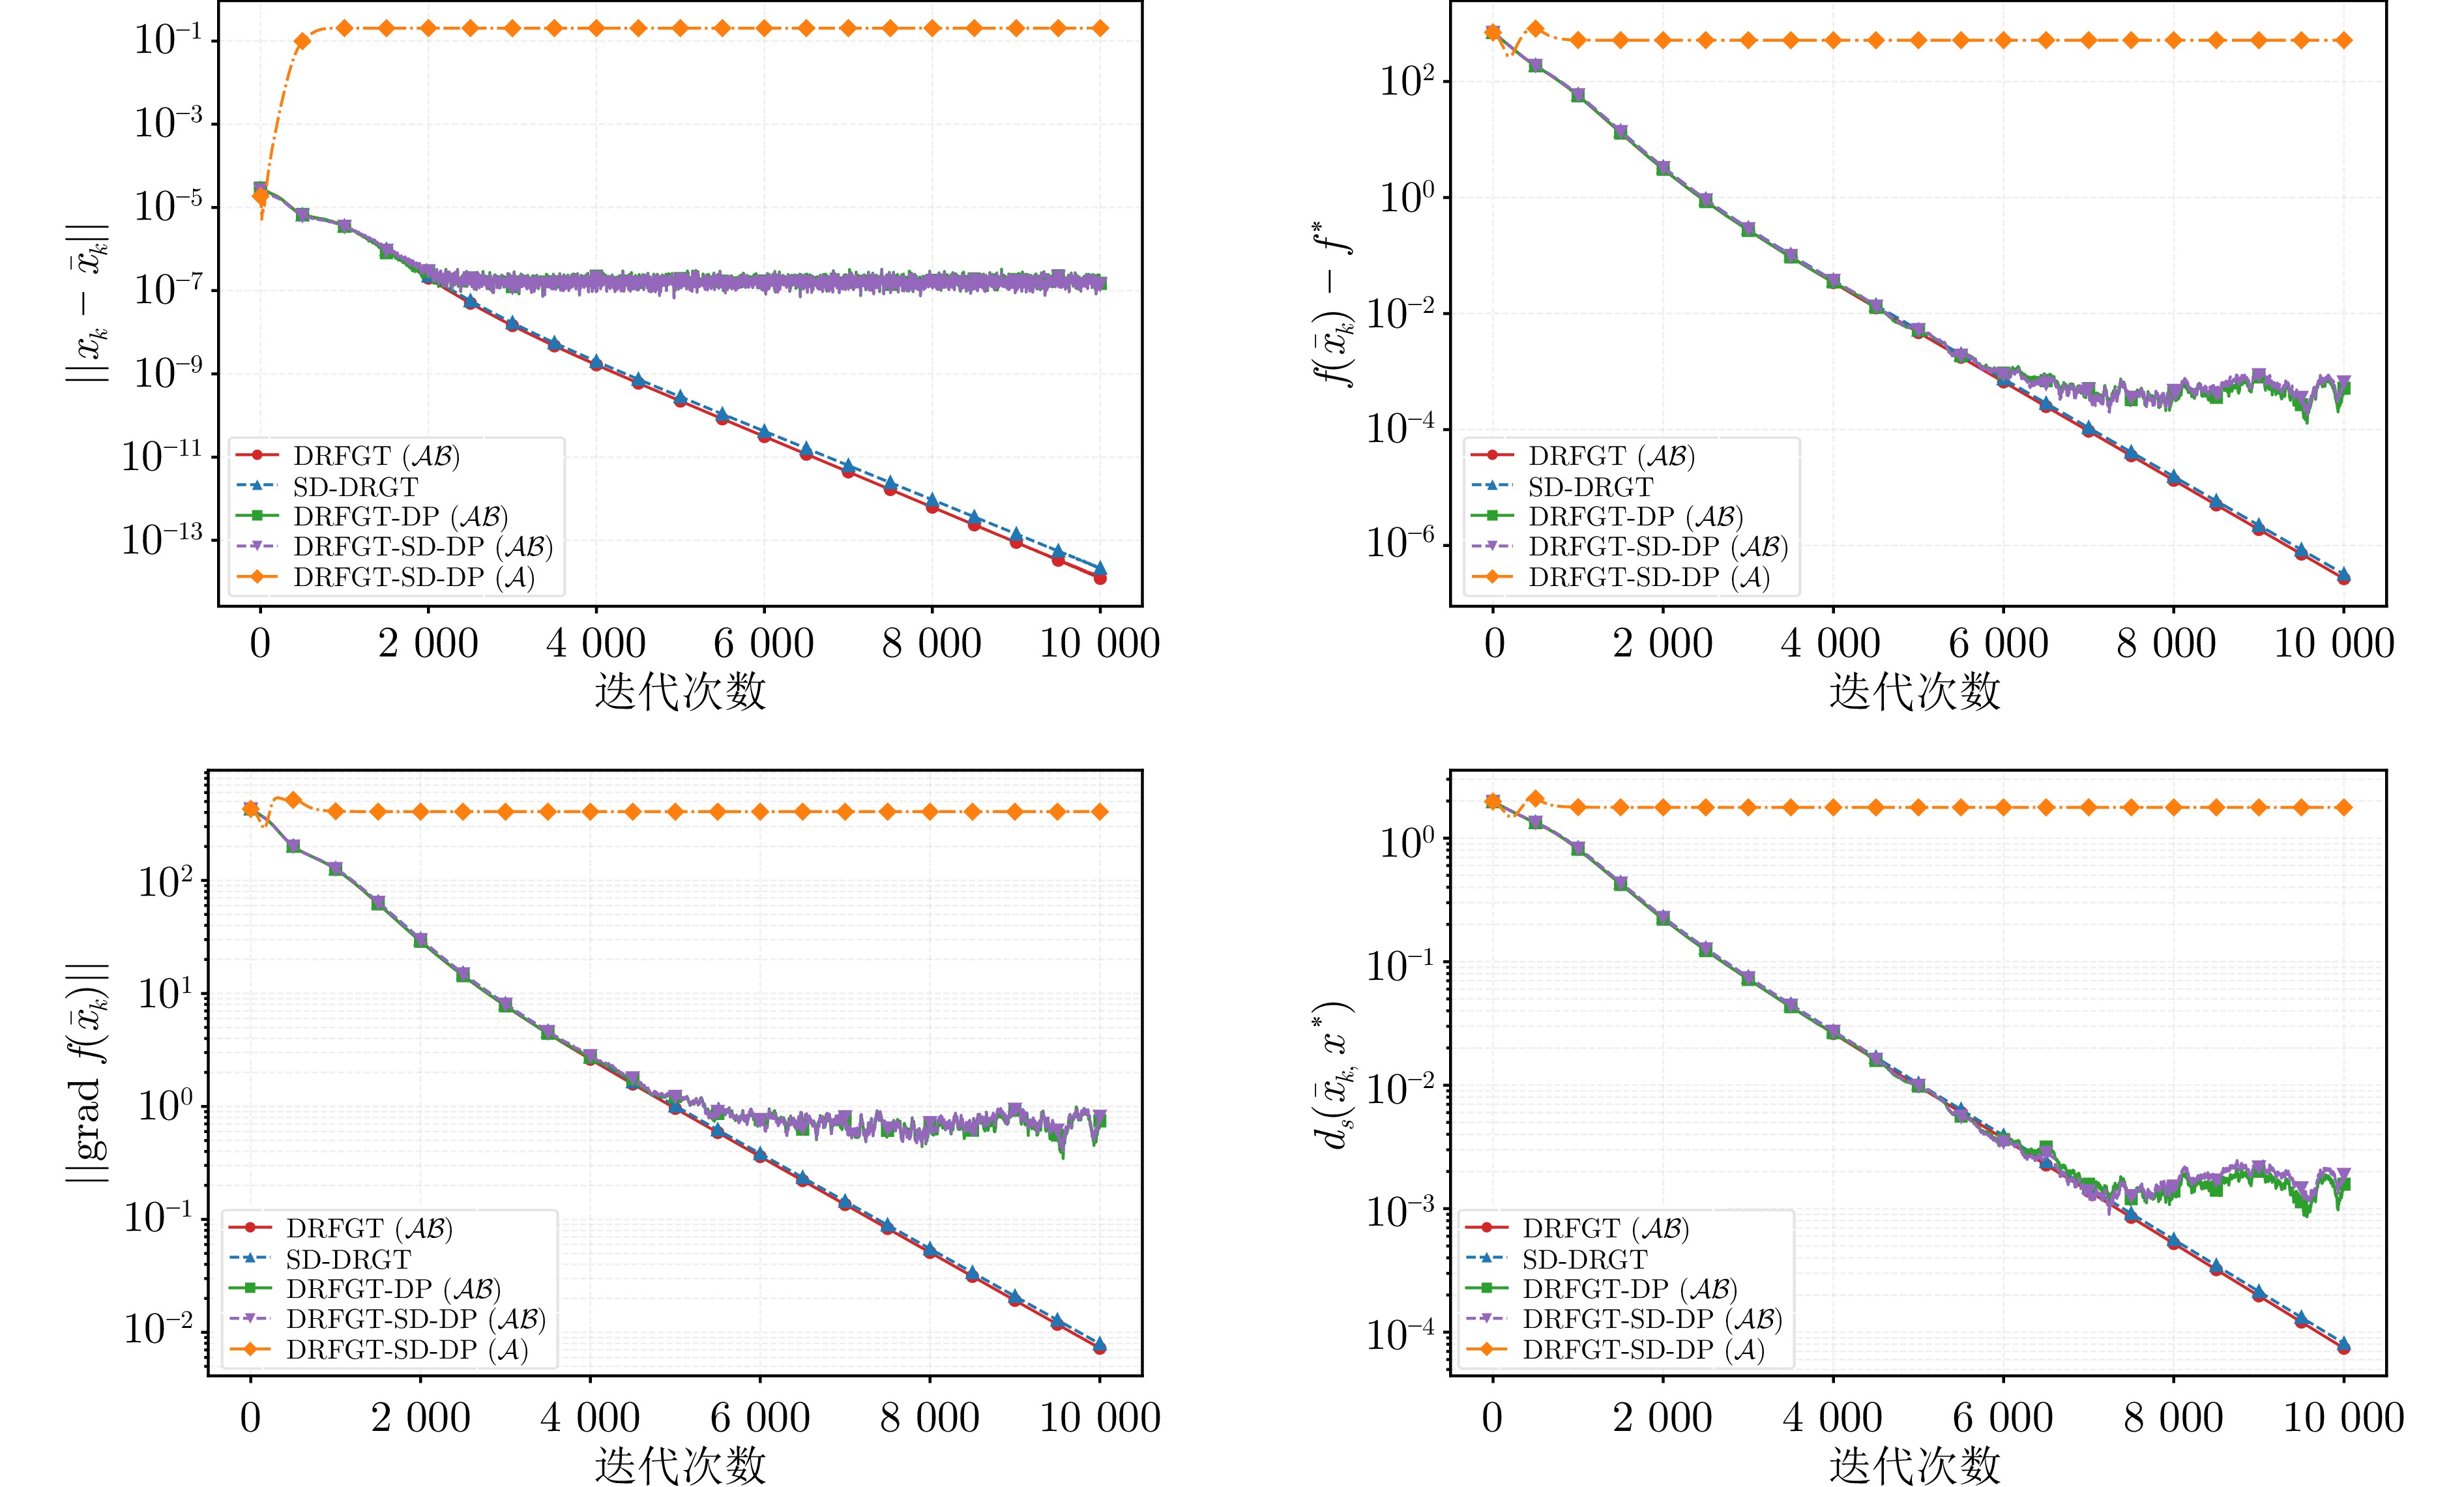
图 1 基于合成数据集的分布式主成分分析实验结果
Fig. 1 Experimental results of distributed principal component analysis on a synthetic dataset
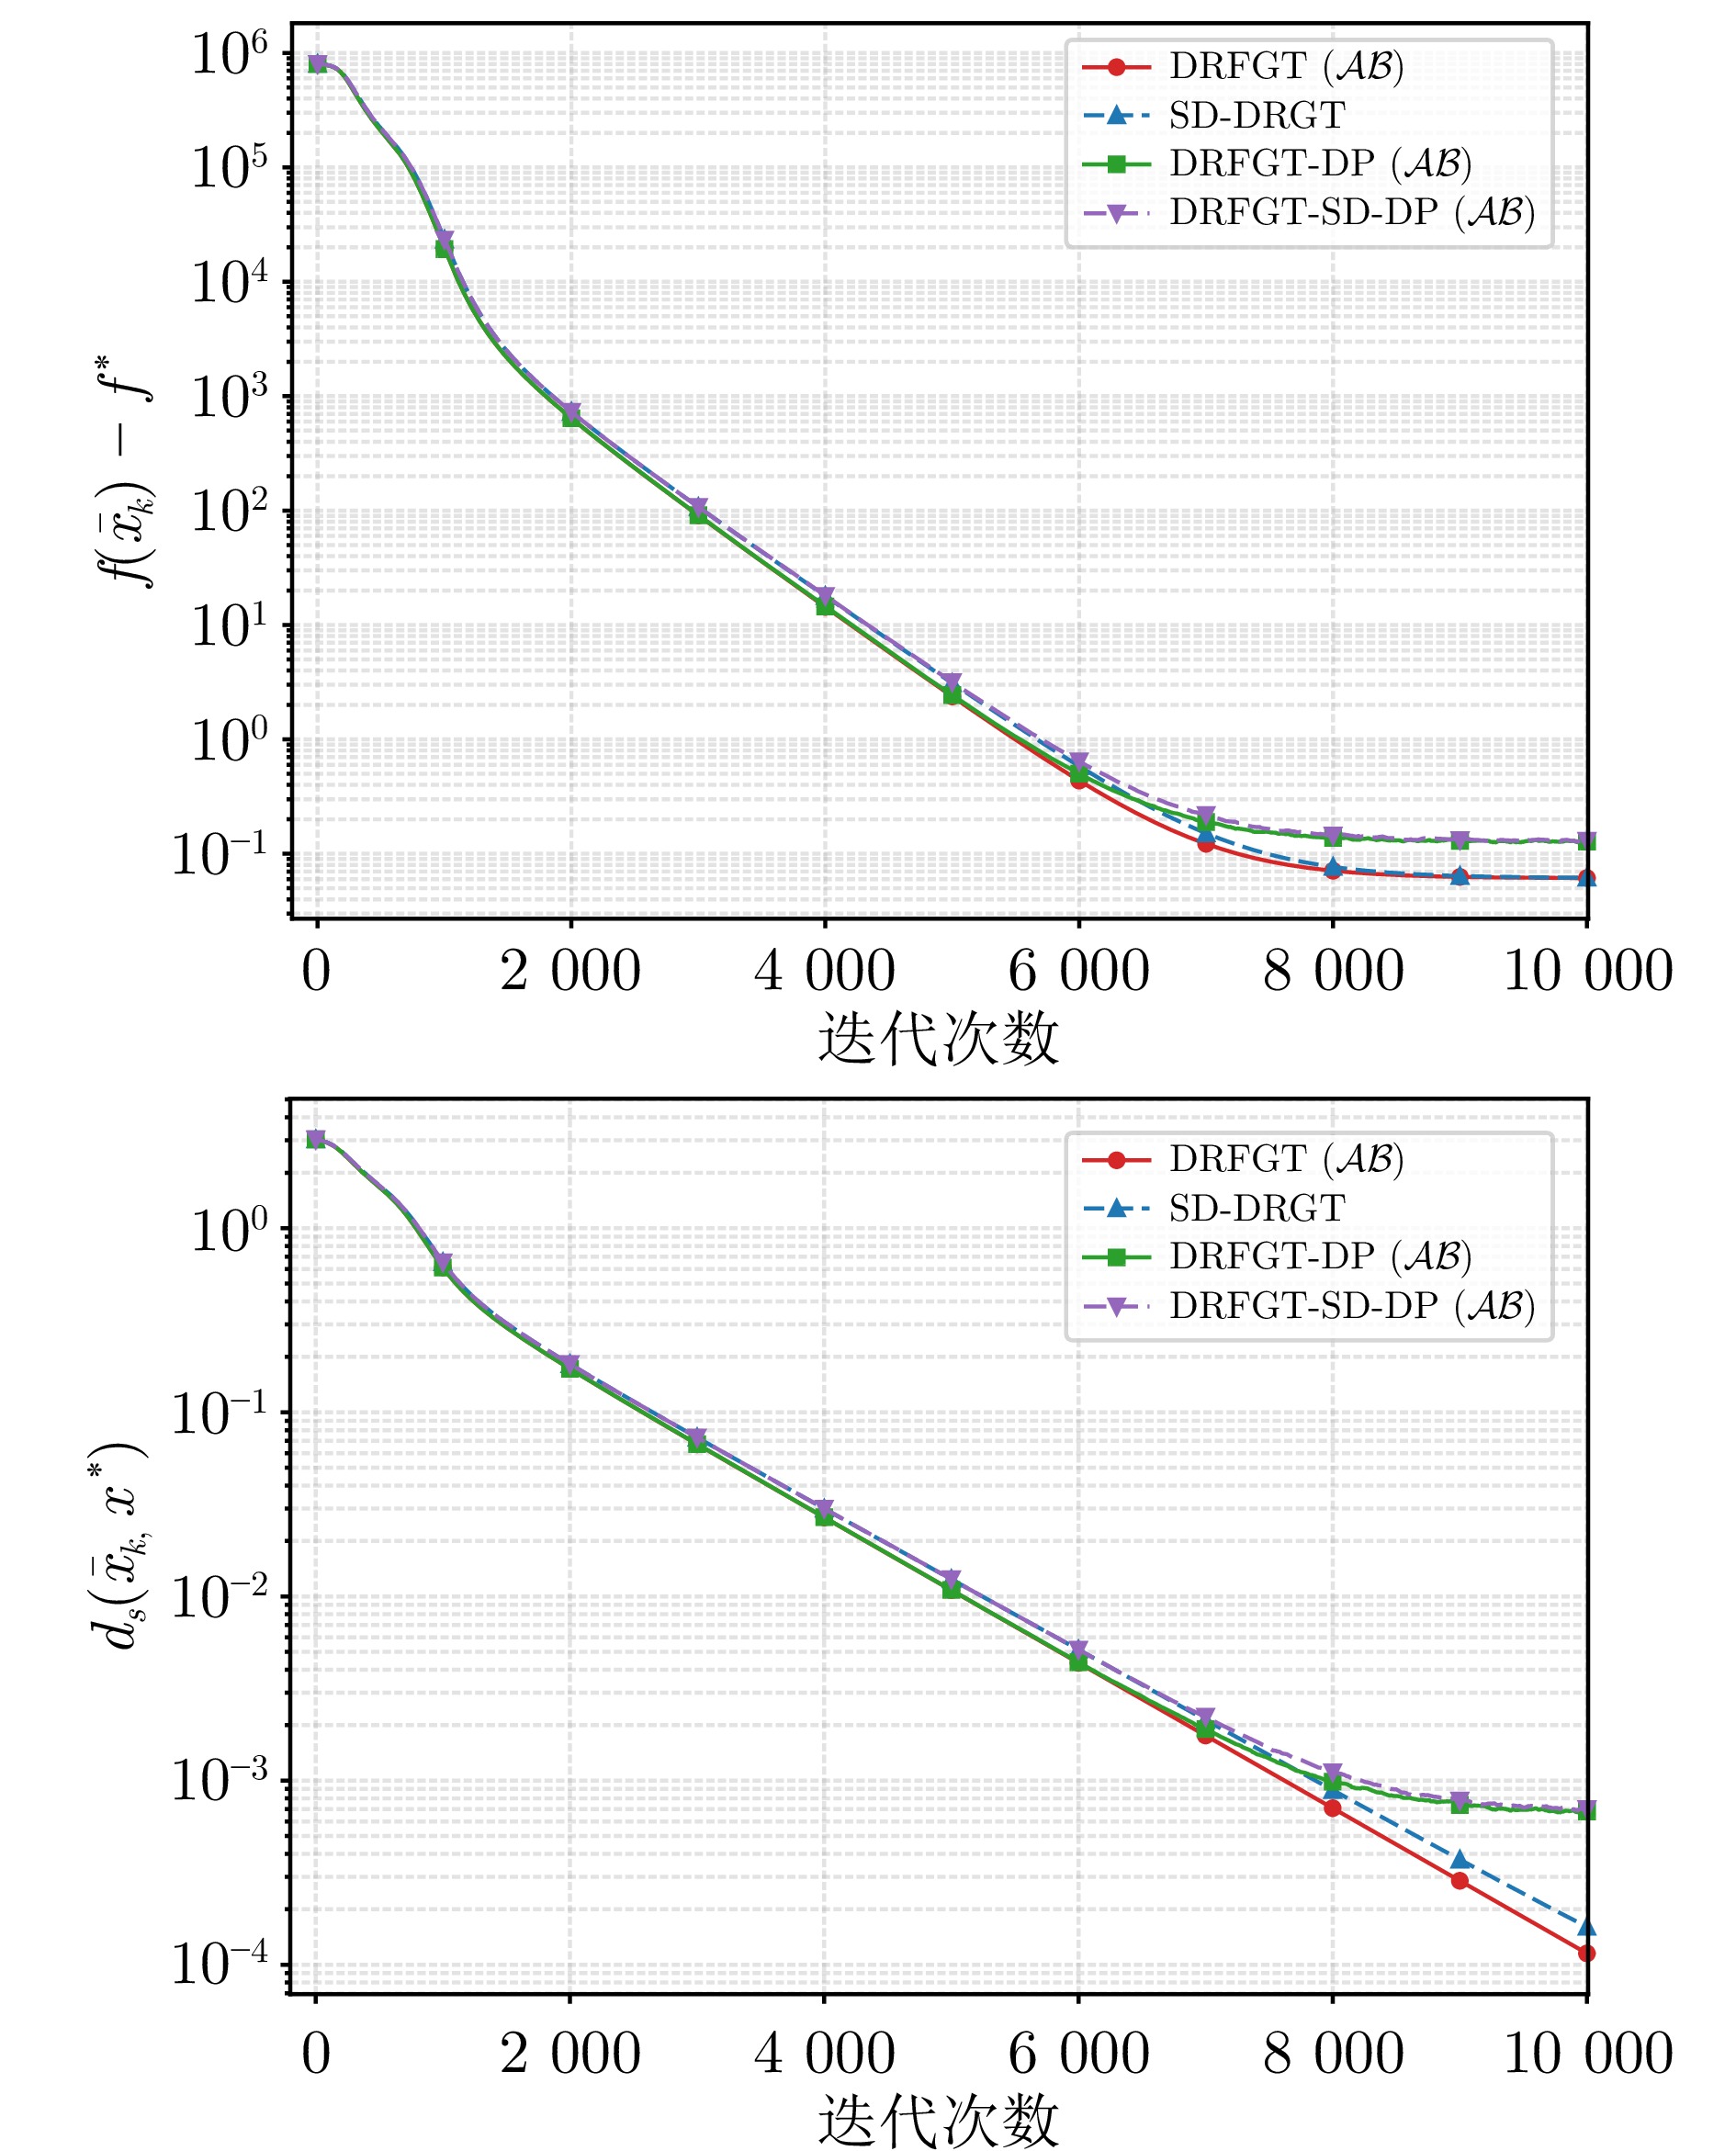
图 2 基于MNIST数据集的分布式主成分分析实验结果
Fig. 2 Experimental results of distributed principal component analysis on the MNIST dataset
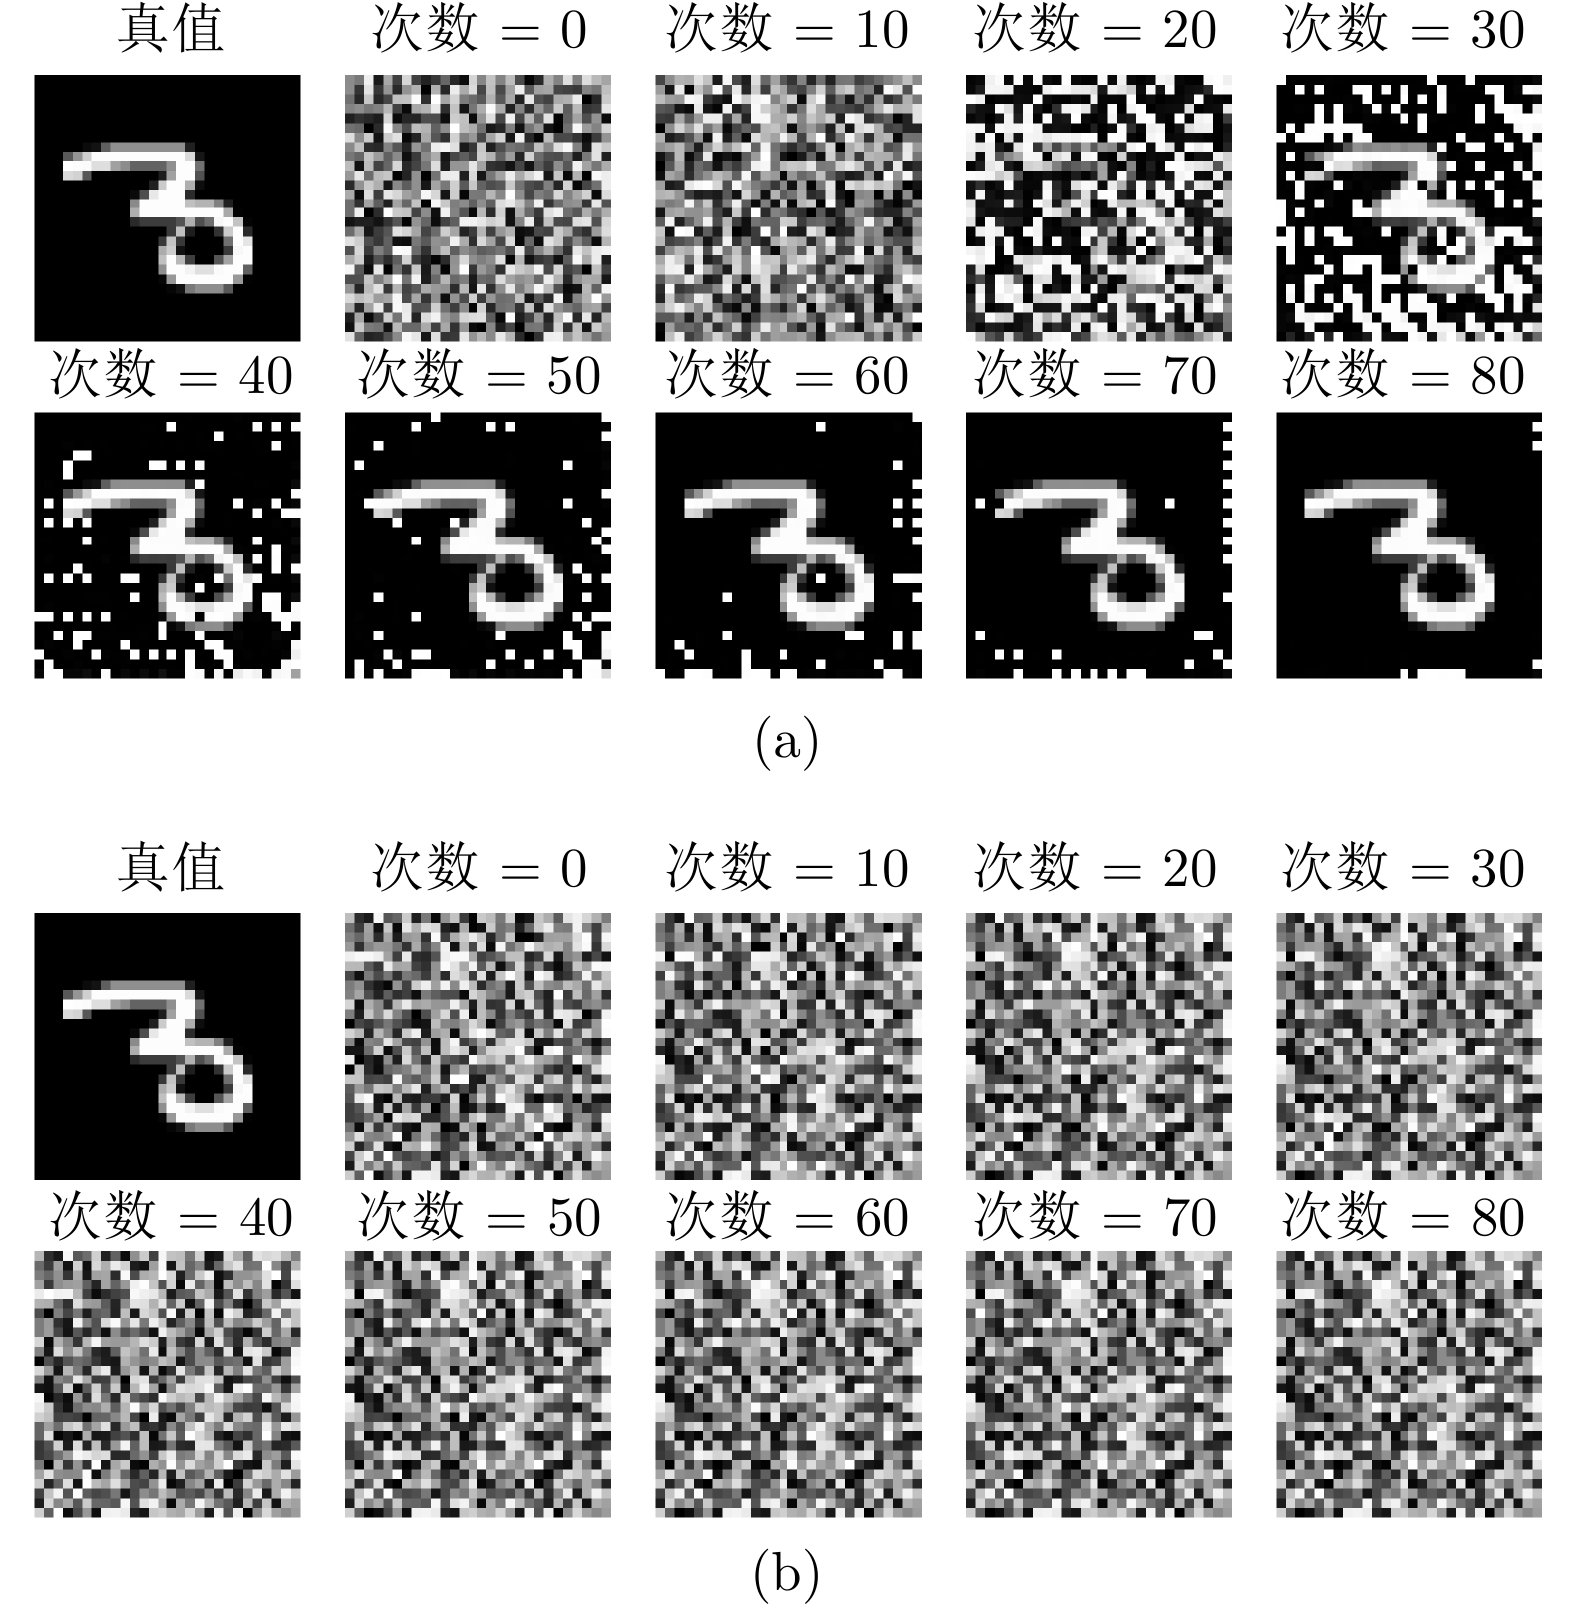
图 3 DLG攻击结果 ((a) DRFGT; (b) SD-DRGT)
Fig. 3 Results of the DLG attack ((a) DRFGT; (b) SD-DRGT)
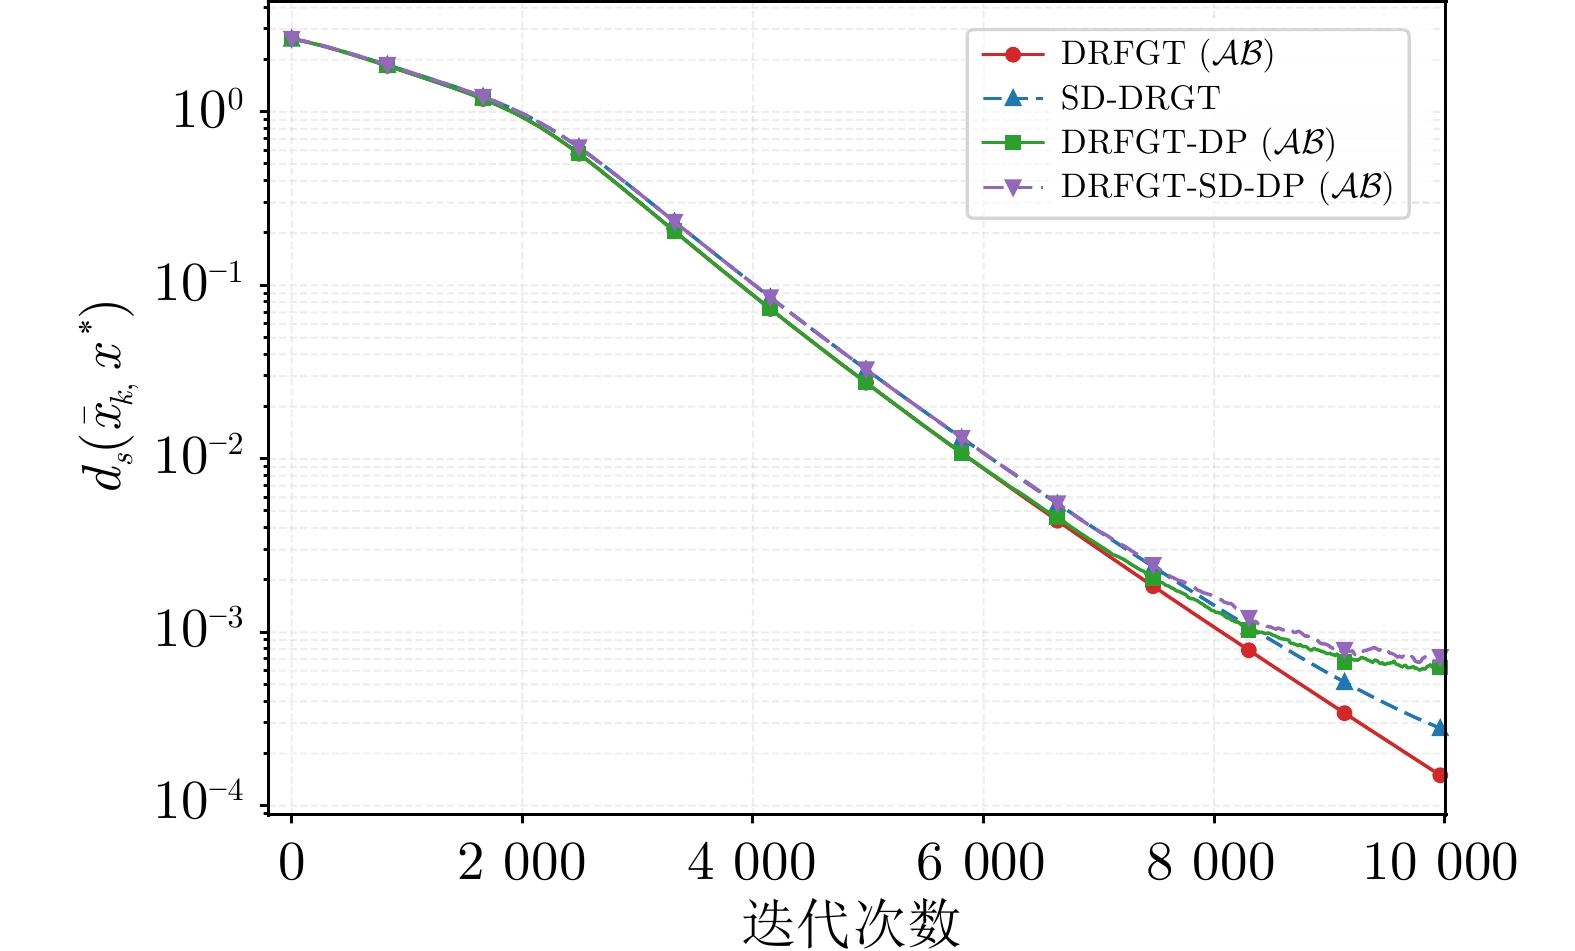
图 4 基于合成数据集的分布式低秩矩阵补全实验结果
Fig. 4 Experimental results of distributed low-rank matrix completion on a synthetic dataset
表 1 SD-DRGT与现有分布式黎曼优化方法的比较
Table 1 Comparison of SD-DRGT with existing distributed Riemannian optimization methods
方法 网络拓扑 流形约束处理 隐私保护 主要特点 收敛性质 文献[29] 无向 收缩 否 黎曼梯度跟踪 $ \mathrm{O}(1/\sqrt{K});\mathrm{O}(1/K) $ 文献[30] 无向 投影 否 投影黎曼梯度跟踪 $ \mathrm{O}(1/\sqrt{K});\mathrm{O}(1/K) $ 文献[31] 无向 投影 否 EXTRA型、单步通信 $ \mathrm{O}(1/K) $ 文献[32] 无向 着陆场 否 避免显式收缩 全局收敛 文献[34] 无向 投影 否 引入量化以降低通信负担 $ \mathrm{O}(1/K) $ SD-DRGT 有向 着陆场 状态分解 Push-Pull + 隐私保护 $ {{{\bf{O}}}{\bf{(1}}/{\boldsymbol{K}}{\bf{)}}} $  下载: 导出CSV
-
[1] Shen Y, Wang Z, Dong H, Lu G, Alsaadi F E. Distributed recursive state estimation for a class of multi-rate nonlinear systems over wireless sensor networks under FlexRay protocols. IEEE Transactions on Network Science and Engineering, 2023, 10(3): 1551−1563 doi: 10.1109/TNSE.2022.3229889 [2] Li T, Yu X Y, Lin Q F, Lv Y Z, Wen G H, Shi C. Distributed cooperative localization for unmanned systems using UWB/INS integration in GNSS-denied environments. IEEE Transactions on Instrumentation and Measurement, 2025, 74: 1−13 doi: 10.1109/tim.2025.3559161 [3] Li Y T, Chen C, Zhang K K, Li D, Lü Q G, Deng S J, et al. Q-DADAM: A Quantized Distributed Online Optimization Algorithm With Adaptive Momentum. IEEE Transactions on Control of Network Systems, 2025, 12(2): 1540−1551 doi: 10.1109/TCNS.2025.3526555 [4] Lu X, Liu C, Zhu S, Mao Y, Lio P, Hui P. RLPTO: A reinforcement learning-based performance-time optimized task and resource scheduling mechanism for distributed machine learning. IEEE Transactions on Parallel and Distributed Systems, 2023, 34(12): 3266−3279 doi: 10.1109/TPDS.2023.3317388 [5] Li H Q, Hu J H, Ran L, Wang Z, Lü Q G, Du Z Y, et al. Decentralized dual proximal gradient algorithms for non-smooth constrained composite optimization problems. IEEE Transactions on Parallel and Distributed Systems, 2021, 32(10): 2594−2605 doi: 10.1109/TPDS.2021.3072373 [6] Lü Q G, Liao X F, Deng S J, Li H Q. Asynchronous algorithms for decentralized resource allocation over directed networks. IEEE Transactions on Parallel and Distributed Systems, 2023, 34(1): 16−32 doi: 10.1109/TPDS.2022.3212424 [7] Guillou E L, Fortin P, Tierny J. Distributed discrete morse sandwich: efficient computation of persistence diagrams for massive scalar data. IEEE Transactions on Parallel and Distributed Systems, 2026, 37(1): 137−154 doi: 10.1109/TPDS.2025.3626047 [8] Li T, Yu X, Lin Q, Lv Y, Wen G, Shi C. Collaborative dictionary learning for compressed sensing. IEEE Transactions on Instrumentation and Measurement, 2025, 74: 1−13 [9] Li W Y, Lu W Z, Liang X J, Chen M R, Guo K. Collaborative dictionary learning for compressed sensing. IEEE Transactions on Industrial Informatics, 2024, 20(7): 9610−9620 doi: 10.1109/TII.2024.3385786 [10] He F, Yang R K, Shi L, Huang X L. A decentralized framework for kernel PCA with projection consensus constraints. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2025, 47(5): 3908−3921 doi: 10.1109/TPAMI.2025.3537318 [11] Wang L, Liu X. Decentralized optimization over the Stiefel manifold by an approximate augmented lagrangian function. IEEE Transactions on Signal Processing, 2022, 70: 3029−3041 doi: 10.1109/TSP.2022.3182883 [12] Lin A Y, Ling Q. Decentralized and privacy-preserving low-rank matrix completion. Journal of the Operations Research Society of China, 2015, 3(2): 189−205 doi: 10.1007/s40305-015-0080-4 [13] Hu J, Ao R C, So A M C, Yang M H, Wen Z W. Riemannian natural gradient methods. SIAM Journal on Scientific Computing, 2024, 46(1): A204−A231 doi: 10.1137/22M1509643 [14] Katsman I, Chen E, Holalkere S, Asch A, Lou A, Lim S N, et al. Riemannian residual neural networks. In: Proceedings of the 37th International Conference on Neural Information Processing Systems, New Orleans, USA: Curran Associates, 2023. 63502-63514 [15] Gao Z, Wu Y W, Fan X M, Harandi M, Jia Y. Learning to optimize on Riemannian manifolds. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2022, 45(5): 5935−5952 doi: 10.1109/tpami.2022.3215702 [16] Wang R, Jin S C, Cai Z Y, Chen Z H, Wu X J, Kittler J. Learning a better SPD network for signal classification: A Riemannian batch normalization method. IEEE Transactions on Neural Networks and Learning Systems, 2025, 36(11): 19574−19588 doi: 10.1109/TNNLS.2025.3589362 [17] Nedic A, Ozdaglar A. Distributed subgradient methods for multi-agent optimization. IEEE Transactions on Automatic Control, 2009, 54(1): 48−61 doi: 10.1109/TAC.2008.2009515 [18] Yuan K, Ling Q, Yin W T. On the convergence of decentralized gradient descent. SIAM Journal on Optimization, 2016, 26(3): 1835−1854 doi: 10.1137/130943170 [19] Qu G N, Li N. Harnessing smoothness to accelerate distributed optimization. IEEE Transactions on Control of Network Systems, 2017, 5(3): 1245−1260 [20] Carnevale G, Farina F, Notarnicola I, Notarstefano G. GTAdam: Gradient tracking with adaptive momentum for distributed online optimization. IEEE Transactions on Control of Network Systems, 2022, 10(3): 1436−1448 doi: 10.1109/tcns.2022.3232519 [21] Shi W, Ling Q, Wu G, Yin W T. EXTRA: an exact first-order algorithm for decentralized consensus optimization. SIAM Journal on Optimization, 2015, 25(2): 944−966 doi: 10.1137/14096668X [22] Wang H, Han D, Liu T, Liu K, Li J, Xia Y. Byzantine-robust distributed vertical learning over time-varying networks. Automatica, 2026, 191: 113113 doi: 10.1016/j.automatica.2026.113113 [23] Nedić A, Olshevsky A. Stochastic gradient-push for strongly convex functions on time-varying directed graphs. IEEE Transactions on Automatic Control, 2016, 61(12): 3936−3947 doi: 10.1109/TAC.2016.2529285 [24] Li H Q, Lü Q G, Liao X F, Huang T W. Accelerated Convergence Algorithm for Distributed Constrained Optimization under Time-Varying General Directed Graphs. IEEE Transactions on Systems, Man, and Cybernetics: Systems, 2020, 50(7): 2612−2622 doi: 10.1109/TSMC.2018.2823901 [25] Lü Q G, Li H Q, Wu C X, Huang T W, Suganthan P-N. Decentralized Constrained Optimization Over Time-Varying Directed Networks via Subgradient Rescaling. IEEE Transactions on Cybernetics, 2026, 56(7): 3725−3738 doi: 10.1109/TCYB.2026.3660676 [26] Pu S, Shi W, Xu J M, Nedić A. Push–pull gradient methods for distributed optimization in networks. IEEE Transactions on Automatic Control, 2020, 66(1): 1−16 [27] Han D, Liu K, Xia Y, Xie L. Byzantine-robust distributed stochastic nonconvex optimization in adversarial environments over unbalanced networks. IEEE Transactions on Automatic Control, 2025, 70(12): 8029−8043 doi: 10.1109/TAC.2025.3579218 [28] Zhou J L, Lv Y Z, Wen G H, Lü J H, Zheng D Z. Distributed Nash equilibrium seeking in consistency-constrained multicoalition games. IEEE Transactions on Cybernetics, 2023, 53(6): 3675−3687 doi: 10.1109/TCYB.2022.3155687 [29] Chen S X, Garcia A, Hong M Y, Shahrampour S. Decentralized Riemannian gradient descent on the Stiefel manifold. In: Proceedings of the 38th International Conference on Machine Learning. PMLR, 2021. 1594-1605 [30] Deng K K, Hu J. Decentralized projected Riemannian gradient method for smooth optimization on compact submanifolds embedded in the Euclidean space. Numerische Mathematik, 2025, 157(6): 2173−2210 doi: 10.1007/s00211-025-01497-0 [31] Wu J Y, Deng Z W, Hu J, Su W J, Wen Z W. Riemannian EXTRA: communication-efficient decentralized optimization over compact submanifolds with data heterogeneity. arXiv preprint arXiv: 2505.15537, 2025 [32] Sun Y B, Chen S X, Garcia A, Shahrampour S. Retraction-free decentralized non-convex optimization with orthogonal constraints. arXiv preprint arXiv: 2405.11590, 2024 [33] Ablin P, Peyré G. Fast and accurate optimization on the orthogonal manifold without retraction. In: Proceedings of the 25th International Conference on Artificial Intelligence and Statistics. PMLR, 2022. 5636-5657 [34] Chen J, Liu L N, Zhu T Y, Liu Y, Dai G, Jiang Y L, et al. Decentralized optimization on compact submanifolds by quantized Riemannian gradient tracking. IEEE Transactions on Signal Processing, 2025, 73: 1851−1861 doi: 10.1109/TSP.2025.3568045 [35] Cheng H Q, Li H Q, Hu J, Lü Q G, Zhao Y, Huang T W. Distributed online learning for constrained nonseparable problems with privacy preservation. IEEE Transactions on Emerging Topics in Computational Intelligence, 20261−10 [36] Hu J H, Chen G, Li H Q, Cheng H Q, Guo X Y, Huang T W. Decentralized nonconvex robust optimization over unsafe multiagent systems: System modeling, utility, resilience, and privacy analysis. IEEE Transactions on Cybernetics, 2025, 55(8): 3799−3810 doi: 10.1109/TCYB.2025.3573957 [37] Wang Y Q. Privacy-preserving average consensus via state decomposition. IEEE Transactions on Automatic Control, 2019, 64(11): 4711−4716 doi: 10.1109/TAC.2019.2902731 [38] Yan J J, Cao J D. Privacy preservation of optimization algorithm over unbalanced directed graph. IEEE Transactions on Network Science and Engineering, 2022, 9(4): 2164−2173 doi: 10.1109/TNSE.2022.3155481 [39] Lü Q G, He C L, Zhang K K, Li H Q, Huang T W. SD-PPDDA: a privacy efficient decentralized dual averaging algorithm over networks. IEEE Transactions on Machine Learning in Communications and Networking, 2025, 3: 1197−1209 doi: 10.1109/TMLCN.2025.3625519 [40] Chen X M, Huang L Y, He L D, Dey S, Shi L. A differentially private method for distributed optimization in directed networks via state decomposition. IEEE Transactions on Control of Network Systems, 2023, 10(4): 2165−2177 doi: 10.1109/TCNS.2023.3264932 [41] Ablin P, Vary S, Gao B, Absil P A. Infeasible deterministic, stochastic, and variance-reduction algorithms for optimization under orthogonality constraints. Journal of Machine Learning Research, 2024, 25(389): 1−38 [42] LeCun Y. The MNIST database of handwritten digits[Online], available: http://yann.lecun.com/exdb/mnist/, October 7, 2026 [43] Zhu L G, Liu Z J, Han S. Deep leakage from gradients. In: Proceedings of Advances in Neural Information Processing Systems, 2019, 32 [44] Absil P A, Malick J. Projection-like retractions on matrix manifolds. SIAM Journal on Optimization, 2012, 22(1): 135−158 doi: 10.1137/100802529 [45] Sato H, Aihara K. Cholesky QR-based retraction on the generalized Stiefel manifold. Computational Optimization and Applications, 2019, 72(2): 293−308 doi: 10.1007/s10589-018-0046-7 [46] Chen Z Y, Sun Y Q, Hu D L, Bian Y G, Wang S S, Zhang X Y, et al. Semi-supervised kernel Fisher discriminant analysis based on exponential-adjusted geometric distance. Neural Computing and Applications, 2024, 36(24): 14825−14855 doi: 10.1007/s00521-024-09768-x [47] Liao Y W, Li Z R, Pu S, Chang T H. A robust compressed push-pull method for decentralized nonconvex optimization. arXiv preprint arXiv: 2408.01727, 2024 [48] Meyer C D. Matrix analysis and applied linear algebra, Second Edition. Philadelphia: Society for Industrial and Applied Mathematics, 2023. -

 下载:

计量
- 文章访问数: 15
- HTML全文浏览量: 5
- 被引次数: 0
