

Embodied Intelligence for Typical Unmanned Platforms in Urban Open Space: Simulation Platforms, Key Technologies, and Future Prospects
-
摘要: 城市开放空间是具身智能走向实际应用的关键场景, 其复杂的环境特征与动态的交互需求为具身智能研究带来独特挑战, 特别是在低空飞行理论与技术的发展下, 无人机等具身智能载体的应用也成为当前人工智能领域的研究热点. 为填补城市开放空间具身智能领域系统性综述的空白, 聚焦该研究方向, 对其前沿进展进行全面梳理. 研究从仿真平台、核心任务、关键方法三个维度展开体系化分析, 从基于真实城市数据和虚拟城市数据两个角度, 梳理各平台的技术框架与任务支撑能力; 根据对任务目标的认知深度, 将核心任务划分为感知推理、导航、搜索三类, 概述并介绍数据集、评测基准和模型方法. 最后, 分析了开放空间具身智能在平台任务设定、感知认知能力、规划决策能力、数据与模型应用四个层面存在的挑战并展望其发展方向, 旨在为研究者提供一个全面视野, 从而促进城市开放空间具身智能研究.Abstract: Urban open space serves as a critical scenario for embodied intelligence to move toward real-world applications, where environmental complexity and dynamic interaction requirements present distinct challenges for embodied intelligence research. In particular, with the evolution of low-altitude flight theories and technologies, the application of embodied intelligence carriers such as unmanned aerial vehicles has emerged as a prominent research focus in the field of artificial intelligence. Addressing the absence of systematic reviews in this domain, frontier advancements are comprehensively surveyed. We conduct a systematic analysis spans three dimensions including simulation platforms, core tasks, and key methodologies. For simulation platforms, the technical framework and task support capability of each platform are reviewed from two perspectives, i.e., platforms based on real-world city data and those based on virtual city data. Core tasks are classified into perceptual reasoning, navigation, and object search according to the cognitive depth that task objectives require, with the corresponding datasets, evaluation benchmarks, and model methods introduced for each category. Finally, we analyze persistent challenges and prospect future directions regarding platform and task setting, perception and cognitive capabilities, planning and decision-making, and data and model deployment are analyzed, aiming to provide a comprehensive reference for the researchers, so as to promote the development of embodied intelligence in urban open space.
-
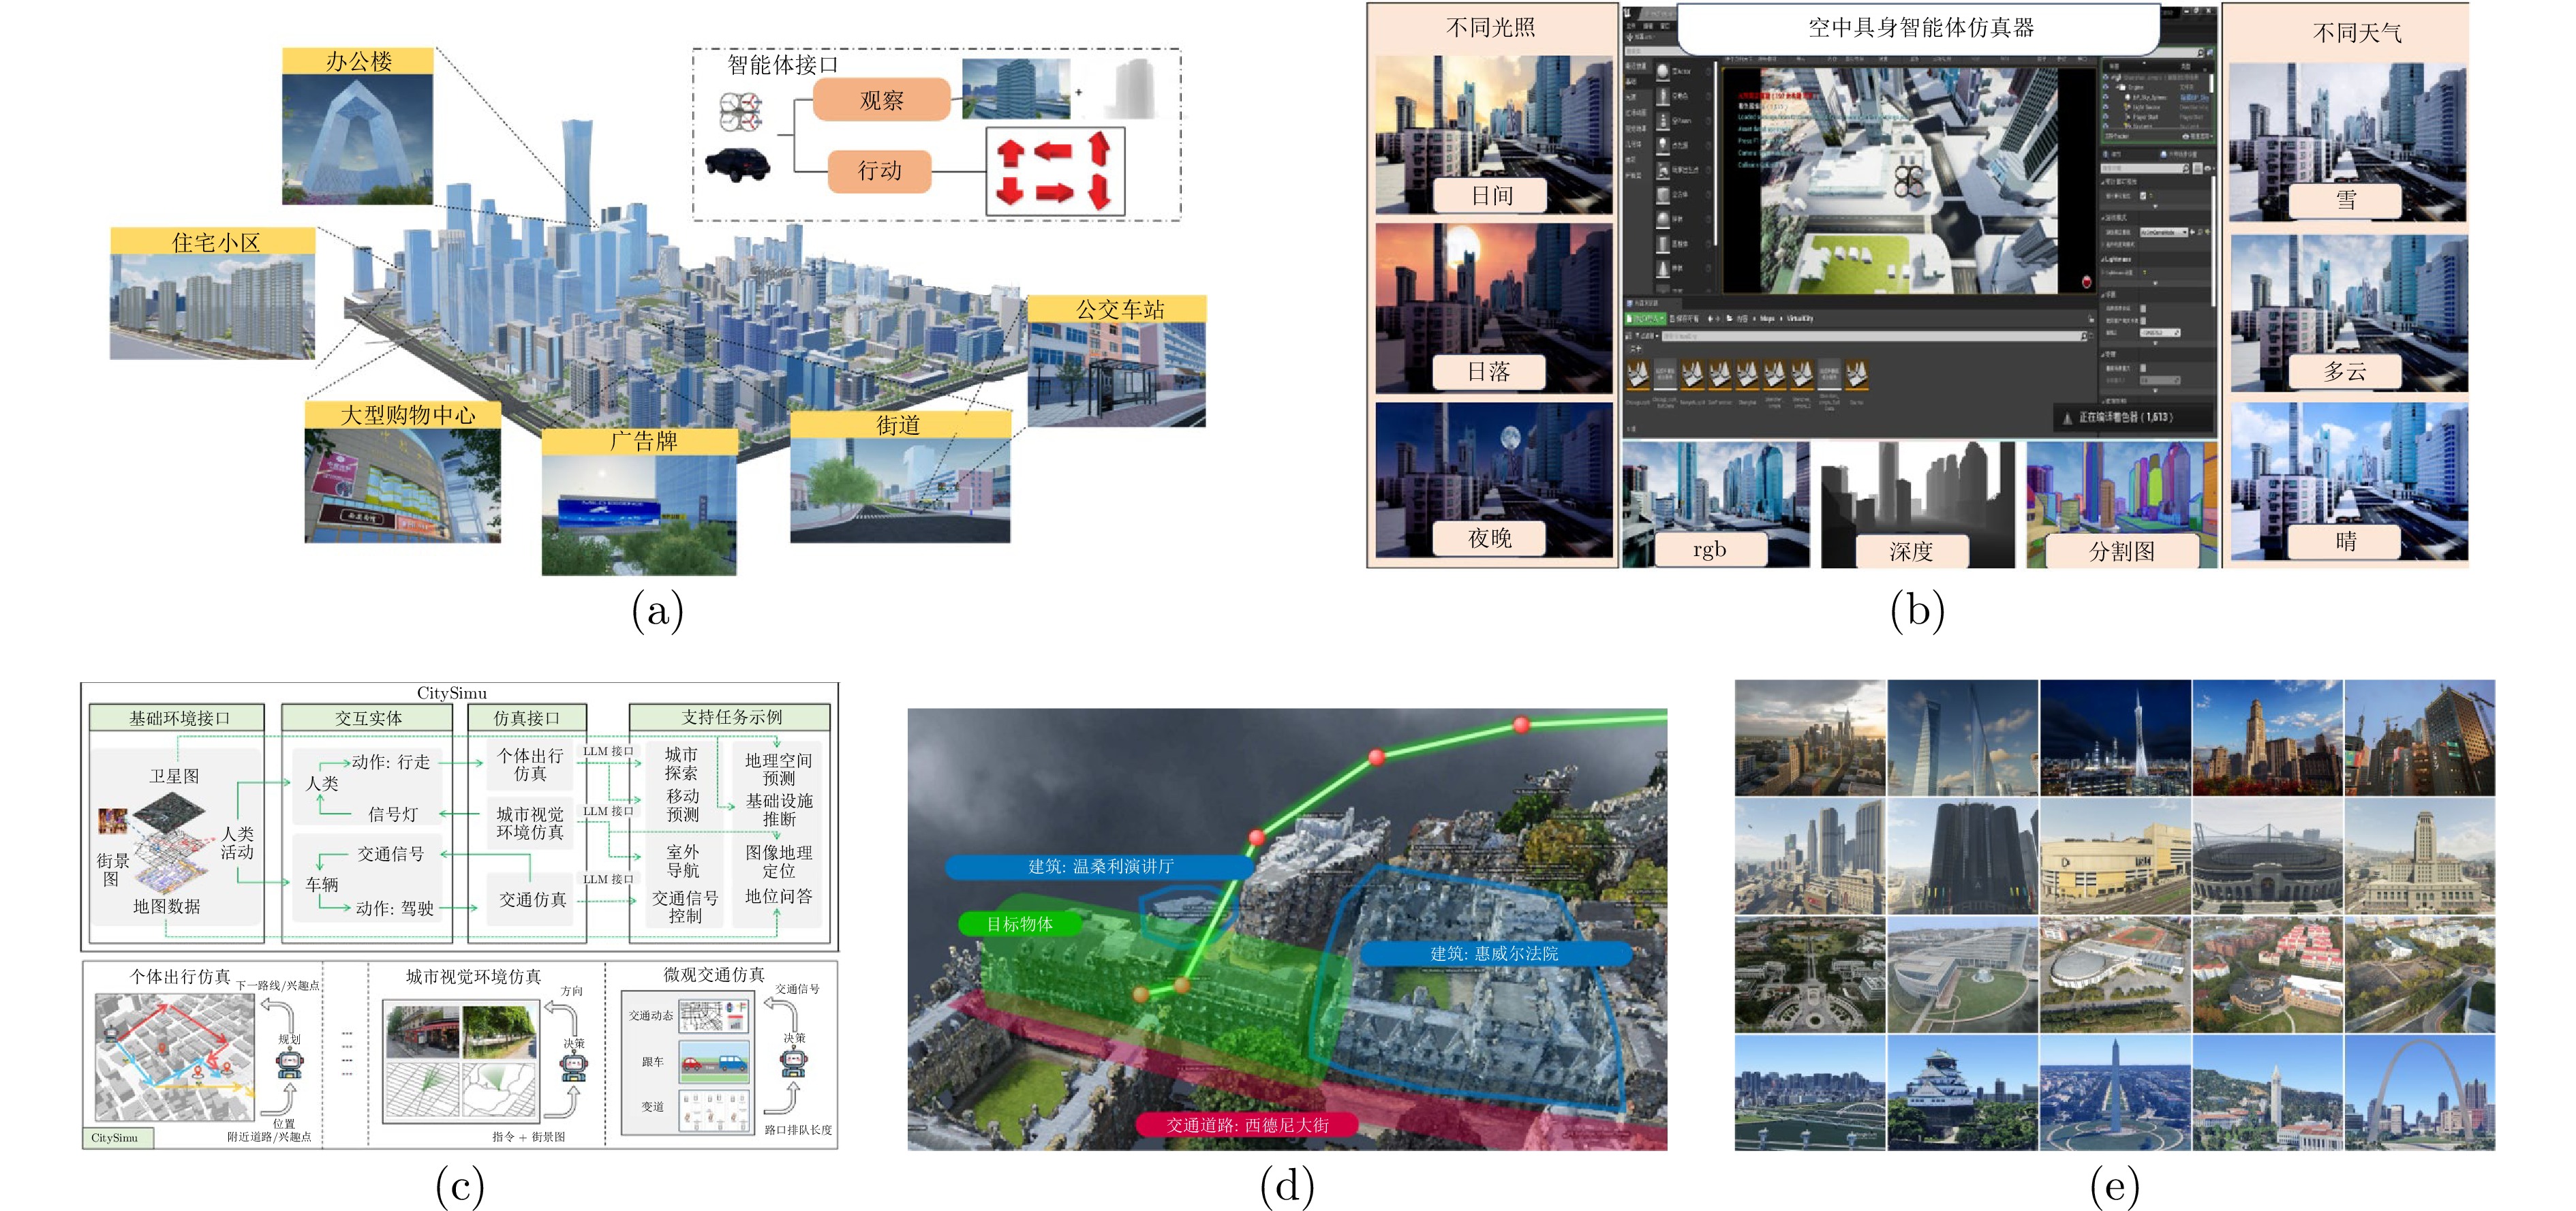
图 1 基于真实城市数据的具身智能仿真平台示意图: (a) EmbodiedCity[7], 经许可转载自文献[7], ©arXiv, 2024; (b) AeroVerse[8], 经许可转载自文献[8], ©IEEE, 2026; (c) CitySimu[19], 经许可转载自文献[19], ©ACM, 2025; (d) CityNav[20], 经许可转载自文献[20], ©IEEE, 2025; (e) OpenFly[21], 经许可转载自文献[21], ©ICLR, 2025
Fig. 1 Diagram of the embodied intelligence simulation platforms based on real urban data: (a) EmbodiedCity[7], reproduced with permission from reference [7], ©arXiv, 2024; (b) AeroVerse[8], reproduced with permission from reference [8], ©IEEE, 2026; (c) CitySimu[19], reproduced with permission from reference [19], ©ACM, 2025; (d) CityNav[20], reproduced with permission from reference [20], ©IEEE, 2025; (e) OpenFly[21], reproduced with permission from reference [21], ©ICLR, 2025
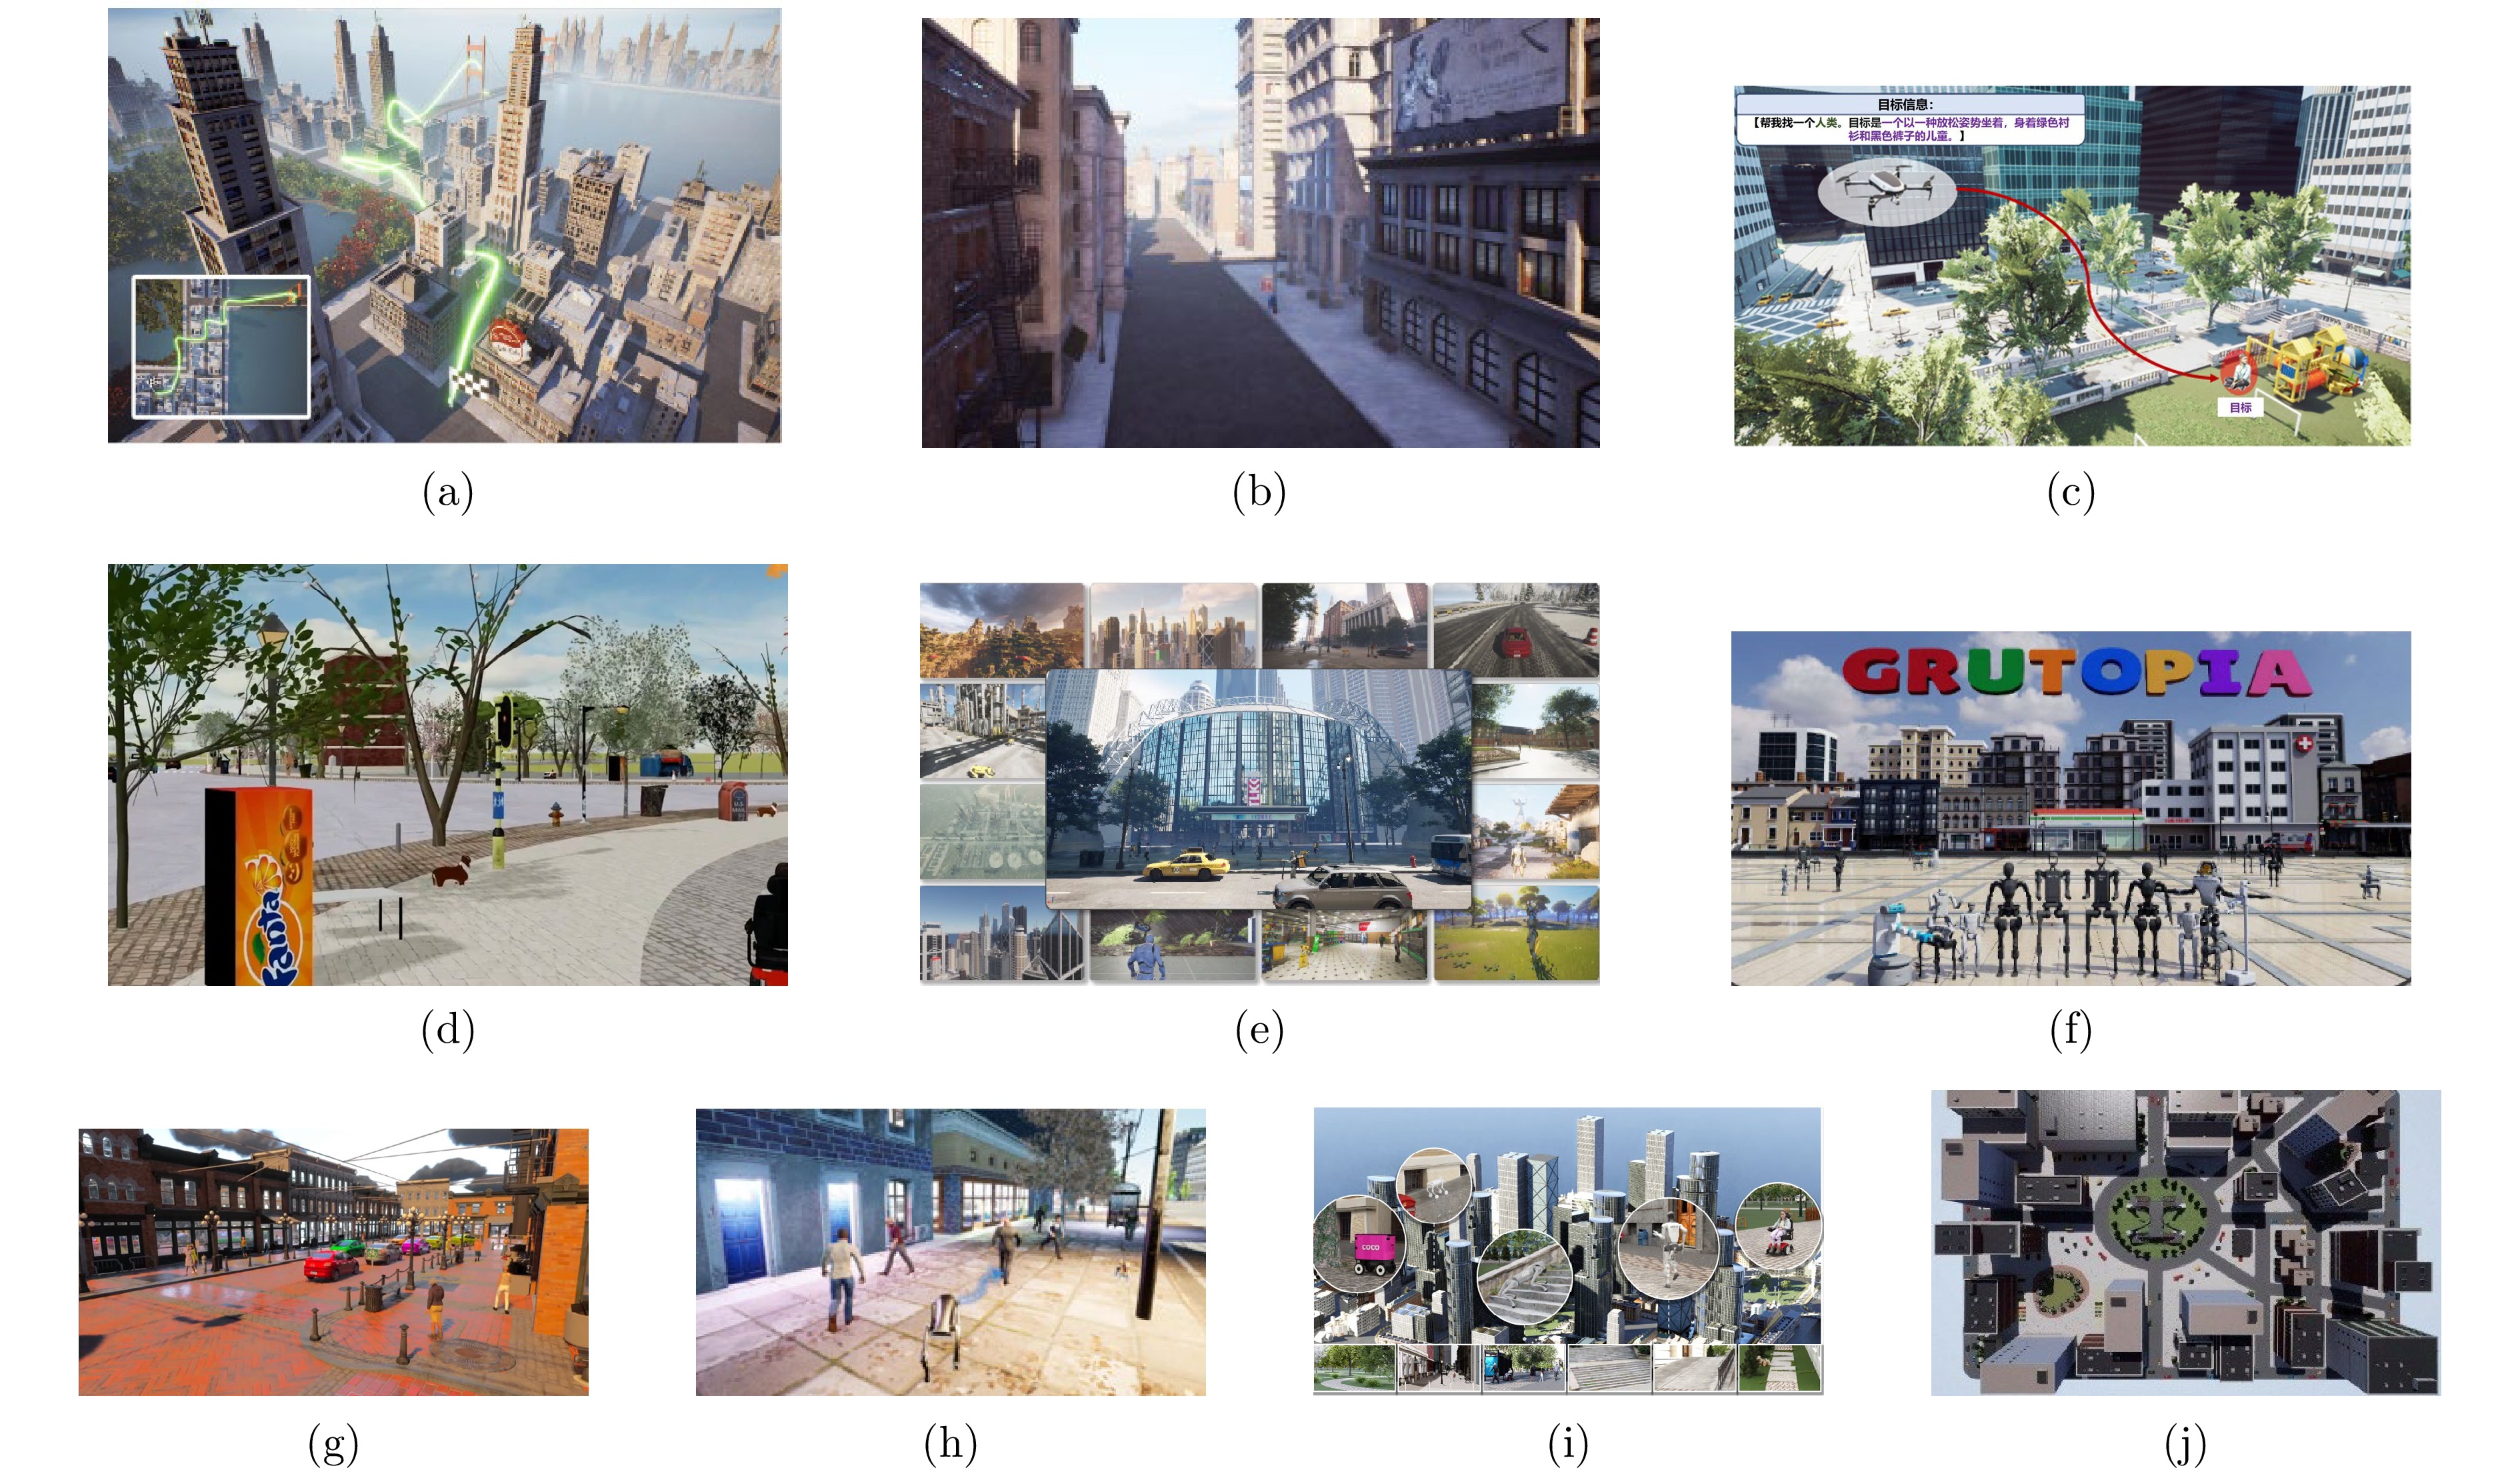
图 2 基于虚拟城市数据的具身智能仿真平台示意图: (a) AerialVLN[22], 经许可转载自文献[22], ©IEEE, 2023; (b) OpenUAV[9], 经许可转载自文献[9], ©ICLR, 2025; (c) UAV-ON[23], 经许可转载自文献[23], ©ACM, 2025; (d) MetaUrban[24], 经许可转载自文献[24], ©ICLR, 2025; (e) SimWorld[29], 经许可转载自文献[29], ©NeurIPS, 2025; (f) GRUtopia[26], 经许可转载自文献[26], ©arXiv, 2024; (g) FreeAskWorld[27], 经许可转载自文献[27], ©AAAI, 2026; (h) UnrealZoo[28], 经许可转载自文献[28], ©IEEE, 2025; (i) Urban-Sim[25], 经许可转载自文献[25], ©IEEE, 2025; (j) ECCD[30], 经许可转载自文献[30], ©NeurIPS, 2025
Fig. 2 Diagram of the embodied intelligence simulation platforms based on virtual urban data: (a) AerialVLN[22], reproduced with permission from reference [22], ©IEEE, 2023; (b) OpenUAV[9], reproduced with permission from reference [9], ©ICLR, 2025; (c) UAV-ON[23], reproduced with permission from reference [23], ©ACM, 2025; (d) MetaUrban[24], reproduced with permission from reference [24], ©ICLR, 2025; (e) SimWorld[29], reproduced with permission from reference [29], ©NeurIPS, 2025; (f) GRUtopia[26], reproduced with permission from reference [26], ©arXiv, 2024; (g) FreeAskWorld[27], reproduced with permission from reference [27], ©AAAI, 2026; (h) UnrealZoo[28], reproduced with permission from reference [28], ©IEEE, 2025; (i) Urban-Sim[25], reproduced with permission from reference [25], ©IEEE, 2025; (j) ECCD[30], reproduced with permission from reference [30], ©NeurIPS, 2025
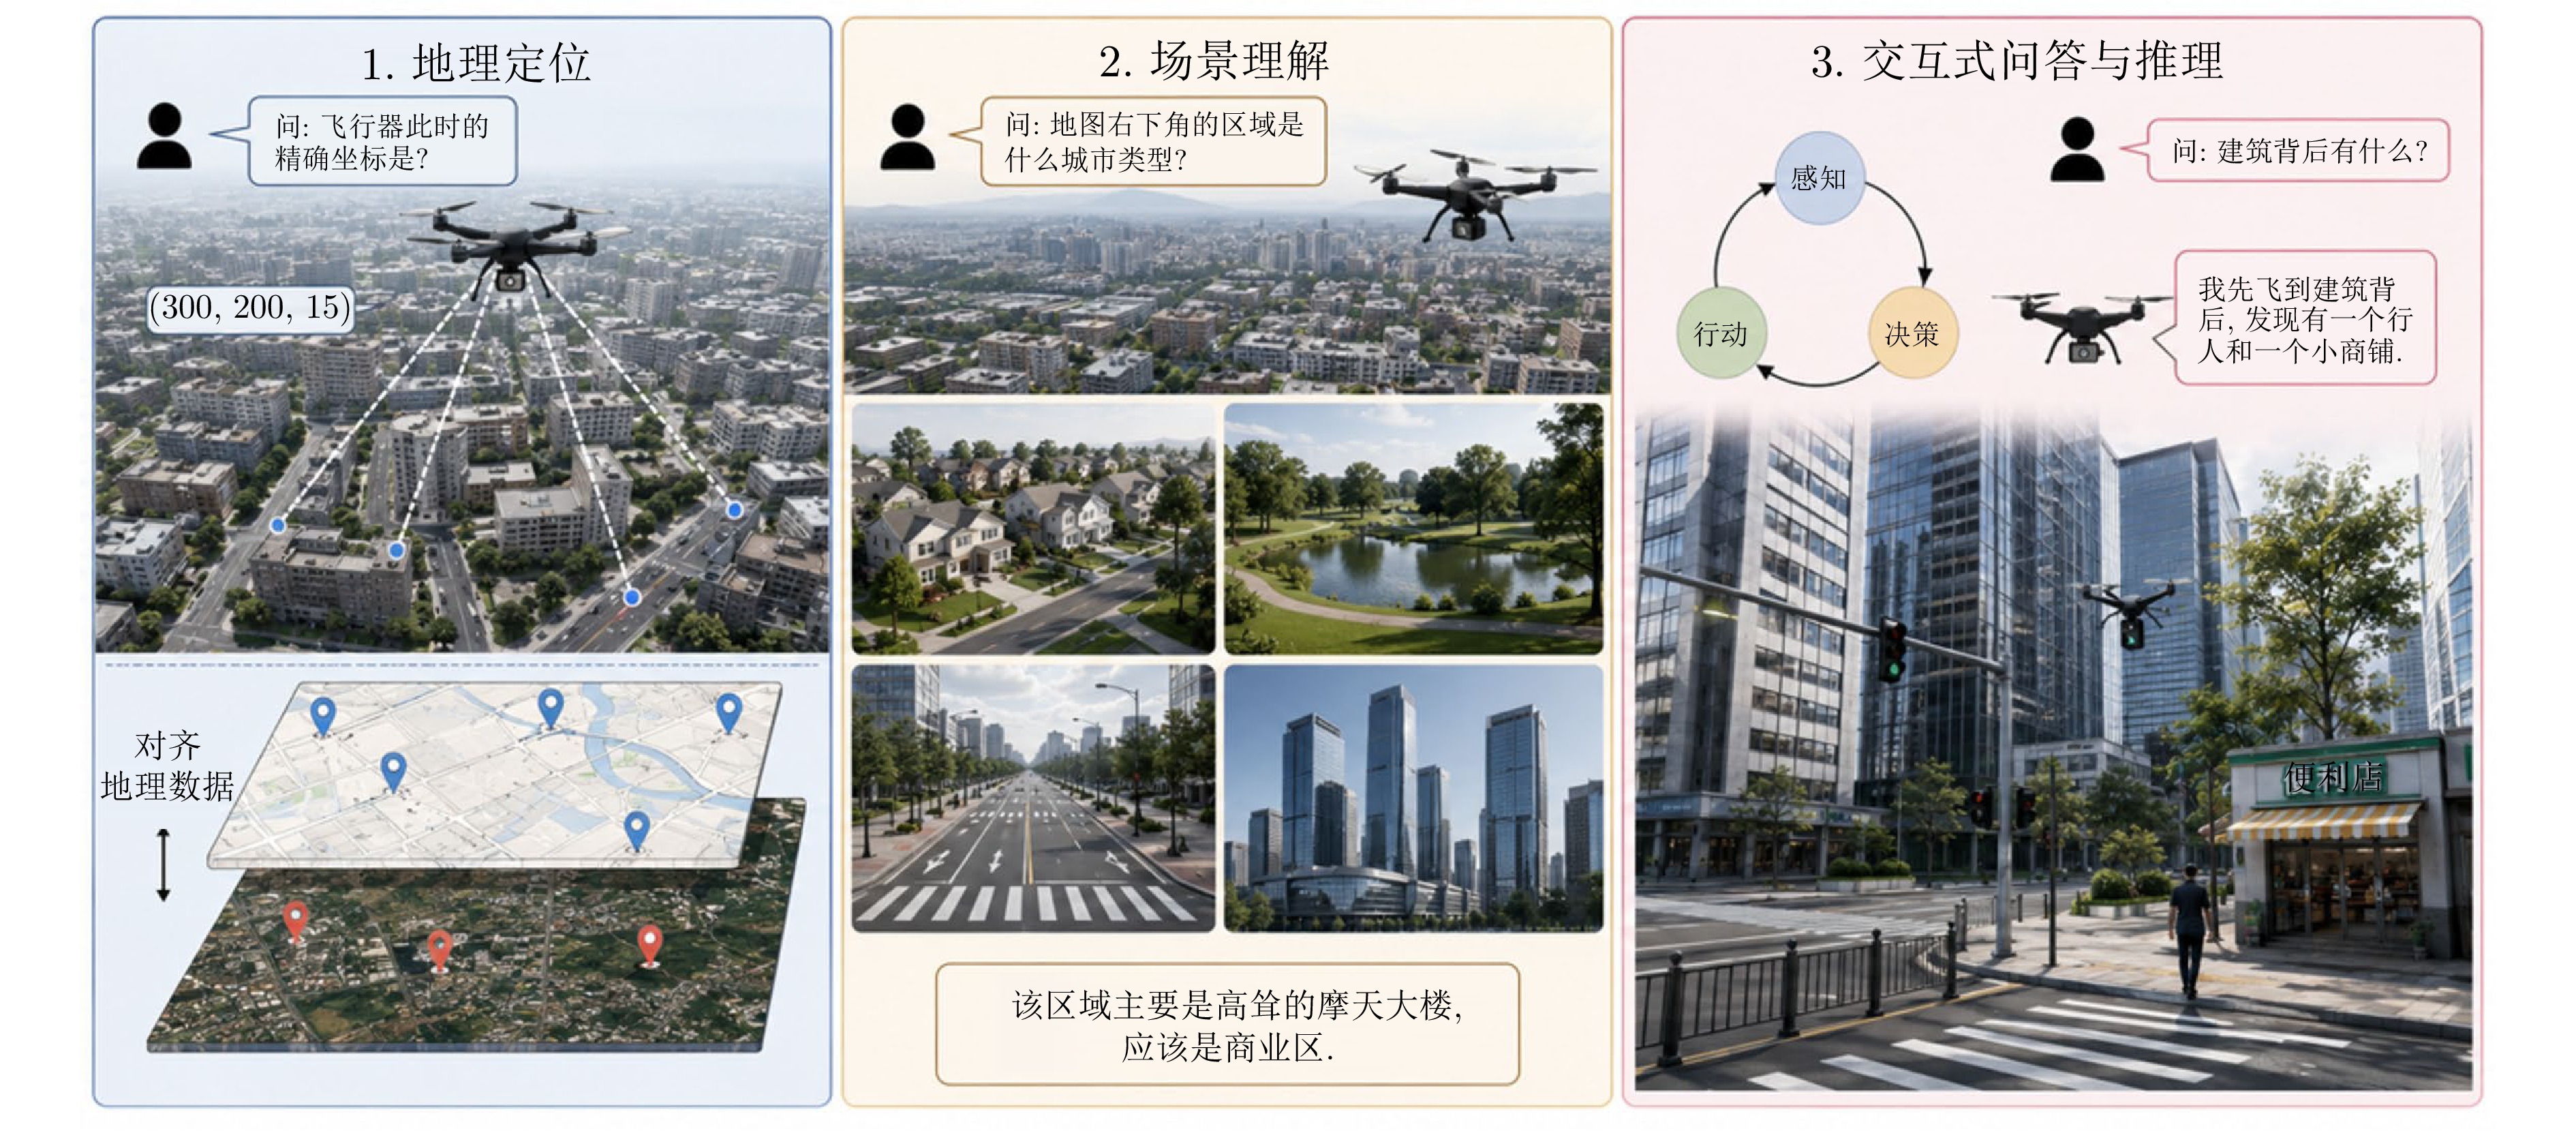
图 3 城市开放空间具身感知推理任务示意图
Fig. 3 Diagram of embodied perception and reasoning tasks for urban open space
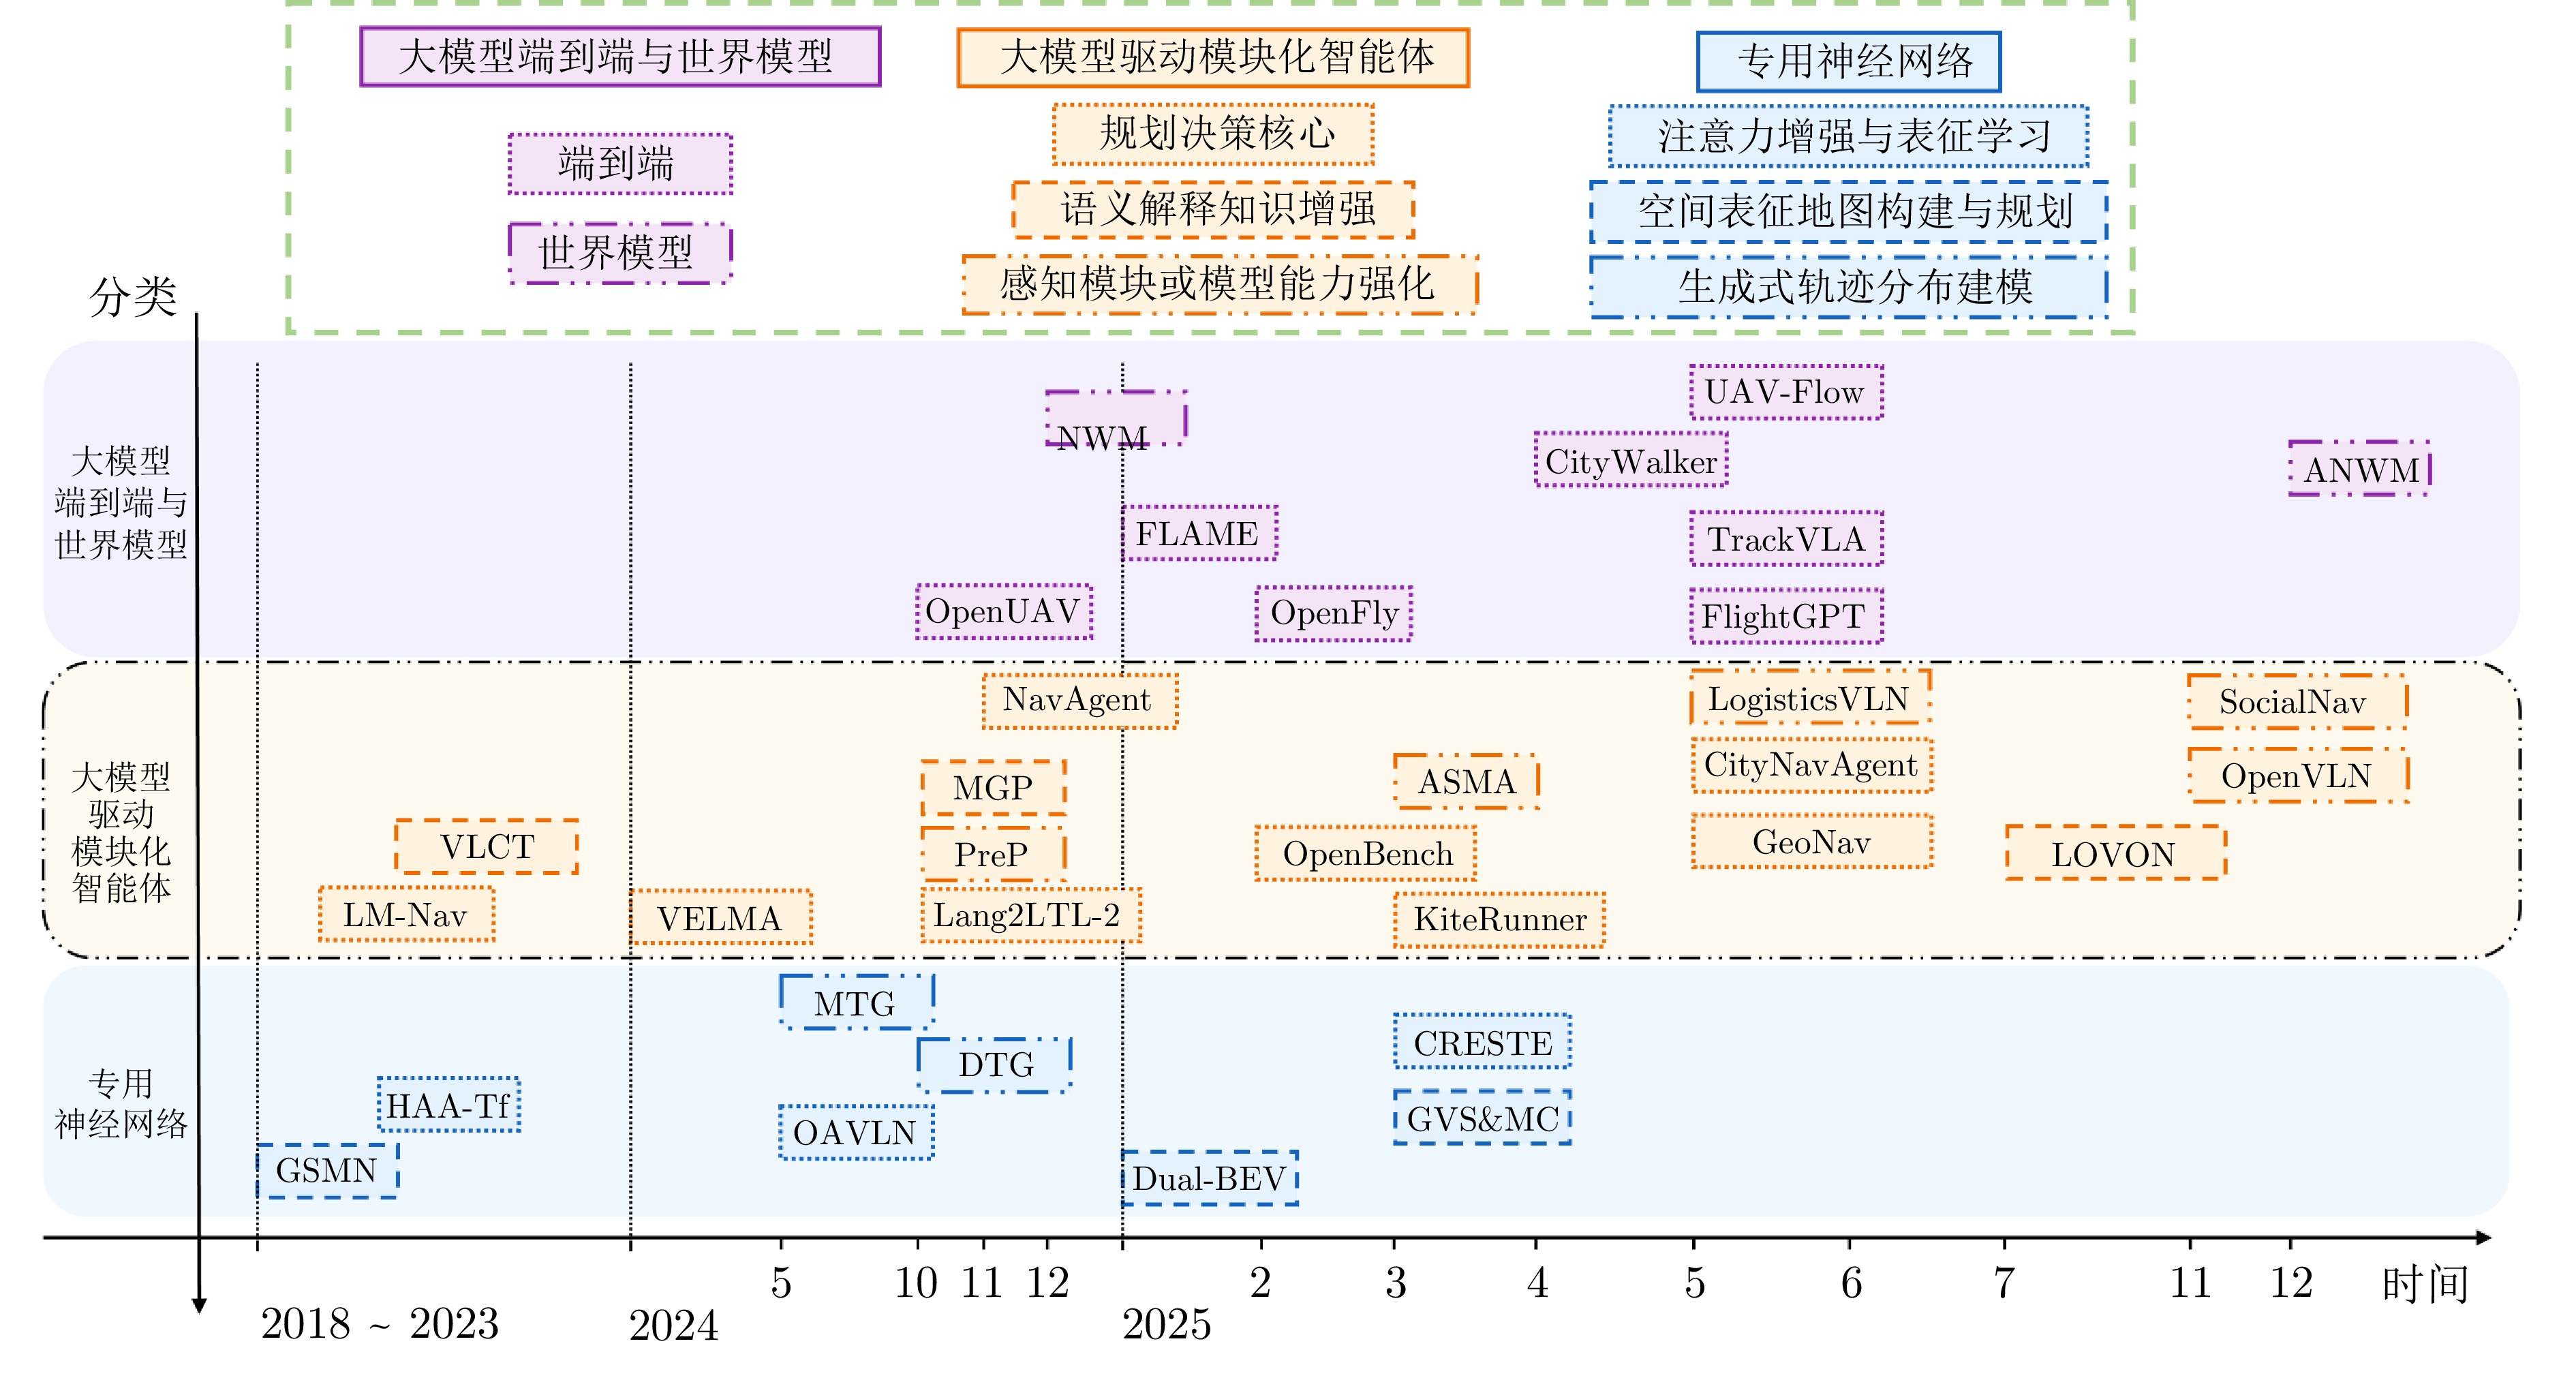
图 5 城市开放空间具身导航方法演进图
Fig. 5 Evolution diagram of embodied navigation methods for urban open space
表 1 城市开放空间具身智能仿真平台汇总
Table 1 Summary of simulation platforms for embodied intelligence in urban open space
模拟器 真实/虚拟 底层平台 场景数量 主要传感器 动作自由度 CityNav[20] 真实 Potree 2 RGB-D、位姿 4 CitySimu[19] 真实 卫星图、人类活动数据、地图 13 RGD、个体移动、交通信号 − EmbodiedCity[7] 真实 UE 5 1 RGB-D、位姿、语义 4 AeroVerse[8] 真实 UE 4 4 RGB-D、位姿、语义、雷达 4 OpenFly[21] 真实 UE 4、UE 5、GTA-V、Google Earth、3D GS 18 RGB-D、位姿、语义、雷达 4 AerialVLN[22] 虚拟 UE 4 25 RGB-D、位姿 4 OpenUAV[9] 虚拟 UE 4 22 RGB-D、位姿、雷达、GPS、IMU 6 UnrealZoo[28] 虚拟 UE 4、UE 5 100 RGB-D、位姿、灰度、Mask 3 ECCD[30] 虚拟 UE 4 60 RGB-D、语义、雷达 6 GRUTopia[26] 虚拟 Isaac Sim 100 k RGB-D、位姿 Various MetaUrban[24] 虚拟 PyBullet 13.8 k RGB-D、语义、雷达 Various UAV-ON[23] 虚拟 UE 14 RGB-D 4 FreeAskWorld[27] 虚拟 Unity 1 RGB-D、语义、BOX − Urban-Sim[25] 虚拟 Omniverse + PhysX 5 无限 RGB-D、雷达 Various SimWorld[29] 虚拟 UE 5 100+ RGB-D、语义、位姿 Various  下载: 导出CSV
表 2 城市开放空间具身感知推理数据集汇总
Table 2 Summary of datasets for embodied perception and reasoning tasks in urban open space
基准 年份 规模 来源 核心视觉模态 交互模式 核心任务 University- 1652 [31]2020 1.6 k个目标 真实 卫星图、无人机 静态 地理定位 GTA-UAV[36] 2024 148 k图像对 仿真 卫星图、无人机 静态 地理定位 DenseUAV[32] 2024 3 k个采样点 真实 卫星图、无人机 静态 地理定位 UAVD4L[33] 2024 2.5 M平方米 仿真 无人机 静态 地理定位 City-3DQA[39] 2024 450 k问答对 真实 点云 静态 场景理解 TUMTraffic-VideoQA[42] 2024 85 k问答对 真实 监控视频 静态 场景理解 Urban Video-Bench[43] 2024 5.2 k问答对 真实 + 仿真 无人机视频 静态 场景理解 CityBench[19] 2024 13个城市 真实 + 仿真 卫星图、街景图、交通流 静态 + 具身 地理定位 + 场景理解 + 具身交互 AnyVisLoc[34] 2025 18 k图像 真实 卫星图, 无人机 静态 地理定位 OrthoLoC[35] 2025 16.4 k图像 仿真 无人机 静态 地理定位 Open3DVQA[40] 2025 9 k问答对 模拟 无人机 静态 场景理解 AirCopBench[45] 2025 14.6 k+ 问答对 真实 + 仿真 多无人机视角 静态 场景理解 + 协同决策 UrBench[44] 2025 11.6 k+ 问答对 真实 卫星图、街景图 静态 场景理解 CityEQA[10] 2025 1412 个任务仿真 无人机 具身 具身交互 SpatialSky-Dataset[41] 2025 1 M个问答对 真实 无人机 静态 场景理解 CityCube[46] 2026 5 k+ 问答对 真实 + 仿真 无人机、街景图、卫星图 静态 场景理解 + 空间认知
下载: 导出CSV
表 3 城市开放空间具身导航任务数据集汇总
Table 3 Summary of datasets for embodied navigation tasks in urban open space
数据集名称 任务类型 年份 输入模态 数据收集方式 规模 AVDN[47] 对话导航 2023 RGB、位姿、文本 人工收集 $ \sim $3 k轨迹 AerialVLN[22] 指令导航 2023 RGB、深度图、文本 半自动 $ \sim $8 k轨迹 CityNav[20] 目标导航 2024 RGB、深度图、地图、文本 人工收集 $ \sim $32 k轨迹 Embodied VLN[7] 指令导航 2024 RGB、深度图、文本 人工收集 $ \sim $1.3 k轨迹 Embodied TaskPlanning[7] 导航规划 2024 RGB、深度图、文本 人工收集 $ \sim $10.6 k样本 OpenUAV-VLN[9] 指令导航 2024 RGB、深度图、位姿、文本 半自动 $ \sim $12 k轨迹 SkyAgent-Nav3k[8] 目标导航 2024 RGB、深度图、位姿、文本 人工收集 3 k样本 SkyAgent-Plan3k[8] 导航规划 2024 RGB、深度图、位姿、文本 人工收集 3 k样本 SkyAgent-Act3k[8] 指令导航 2024 RGB、深度图、位姿、文本 人工收集 3 k样本 FG-AVDN[49] 对话导航 2025 RGB、位姿、文本 半自动(自动标注 + 人工校对) $ \sim $3 k轨迹 UAV-ON[23] 目标导航 2025 RGB、深度图、文本 半自动 $ \sim $11 k任务 MapBench[48] 地图规划 2025 地图、文本 半自动(人工标注 + 算法生成) $ \sim $1.6 k问题 OpenFly[21] 指令导航 2025 RGB、文本 全自动生成 $ \sim $100 k轨迹 SocNav[50] 目标导航 2025 RGB、位姿、目标坐标 半自动(人工标注 + 自动轨迹) 7 M+ 样本 ANWM[51] 导航规划 2026 RGB、深度图、位姿 全自动生成 350 k+ 轨迹
下载: 导出CSV
-
[1] 沈甜雨, 陶子锐, 王亚东, 张庭祯, 刘宇航, 王兴霞, 等. 具身智能研究的关键问题: 自主感知、行动与进化. 自动化学报, 2025, 51(1): 43−71 doi: 10.16383/j.aas.c240364Shen Tian-Yu, Tao Zi-Rui, Wang Ya-Dong, Zhang Ting-Zhen, Liu Yu-Hang, Wang Xing-Xia, et al. Key problems of embodied intelligence research: Autonomous perception, action, and evolution. Acta Automatica Sinica, 2025, 51(1): 43−71 doi: 10.16383/j.aas.c240364 [2] 孙长银, 袁心, 王远大, 柳文节. 具身智能自主无人系统技术. 自动化学报, 2025, 51(4): 762−777 doi: 10.16383/j.aas.c240456Sun Chang-Yin, Yuan Xin, Wang Yuan-Da, Liu Wen-Zhang. Embodied intelligence autonomous unmanned systems technology. Acta Automatica Sinica, 2025, 51(4): 762−777 doi: 10.16383/j.aas.c240456 [3] 王文晟, 谭宁, 黄凯, 张雨浓, 郑伟诗, 孙富春. 基于大模型的具身智能系统综述. 自动化学报, 2025, 51(1): 1−19 doi: 10.16383/j.aas.c240542Wang Wen-Sheng, Tan Ning, Huang Kai, Zhang Yu-Nong, Zheng Wei-Shi, Sun Fu-Chun. Embodied intelligence systems based on large models: A survey. Acta Automatica Sinica, 2025, 51(1): 1−19 doi: 10.16383/j.aas.c240542 [4] 刘华平, 郭迪, 孙富春, 张新钰. 基于形态的具身智能研究: 历史回顾与前沿进展. 自动化学报, 2023, 49(6): 1131−1154 doi: 10.16383/j.aas.c220564Liu Hua-Ping, Guo Di, Sun Fu-Chun, Zhang Xin-Yu. Morphology-based embodied intelligence: Historical retrospect and research progress. Acta Automatica Sinica, 2023, 49(6): 1131−1154 doi: 10.16383/j.aas.c220564 [5] Xu F, Zhang J, Gao C, Liu P, Feng J, Li Y. Towards a foundational platform for generative agents in simulated city environment. PLOS Complex Systems, 2026, 3(3): e0000093 doi: 10.1371/journal.pcsy.0000093 [6] 邓三鹏, 张香玲, 王凯, 曹宇聪, 马传庆. 具身智能机器人关键技术及发展趋势研究. 装备制造技术, 2024(6): 2−10 doi: 10.3969/j.issn.1672-545X.2024.06.003Deng San-Peng, Zhang Xiang-Ling, Wang Kai, Cao Yu-Cong, Ma Chuan-Qing. Research on key technologies and development trends of embodied intelligence robots. Equipment Manufacturing Technology, 2024(6): 2−10 doi: 10.3969/j.issn.1672-545X.2024.06.003 [7] Gao C, Zhao B, Zhang W, Mao J, Zhang J, Zheng Z, et al. EmbodiedCity: A benchmark platform for embodied agent in real-world city environment. arXiv preprint arXiv: 2410.09604, 2024 [8] Yao F, Yue Y, Liu Y, Wang Z, Jin L, Zhao B, et al. AeroVerse: UAV-agent benchmark suite for simulating, pre-training, finetuning, and evaluating aerospace embodied foundation models. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2026. DOI: 10.1109/TPAMI.2026.3697634 [9] Wang X, Yang D, Wang Z, Kwan H, Chen J, Wu W, et al. Towards realistic UAV vision-language navigation: Platform, benchmark, and methodology. In: Proceedings of the 2025 International Conference on Learning Representations (ICLR), 2025 [10] Zhao Y, Xu K, Zhu Z, Hu Y, Zheng Z, Chen Y, et al. CityEQA: A hierarchical LLM agent on embodied question answering benchmark in city space. In: Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, 2025. 12465−12480 [11] Liu Y, Chen W, Bai Y, Liang X, Li G, Gao W. Aligning cyber space with physical world: A comprehensive survey on embodied AI. IEEE/ASME Transactions on Mechatronics, 2025, 30(6): 7253−7274 doi: 10.1109/TMECH.2025.3574943 [12] Lin J, Gao H, Feng X, Xu R, Wang C, Zhang M, et al. Advances in embodied navigation using large language models: A survey. arXiv preprint arXiv: 2311.00530, 2025 [13] Li Z, Yu H, Ding Y, Li Y, He Y, Akhtar N. Embodied intelligence for 3D understanding: A survey on 3D scene question answering. Information Fusion, 2026, 127: 103624 doi: 10.1016/j.inffus.2025.103624 [14] Tian Y, Lin F, Li Y, Zhang T, Zhang Q, Fu X, et al. UAVs meet LLM: Overviews and perspectives towards agentic low-altitude mobility. Information Fusion, 2025, 122: 103158 doi: 10.1016/j.inffus.2025.103158 [15] Farea A, Emmert-Streib F. Understanding question-answering systems: Evolution, applications, trends, and challenges. Engineering Applications of Artificial Intelligence, 2025, 156: 110997 doi: 10.1016/j.engappai.2025.110997 [16] Li Y, Liu Z, Li Z, Zhang X, Xu Z, Chen X, et al. Perception, reason, think, and plan: A survey on large multimodal reasoning models. arXiv preprint arXiv: 2505.04921, 2025 [17] Feng J, Zeng J, Long Q, Chen H, Zhao J, Xi Y, et al. A survey of large language model-powered spatial intelligence across scales: Advances in embodied agents, smart cities, and earth science. arXiv preprint arXiv: 2504.09848, 2025 [18] Han J, Ning Y, Yuan Z, Ni H, Liu F, Lyu T, et al. Large language model powered intelligent urban agents: Concepts, capabilities, and applications. arXiv preprint arXiv: 2507.00914, 2025 [19] Feng J, Zhang J, Liu T, Zhang X, Ouyang T, Yan J, et al. CityBench: Evaluating the capabilities of large language models for urban tasks. In: Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining, 2025 [20] Lee J, Miyanishi T, Kurita S, Sakamoto K, Azuma D, Matsuo Y, et al. CityNav: A large-scale dataset for real-world aerial navigation. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025. 5912−5922 [21] Gao Y, Li C, You Z, Liu J, Zhen L, Chen P, et al. OpenFly: A versatile toolchain and large-scale benchmark for aerial vision-language navigation. In: Proceedings of the International Conference on Learning Representations (ICLR), 2025 [22] Liu S, Zhang H, Qi Y, Wang P, Zhang Y, Wu Q. AerialVLN: Vision-and-language navigation for UAVs. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2023. 15384−15394 [23] Xiao J, Sun Y, Shao Y, Gan B, Liu R, Wu Y, et al. UAV-ON: A benchmark for open-world object goal navigation with aerial agents. In: Proceedings of the 33rd ACM International Conference on Multimedia, 2025. 13023−13029 [24] Wu W, He H, He J, Wang Y, Duan C, Liu Z, et al. MetaUrban: An embodied AI simulation platform for urban micromobility. In: Proceedings of the International Conference on Learning Representations (ICLR), 2025 [25] Wu W, He H, Zhang C, He J, Zhao S Z, Gong R, et al. Towards autonomous micromobility through scalable urban simulation. In: Proceedings of the 2025 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025. 27553−27563 [26] Wang H, Chen J, Huang W, Ben Q, Wang T, Mi B, et al. GRUtopia: Dream general robots in a city at scale. arXiv preprint arXiv: 2407.10943, 2024 [27] Peng Y, Pan Y, He X, Yang J, Yin X, Wang H, et al. FreeAskWorld: An interactive and closed-loop simulator for human-centric embodied AI. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2026, 40(2): 926−934 [28] Zhong F, Wu K, Wang C, Chen H, Ci H, Li Z. UnrealZoo: Enriching photo-realistic virtual worlds for embodied AI. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025. 5769−5779 [29] Ren J, Zhuang Y, Ye X, Mao L, He X, Shen J, et al. SimWorld: An open-ended realistic simulator for autonomous agents in physical and social worlds. In: Advances in Neural Information Processing Systems (NeurIPS), 2025 [30] Long R, Wang Y, Wan J, Deng X, Zhu X, Guan W, et al. Embodied crowd counting. In: Advances in Neural Information Processing Systems (NeurIPS), 2025 [31] Zheng Z, Zheng L, Garrett M, Yang Y, Xu M, Shen Y. Dual-path convolutional image-text embeddings with instance loss. ACM Transactions on Multimedia Computing, Communications, and Applications, 2020, 16(2): 1−23 doi: 10.1145/3383184 [32] Dai M, Zheng E, Feng Z, Qi L, Zhuang J, Yang W. Vision-based UAV self-positioning in low-altitude urban environments. IEEE Transactions on Image Processing, 2024, 33: 493−508 doi: 10.1109/TIP.2023.3346279 [33] Wu R, Cheng X, Zhu J, Liu X, Zhang M, Yan S. UAVD4L: A large-scale dataset for UAV 6-DoF localization. In: Proceedings of the 2024 International Conference on 3D Vision (3DV), 2024. 1574−1583 [34] Ye Y, Teng X, Chen S, Liu L, Wang K, Song X, et al. Exploring the best way for UAV visual localization under low-altitude multi-view observation condition: A benchmark. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Findings, 2026. 1731−1741 [35] Dhaouadi O, Marin R, Meier J, Kaiser J, Cremers D. OrthoLoC: UAV 6-DoF localization and calibration using orthographic geodata. In: Advances in Neural Information Processing Systems (NeurIPS), 2025 [36] Ji Y, He B, Tan Z, Wu L. Game4loc: A UAV geo-localization benchmark from game data. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2025, 39(4): 3913−3921 [37] Hao X, Chen W, Yan Y, Zhong S, Wang K, Wen Q, et al. UrbanVLP: Multi-granularity vision-language pretraining for urban socioeconomic indicator prediction. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2025, 39(27): 28061−28069 [38] Wang J, Zheng Z, Chen Z, Ma A, Zhong Y. EarthVQA: Towards queryable Earth via relational reasoning-based remote sensing visual question answering. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2024, 38(6): 5481−5489 [39] Sun P, Song Y, Liu X, Yang X, Wang Q, Li T, et al. 3D question answering for city scene understanding. In: Proceedings of the 32nd ACM International Conference on Multimedia, 2024. 2156−2165 [40] Zhang W, Zhou Z, Zeng X, Liu X, Fang J, Gao C, et al. Open3D-VQA: A benchmark for embodied spatial concept reasoning with multimodal large language model in open space. In: Proceedings of the 33rd ACM International Conference on Multimedia, 2025. 12784−12791 [41] Zhang L, Zhang Y, Li H, Fu H, Tang Y, Ye H, et al. Is your VLM sky-ready? A comprehensive spatial intelligence benchmark for UAV navigation. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026. 25904−25913 [42] Zhou X, Larintzakis K, Guo H, Zimmer W, Liu M, Cao H, et al. TUMTraf VideoQA: Dataset and benchmark for unified spatio-temporal video understanding in traffic scenes. In: Proceedings of the 42nd International Conference on Machine Learning (ICML), 2025. 78786−78811 [43] Zhao B, Fang J, Dai Z, Wang Z, Zha J, Zhang W, et al. UrbanVideo-bench: Benchmarking vision-language models on embodied intelligence with video data in urban spaces. In: Findings of the Association for Computational Linguistics: ACL 2025, 2025. 32400−32423 [44] Zhou B, Yang H, Chen D, Ye J, Bai T, Yu J, et al. UrBench: A comprehensive benchmark for evaluating large multimodal models in multi-view urban scenarios. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2025, 39(13): 10707−10715 [45] Zha J, Fan Y, Zhang T, Chen G, Chen Y, Gao C, et al. AirCopBench: A benchmark for multi-drone collaborative embodied perception and reasoning. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2026, 40(2): 1507−1515 [46] Xu H, Hu Y, Zhu Z, Gao C, Wang Z, Rao J, et al. CityCube: Benchmarking cross-view spatial reasoning on vision-language models in urban environments. In: Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 2026. 9190−9215 [47] Fan Y, Chen W, Jiang T, Zhou C, Zhang Y, Wang X E. Aerial vision-and-dialog navigation. In: Findings of the Association for Computational Linguistics: ACL 2023, 2023. 3043−3061 [48] Hao X, Wei M, Yang Y, Zhao H, Zhang H, Zhou Y, et al. Is your HD map constructor reliable under sensor corruptions. In: Advances in Neural Information Processing Systems (NeurIPS), 2024 [49] Su Y, An D, Chen K, Yu W, Ning B, Ling Y, et al. Learning fine-grained alignment for aerial vision-dialog navigation. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2025, 39(7): 7060−7068 [50] Chen Z, Sun M, Liu L, Guo Y, Chu Z, Luo M, et al. SocialNav: Training human-inspired foundation model for socially-aware embodied navigation. In: Proceedings of the 2026 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026. 28796−28806 [51] Zhang W, Tang P, Zeng X, Man F, Yu S, Dai Z, et al. Aerial world model for long-horizon visual generation and navigation in 3D space. arXiv preprint arXiv: 2512.21887, 2025 [52] Ji Y, Zhu Z, Zhao Y, Liu B, Gao C, Zhao Y, et al. Towards autonomous UAV visual object search in city space: Benchmark and agentic methodology. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2026, 40(22): 18342−18350 [53] Mi L, Béchaz M, Chen Z, Bosselut A, Tuia D. GeoExplorer: Active geo-localization with curiosity-driven exploration. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), 2025. 6122−6131 [54] Cai Z, Cardenas C R, Leo K, Zhang C, Backman K, Li H, et al. NEUSIS: A compositional neuro-symbolic framework for autonomous perception, reasoning, and planning in complex UAV search missions. IEEE Robotics and Automation Letters, 2025, 10(9): 9502−9509 doi: 10.1109/LRA.2025.3592098 [55] Jiang X, Liu T, Liu L, Liu Z, Liu Y. UEVAVD: A dataset for developing UAV's eye view active object detection. IEEE Robotics and Automation Letters, 2025, 10(6): 6272−6279 doi: 10.1109/LRA.2025.3566604 [56] Sun Y, Qiu Y, Aoki Y, Kataoka H. Guided by the way: The role of on-the-route objects and scene text in enhancing outdoor navigation. In: Proceedings of the 2024 IEEE International Conference on Robotics and Automation (ICRA), 2024. 5198−5204 [57] Zhang A, Sikchi H, Zhang A, Biswas J. CREStE: Scalable mapless navigation with internet scale priors and counterfactual guidance. In: Proceedings of Robotics: Science and Systems (RSS), 2025 [58] Blukis V, Brukhim N, Bennett A, Knepper R A, Artzi Y. Following high-level navigation instructions on a simulated quadcopter with imitation learning. In: Proceedings of Robotics: Science and Systems (RSS), 2018 [59] Zhang J, Dong H, Yang J, Liu J, Huang S, Li K, et al. Dual-BEV Nav: Dual-layer BEV-based heuristic path planning for robotic navigation in unstructured outdoor environments. In: Proceedings of the 2025 IEEE International Conference on Robotics and Automation (ICRA), 2025. 8872−8879 [60] Zhao G, Li G, Pan J, Yu Y. Aerial vision-and-language navigation with grid-based view selection and map construction. arXiv preprint arXiv: 2503.11091, 2025 [61] Liang J, Gao P, Xiao X, Sathyamoorthy A J, Elnoor M, Lin M C, et al. MTG: Mapless trajectory generator with traversability coverage for outdoor navigation. In: Proceedings of the 2024 IEEE International Conference on Robotics and Automation (ICRA), 2024. 2396−2402 [62] Liang J, Payandeh A, Song D, Xiao X, Manocha D. DTG: Diffusion-based trajectory generation for mapless global navigation. In: Proceedings of the 2024 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2024. 5340−5347 [63] Shah D, Osiński B, Ichter B, Levine S. LM-Nav: Robotic navigation with large pre-trained models of language, vision, and action. In: Proceedings of the 6th Annual Conference on Robot Learning (CoRL), 2022. 492−504 [64] Wang J, Huo D, Xu Z, Shi Y, Yan Y, Wang Y, et al. OpenBench: A new benchmark and baseline for semantic navigation in smart logistics. In: Proceedings of the 2025 IEEE International Conference on Robotics and Automation (ICRA), 2025 [65] Zhang W, Gao C, Yu S, Peng R, Zhao B, Zhang Q, et al. CityNavAgent: Aerial vision-and-language navigation with hierarchical semantic planning and global memory. In: Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 2025. 31292−31309 [66] Zeng Q, Yang Q, Dong S, Du H, Zheng L, Xu F, et al. Perceive, reflect, and plan: Designing LLM agent for goal-directed city navigation without instructions. arXiv preprint arXiv: 2408.04168, 2024 [67] Liu J X, Shah A, Konidaris G, Tellex S, Paulius D. Lang2LTL-2: Grounding spatiotemporal navigation commands using large language and vision-language models. In: Proceedings of the 2024 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2024. 2325−2332 [68] Schumann R, Zhu W, Feng W, Fu T J, Riezler S, Wang W Y. VELMA: Verbalization embodiment of LLM agents for vision and language navigation in street view. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2024, 38(17): 18924−18933 [69] Gao Y, Wang Z, Jing L, Wang D, Li X, Zhao B. Aerial vision-and-language navigation via semantic-topo-metric representation guided LLM reasoning. arXiv preprint arXiv: 2410.08500, 2024 [70] Liu Y, Yao F, Yue Y, Xu G, Sun X, Fu K. NavAgent: Multi-scale urban street view fusion for UAV embodied vision-and-language navigation. arXiv preprint arXiv: 2411.08579, 2024 [71] Huang S, Shi C, Yang J, Dong H, Mi J, Li K, et al. KiteRunner: Language-driven cooperative local-global navigation policy with UAV mapping in outdoor environments. In: Proceedings of the 2025 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2025. 18512−18519 [72] Xu H, Hu Y, Gao C, Zhu Z, Zhao Y, Yin Q. GeoNav: Empowering MLLM with dual-scale geospatial reasoning for language-goal aerial navigation. Pattern Recognition, 2026, 177: 113365 doi: 10.1016/j.patcog.2026.113365 [73] Chen Z, Li J, Fukumoto F, Liu P, Suzuki Y. Vision-language navigation for quadcopters with conditional transformer and prompt-based text rephraser. In: Proceedings of the 5th ACM International Conference on Multimedia in Asia, 2023. 76 [74] Peng D, Cao J, Zhang Q, Ma J. LOVON: Legged open-vocabulary object navigator. IEEE/ASME Transactions on Mechatronics, 2026 [75] Sanyal S, Roy K. ASMA: An adaptive safety margin algorithm for vision-language drone navigation via scene-aware control barrier functions. IEEE Robotics and Automation Letters, 2025, 10(9): 9232−9239 doi: 10.1109/lra.2025.3592138 [76] Zhang X, Tian Y, Lin F, Liu Y, Ma J, Szatmáry K S, et al. LogisticsVLN: Vision-language navigation for low-altitude terminal delivery based on agentic UAVs. In: Proceedings of the 2025 IEEE 28th International Conference on Intelligent Transportation Systems (ITSC), 2025. 4437−4442 [77] Song D, Liang J, Xiao X, Manocha D. VL-TGS: Trajectory generation and selection using vision language models in mapless outdoor environments. IEEE Robotics and Automation Letters, 2025, 10(6): 5791−5798 doi: 10.1109/LRA.2025.3559822 [78] Lin P, Sun G, Liu C, Li F, Ren W, Cong Y. OpenVLN: Open-world aerial vision-language navigation. arXiv preprint arXiv: 2511.06182, 2025 [79] 李浩然, 陈宇辉, 崔文博, 刘卫恒, 刘锴, 周明才, 等. 面向具身操作的视觉−语言−动作模型综述. 自动化学报, 2026, 52(1): 18−51 doi: 10.16383/j.aas.c250394Li Hao-Ran, Chen Yu-Hui, Cui Wen-Bo, Liu Wei-Heng, Liu Kai, Zhou Ming-Cai, et al. Survey of vision-language-action models for embodied manipulation. Acta Automatica Sinica, 2026, 52(1): 18−51 doi: 10.16383/j.aas.c250394 [80] Xu Y, Pan Y, Liu Z, Wang H. FLAME: Learning to navigate with multimodal LLM in urban environments. In: Proceedings of the AAAI Conference on Artificial Intelligence, 2025. 9005−9013 [81] Wang X, Yang D, Liao Y, Zheng W, Dai B, Wu W, et al. UAV-flow colosseo: A real-world benchmark for flying-on-a-word UAV imitation learning. In: Advances in Neural Information Processing Systems (NeurIPS), 2025 [82] Wang S, Zhang J, Li M, Liu J, Li A, Wu K, et al. TrackVLA: Embodied visual tracking in the wild. In: Proceedings of the 9th Conference on Robot Learning (CoRL), 2025. 4139−4164 [83] Cai H, Dong J, Tan J, Deng J, Li S, Gao Z, et al. FlightGPT: Towards generalizable and interpretable UAV vision-and-language navigation with vision-language models. In: Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, 2025. 6659−6676 [84] Liu X, Li J, Jiang Y, Sujay N, Yang Z, Zhang J, et al. CityWalker: Learning embodied urban navigation from web-scale videos. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025. 6875−6885 [85] Bar A, Zhou G, Tran D, Darrell T, LeCun Y. Navigation world models. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025. 15791−15801 [86] Hutchinson M, Oh H, Chen W H. Entrotaxis as a strategy for autonomous search and source reconstruction in turbulent conditions. Information Fusion, 2018, 42: 179−189 doi: 10.1016/j.inffus.2017.10.009 [87] Lin H, Yang X, Wen G, Zheng W X. Fast UAV object-searching in large-scale and complex environments. IEEE Transactions on Cybernetics, 2025, 55(6): 2993−3004 doi: 10.1109/TCYB.2025.3556744 [88] Dang T, Papachristos C, Alexis K. Autonomous exploration and simultaneous object search using aerial robots. In: Proceedings of the 2018 IEEE Aerospace Conference, 2018. 1−7 [89] Wang C, Cheng J, Chi W, Yan T, Meng M Q H. Semantic-aware informative path planning for efficient object search using mobile robot. IEEE Transactions on Systems, Man, and Cybernetics: Systems, 2021, 51(8): 5230−5243 doi: 10.1109/TSMC.2019.2946646 [90] Meera A A, Popović M, Millane A, Siegwart R. Obstacle-aware adaptive informative path planning for UAV-based target search. In: Proceedings of the 2019 International Conference on Robotics and Automation (ICRA), 2019. 718−724 [91] Zheng K, Bayazit D, Mathew R, Pavlick E, Tellex S. Spatial language understanding for object search in partially observed city-scale environments. In: Proceedings of the 30th IEEE International Conference on Robot & Human Interactive Communication (RO-MAN), 2021. 315−322 [92] Döschl B, Kiam J J. Say-REAPEx: An LLM-modulo UAV online planning framework for search and rescue. In: Proceedings of the 2nd CoRL Workshop on Learning Effective Abstractions for Planning, 2024 -

 下载:

计量
- 文章访问数: 16
- HTML全文浏览量: 6
- 被引次数: 0
