

Multi-Dimensional Automated Essay Scoring Based on Disentangled Representation and Collaborative Scoring Mechanism
-
摘要: 多维度作文评分旨在从多个评分维度对作文质量进行细粒度评估, 从而实现更加全面和客观的自动化评价. 现有方法大多基于共享预训练编码器提取统一文本表示, 并在此基础上分别预测各维度得分. 然而, 这种共享表示往往混合了不同评分维度的信息, 导致维度间特征相互干扰, 削弱模型对特定维度差异的感知能力, 进而限制整体评分性能的提升. 为解决上述问题, 提出了一种基于“解耦−协作”机制的多维度特征学习框架, 旨在通过增强维度特征的独立建模能力与跨维度评分协同能力. 首先, 针对共享编码器所产生的特征过度耦合问题, 通过引入大语言模型生成维度特定的质量描述, 并将其作为外部知识信号引导维度表征学习, 从而促进共享表示的解耦. 其次, 为提高多任务学习过程中评分维度间的跨维度协同评分能力, 进一步引入促进评分协作的混合专家机制, 通过动态路由实现维度间的可控信息交互, 在保持维度独立性的同时充分利用跨维度相关信息. 在公开数据集上的实验结果表明, 所提出方法增强了模型对维度特征差异的感知能力, 在整体评分及不同维度的评分上均取得了优于现有方法的性能表现.Abstract: Multi-trait essay scoring aims to evaluate essay quality from multiple scoring dimensions, thereby enabling a more comprehensive and objective automated assessment. Existing approaches rely on a shared pre-trained encoder to extract unified textual representations, upon which trait-specific scores are predicted separately. Such shared representations from different scoring traits are often entangled, leading to inner-trait interference. This interference weakens the model's ability to capture trait-specific distinctions and consequently limits scoring performance. To address these issues, this paper proposes a multi-trait representation learning framework based on a disentanglement-collaboration mechanism, designed to enhance both the independent modeling of trait-specific features and cross-trait collaborative scoring capability. First, to mitigate the over-entanglement problem, this paper incorporates large language models to generate trait-specific quality descriptions. These descriptions serve as external knowledge signals to guide trait-level representation learning, thereby promoting the disentanglement of shared representations. Second, to improve cross-trait collaborative scoring ability in the multi-task learning setting, a mixture-of-experts mechanism that facilitates scoring collaboration is introduced. This approach enables controlled information interaction across traits, effectively leveraging inter-trait correlations while preserving trait independence. Experimental results on public benchmark datasets demonstrate that the proposed method enhances the model's sensitivity to trait-specific feature differences and achieves superior performance over existing approaches in both overall scoring and multiple traits.1) †王炯和吴浩的贡献相同
-
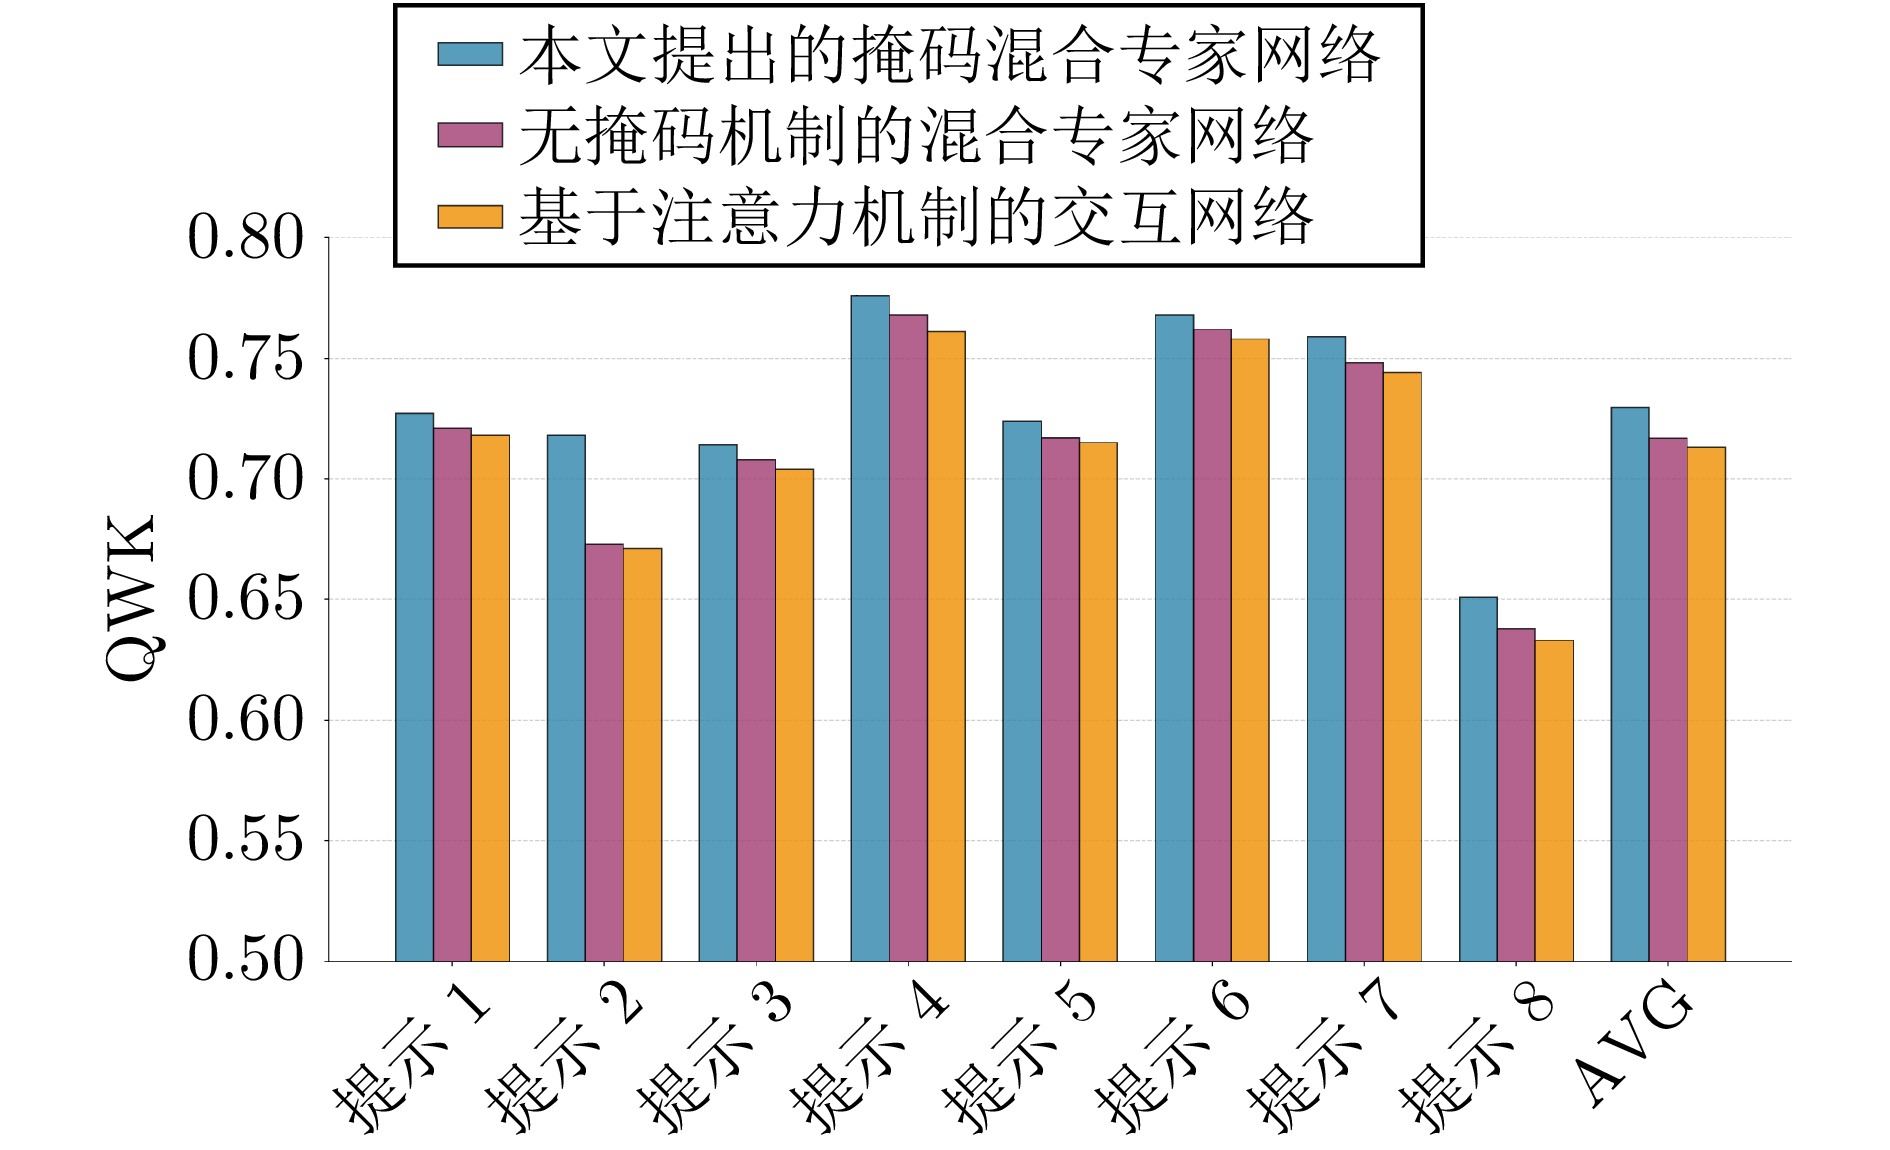
图 4 不同跨评分维度协同网络的性能比较实验
Fig. 4 Performance comparison of different cross-dimension collaborative networks
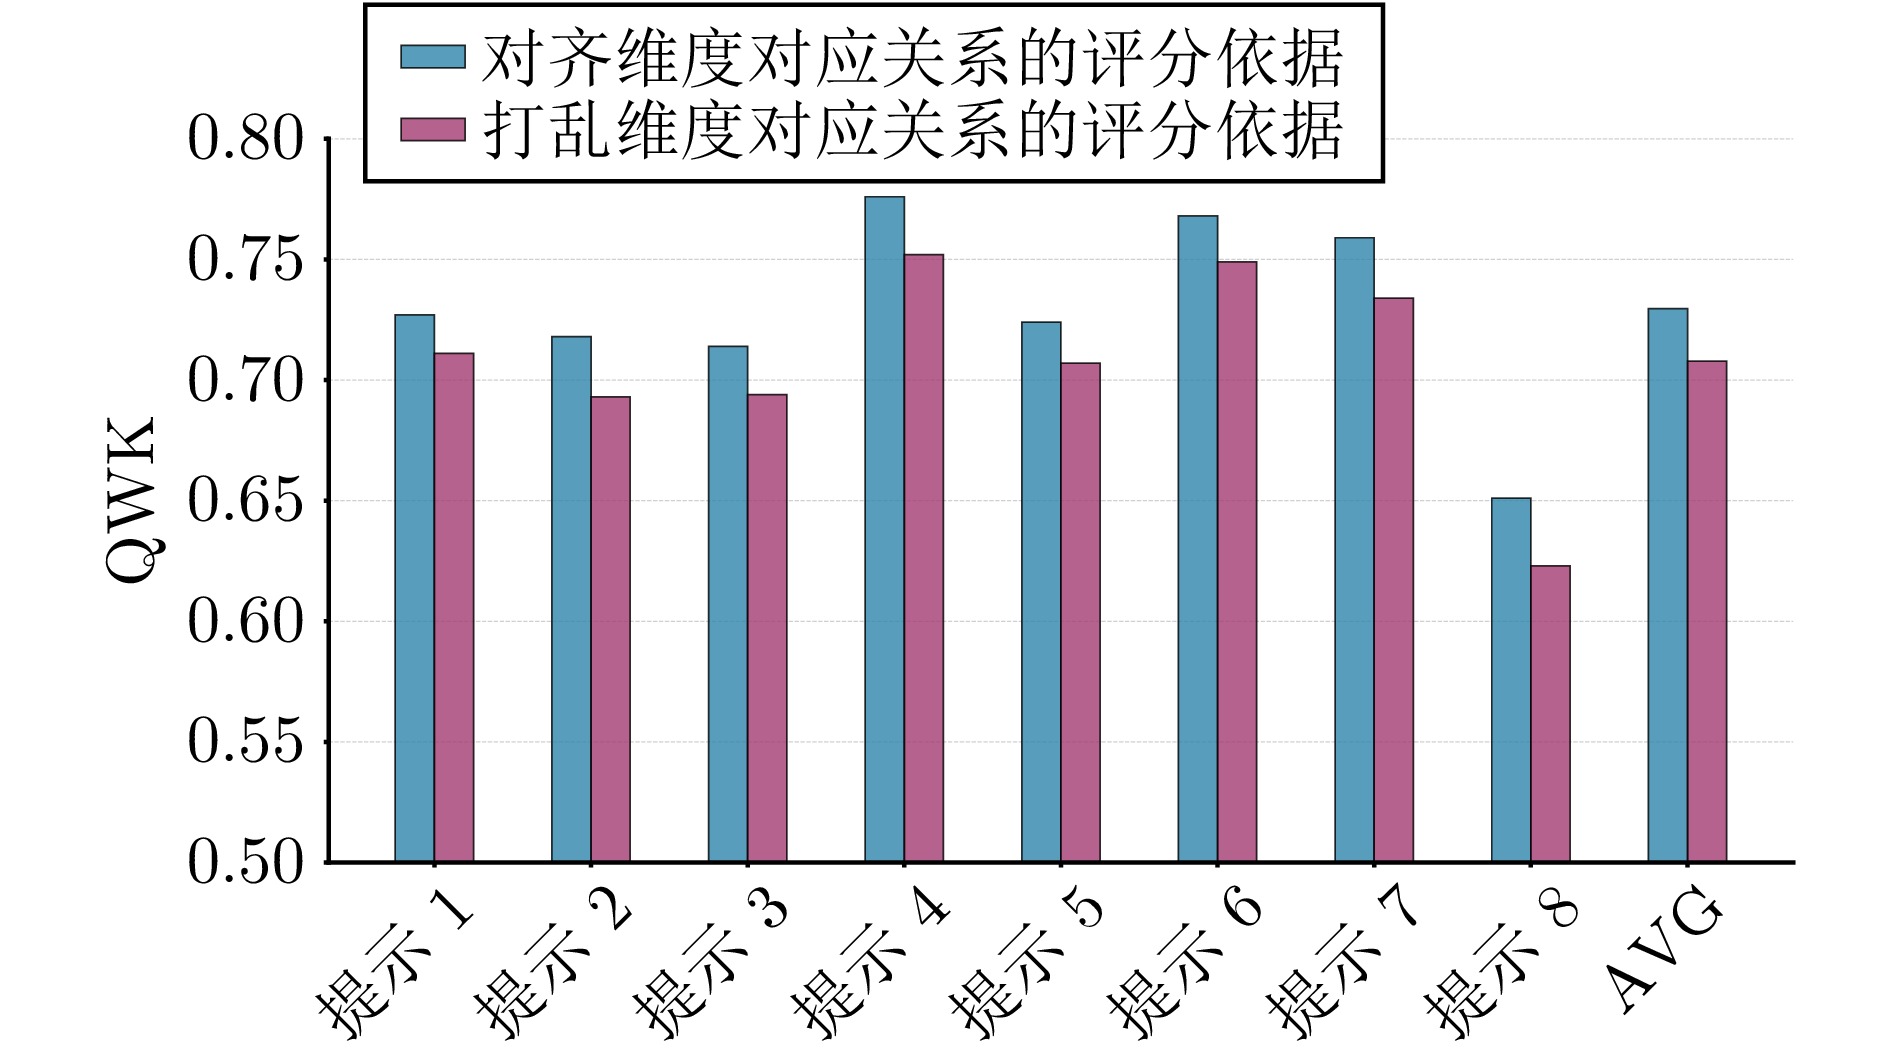
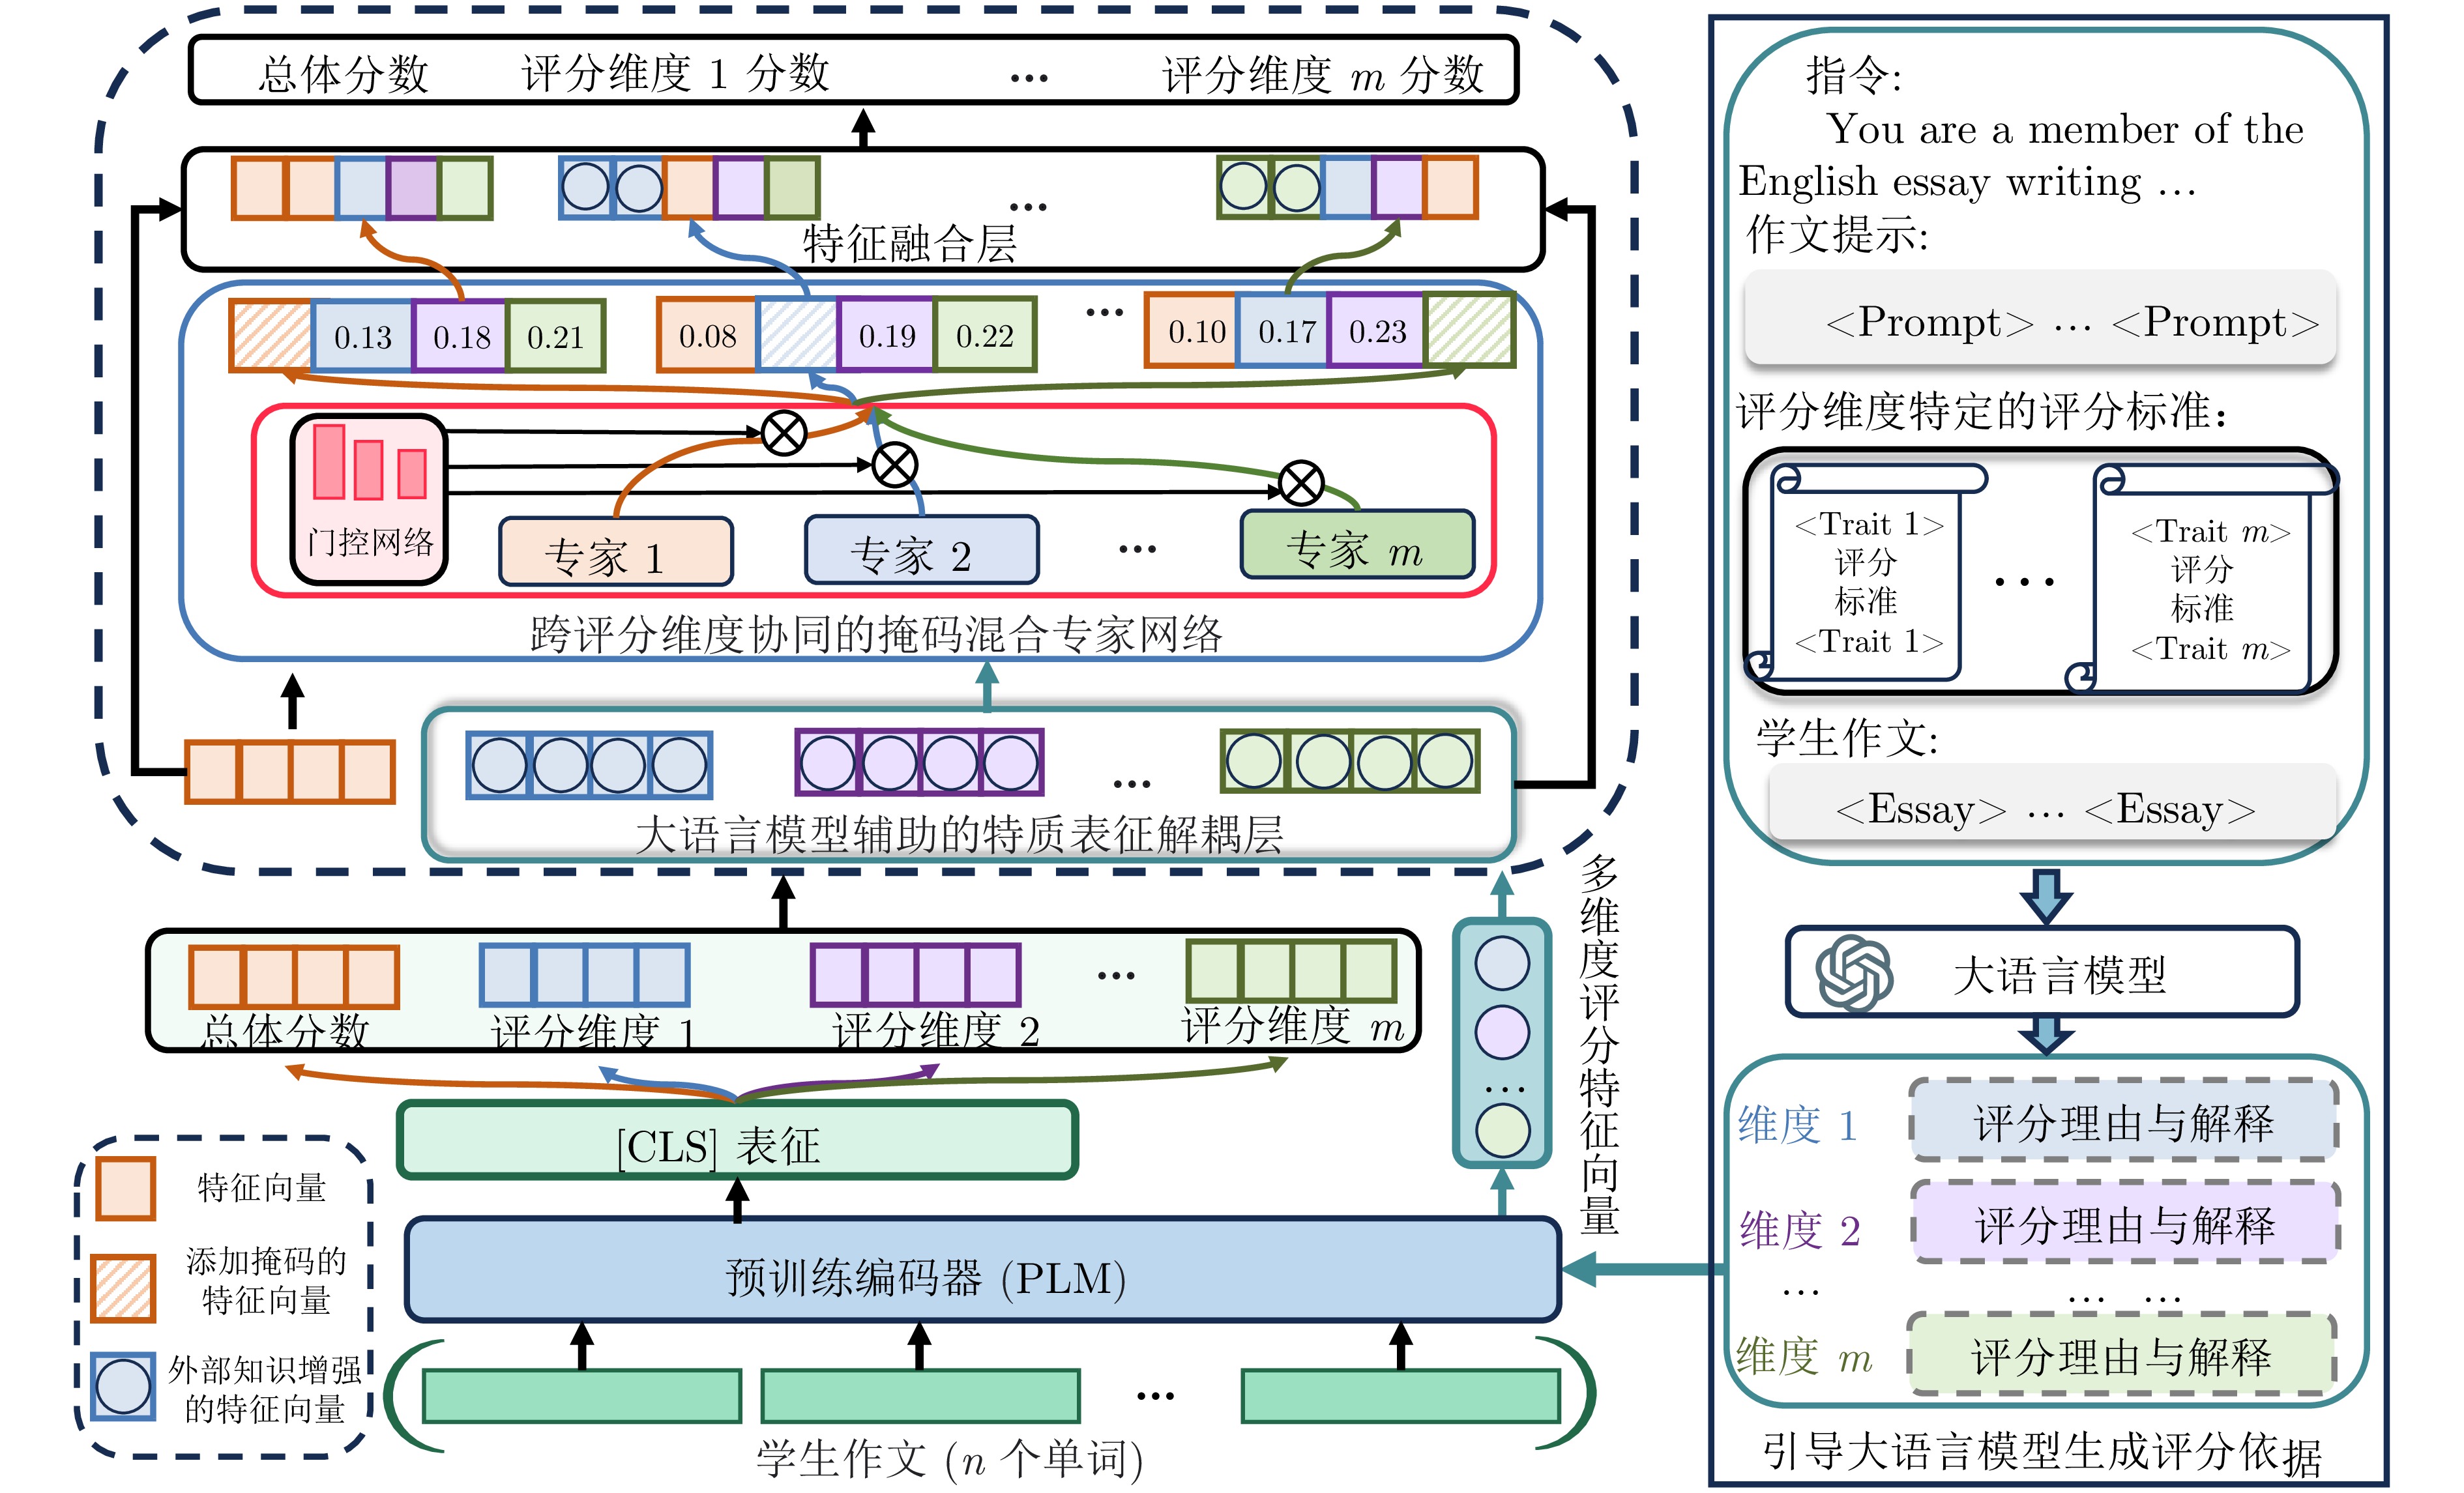
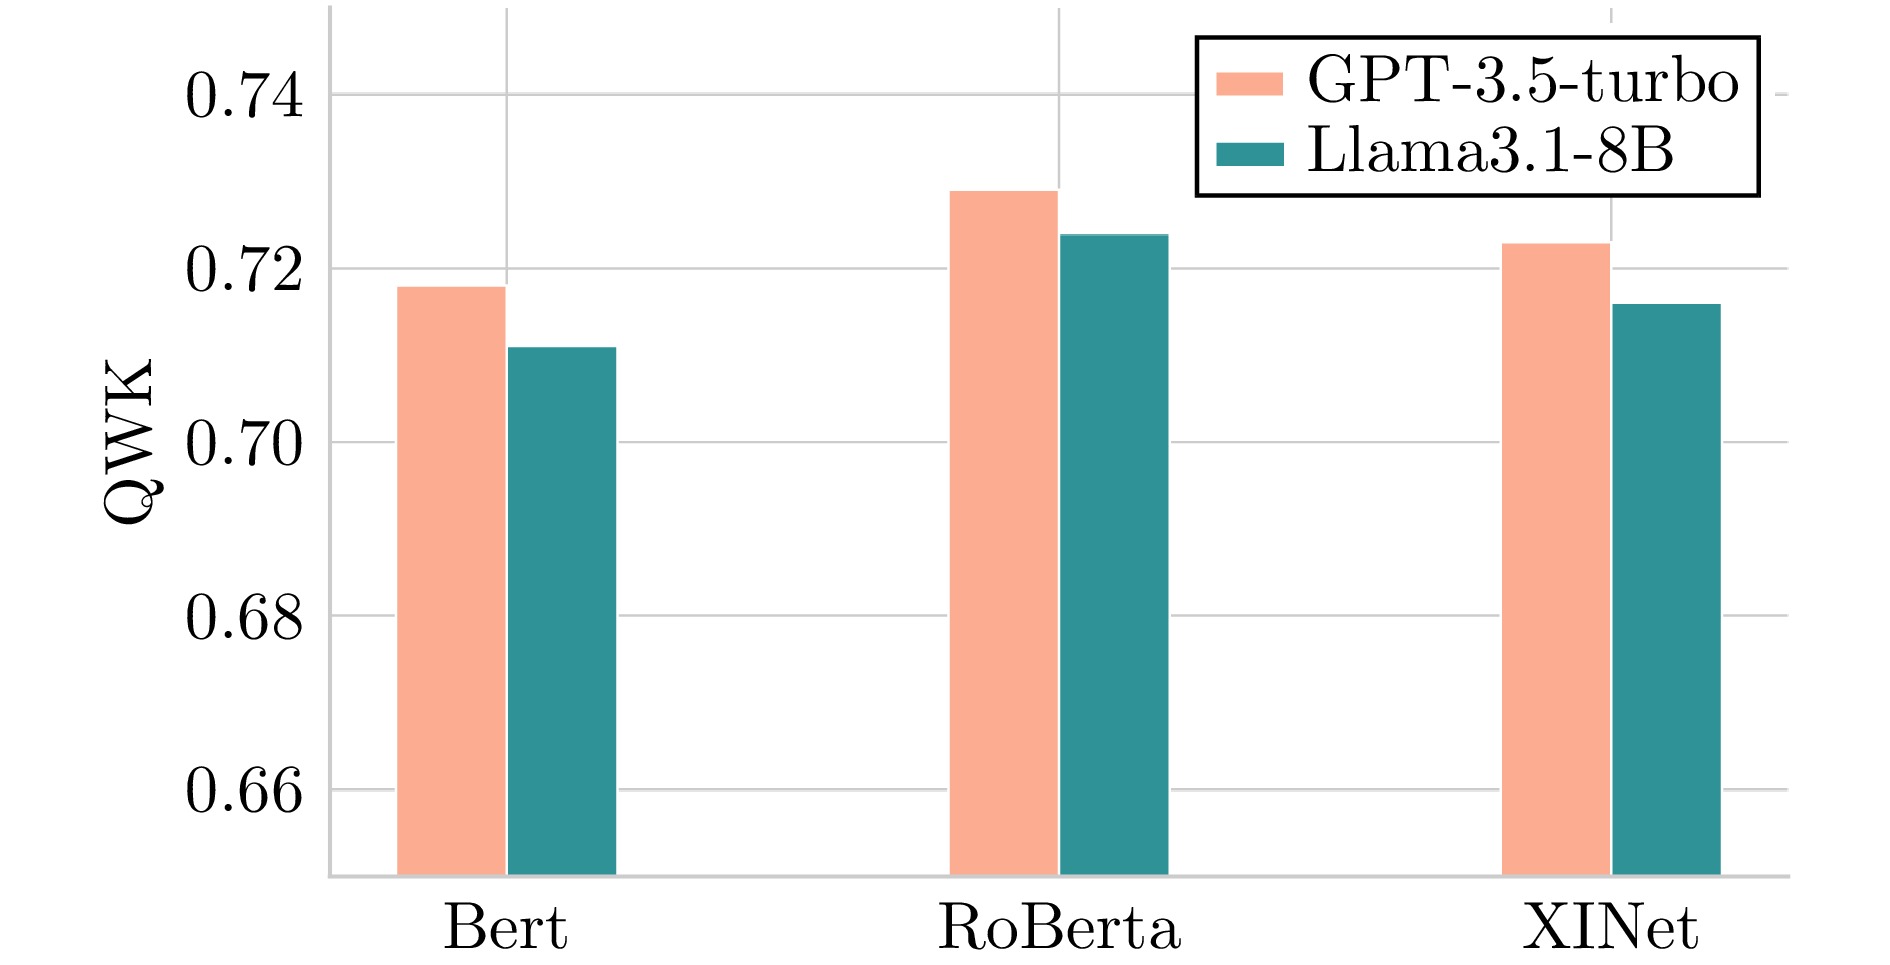
图 5 LLM生成评分依据的有效性分析实验
Fig. 5 Experimental results on the validity analysis of scoring rationals generated by LLMs
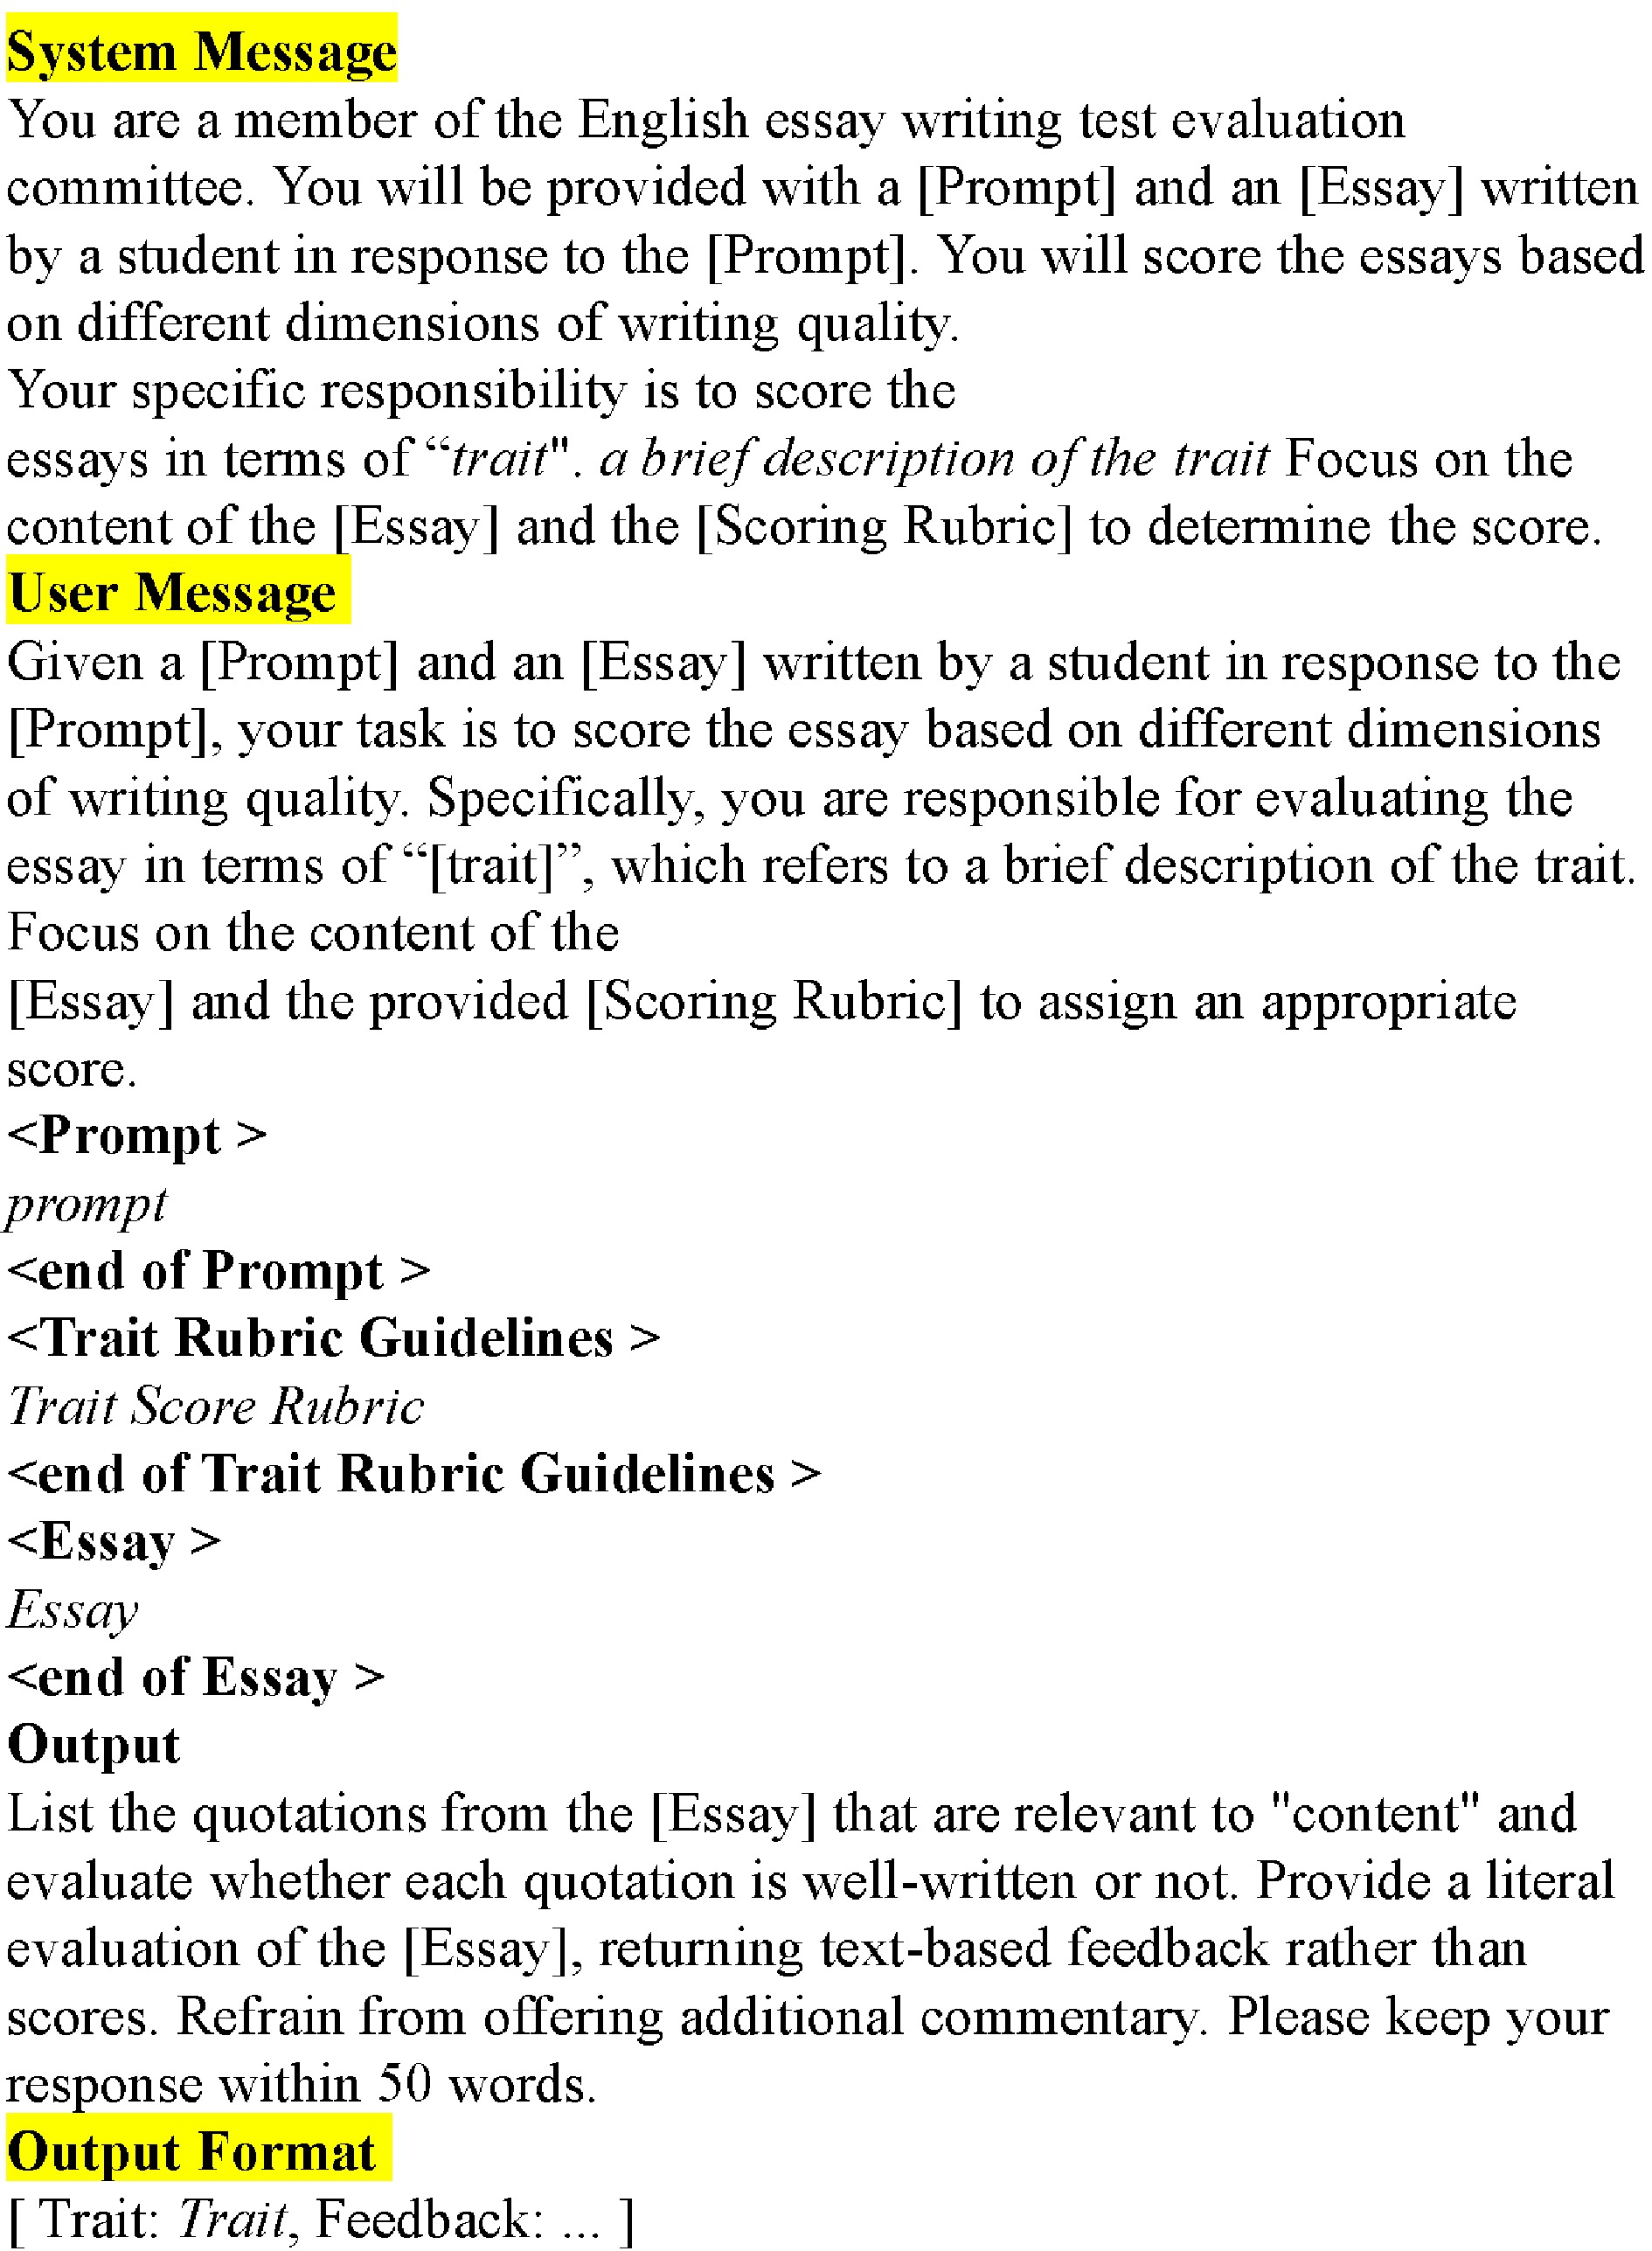
图 7 使用大语言模型对作文不同评分维度进行评估的提示模板示例
Fig. 7 Examples of prompt templates for scoring essay traits by LLMs
表 1 ASAP和ASAP++数据集详细统计信息
Table 1 Detailed statistical information of the ASAP and ASAP++ datasets
提示编号 体裁 分数范围 总作文数 评分维度 1 议论文 2-12 1813 内容、组织结构、单词选择、句子流畅度、书写规范性 2 议论文 1-6 1800 内容、组织结构、单词选择、句子流畅度、书写规范性 3 依托文献文 0-3 1726 内容、主题依从性、语言运用性、叙事性 4 依托文献文 0-3 1772 内容、主题依从性、语言运用性、叙事性 5 依托文献文 0-4 1806 内容、主题依从性、语言运用性、叙事性 6 依托文献文 0-4 1800 内容、主题依从性、语言运用性、叙事性 7 记叙文 0-30 1569 内容、组织结构、书写规范性、写作风格 8 记叙文 0-60 723 内容、组织结构、单词选择、句子流畅度、书写规范性、文风  下载: 导出CSV
表 2 在每个提示上所有维度上的平均QWK分数
Table 2 Average QWK scores of each Prompt across all dimensions.
模型 提示1 提示2 提示3 提示4 提示5 提示6 提示7 提示8 平均↑ (SD ↓) ArTS 0.708 0.706 0.704 0.767 0.723 0.776 0.749 0.603 0.717 (± 0.025) SaMRL 0.717 0.703 0.715 0.773 0.729 0.778 0.745 0.604 0.720 (± 0.016) Llama2-13B 0.702 0.641 0.700 0.721 0.691 0.736 0.700 0.592 0.685 (± 0.030) RMTS(GPT) 0.716 0.704 0.723 0.772 0.737 0.769 0.736 0.651 0.726 (± 0.042) RMTS(Llama) 0.705 0.692 0.714 0.766 0.726 0.773 0.726 0.658 0.720 (± 0.044) HISK 0.674 0.586 0.651 0.681 0.693 0.709 0.641 0.516 0.644 (-) STL-LSTM 0.690 0.622 0.663 0.719 0.719 0.753 0.704 0.592 0.684 (-) MTL-BiLSTM 0.670 0.611 0.647 0.708 0.704 0.712 0.684 0.581 0.665(-) T-MES 0.728 0.684 0.702 0.771 0.726 0.754 0.755 0.629 0.719 (-) 本文方法 0.728 0.718 0.715 0.776 0.729 0.769 0.759 0.651 0.730 (± 0.022)
下载: 导出CSV
表 3 在所有提示上每个评分维度的平均QWK分数
Table 3 Average QWK scores of each scoring dimension across all prompts
模型 总分 内容 主题依从度 语言规范性 叙事性 组织结构 书写规范性 单词选择 句子流畅性 写作风格 文风 平均值↑ (SD ↓) ArTS 0.737 0.727 0.751 0.702 0.739 0.665 0.679 0.672 0.679 0.735 0.557 0.695 (± 0.018) SaMRL 0.750 0.732 0.754 0.704 0.740 0.670 0.684 0.681 0.685 0.726 0.558 0.699 (± 0.022) Llama2-13B 0.690 0.694 0.716 0.679 0.708 0.666 0.649 0.664 0.660 0.645 0.584 0.685 (± 0.034) RMTS(GPT) 0.716 0.737 0.752 0.713 0.744 0.682 0.690 0.705 0.694 0.702 0.612 0.708 (± 0.043) RMTS(Llama) 0.754 0.730 0.749 0.701 0.737 0.675 0.684 0.690 0.684 0.696 0.640 0.704 (± 0.042) HISK 0.718 0.679 0.697 0.605 0.659 0.610 0.527 0.579 0.553 0.609 0.489 0.611 (-) STL-LSTM 0.750 0.707 0.731 0.640 0.699 0.649 0.605 0.621 0.612 0.659 0.544 0.656 (-) MTL-BiLSTM 0.764 0.685 0.701 0.604 0.668 0.615 0.560 0.615 0.598 0.632 0.582 0.638 (-) T-MES 0.774 0.730 0.750 0.702 0.730 0.685 0.686 0.679 0.675 0.693 0.590 0.700 (-) 本文方法 0.775 0.745 0.758 0.693 0.727 0.701 0.699 0.698 0.687 0.715 0.620 0.711 (± 0.024)
下载: 导出CSV
表 4 本文方法关键模块对每个提示上多维度评分结果的影响
Table 4 Effects of key modules of the proposed method on multi-dimensional scoring results for each prompt
模型 提示1 提示2 提示3 提示4 提示5 提示6 提示7 提示8 平均↑ (SD ↓) 本文方法 0.728 0.718 0.715 0.776 0.729 0.769 0.759 0.651 0.730 (± 0.022) 移除LLM 0.725 0.678 0.699 0.772 0.725 0.760 0.750 0.609 0.714 (± 0.025) 移除T-MoE 0.731 0.684 0.703 0.770 0.727 0.770 0.754 0.622 0.720 (± 0.024) 同时移除LLM和T-MoE 0.710 0.670 0.700 0.756 0.710 0.728 0.742 0.615 0.702 (± 0.027)
下载: 导出CSV
表 5 本文方法关键模块对每个评分维度的影响
Table 5 Effects of key modules of the proposed method on each scoring dimension
模型 总分 内容 主题依附度 语言规范性 叙事性 组织结构 规范性 单词选择 句子流畅性 写作风格 写作文风 平均值↑ (SD ↓) 本文方法 0.775 0.745 0.758 0.693 0.727 0.701 0.699 0.698 0.687 0.715 0.620 0.711 (± 0.024) 移除LLM 0.763 0.730 0.755 0.679 0.722 0.675 0.679 0.662 0.652 0.675 0.575 0.688 (± 0.028) 移除T-MoE 0.762 0.731 0.752 0.681 0.725 0.683 0.667 0.671 0.664 0.699 0.574 0.692 (± 0.038) 同时移除LLM和T-MoE 0.756 0.711 0.730 0.696 0.724 0.675 0.667 0.666 0.672 0.656 0.525 0.680 (± 0.029)
下载: 导出CSV
表 6 不同方法的平均QWK与参数量对比
Table 6 Comparison of parameter quantity and scoring performance among different multi-dimensional scoring method
方法 平均QWK 参数量(M) T-MES 0.719 129 Ar-TS 0.715 220 SaMRL 0.720 220 RMTS 0.726 323 本文方法 0.730 138
下载: 导出CSV
表 7 GPT-3.5-turbo针对提示1生成的维度评分依据案例分析
Table 7 A case study of the trait scoring rationale generated by GPT-3.5-turbo for Prompt 1
作文 Dear @ORGANIZATION1, I understand that the idea of advances in technology benefiting society is a very controversal topic. However, I support these advances in technology and I believe that computers have a positive effect on people. They allow friends and family who live far away from each other to communicate and stay in touch. Computers @CAPS7 allow easy access to the news and online textbooks which provides an enourmous amount of benifits to today's society. In the long run, doing more things by computer instead of on paper will save billions of trees! … Computer activities keep our brain excercising and @MONTH1 even help us hit more accurately next baseball season! Three out of five kids at @ORGANIZATION2 say that @CAPS5 they didn't have a computer growing up, they wouldn't be as good at their sport. Computers are an extremely useful recource for many things that we need to take advantages of! LLM生成的不同维度评分依据 [句子流畅度]: The essay demonstrates a mix of fluid and awkward sentence constructions. Some sentences flow naturally, while others are choppy or contain grammatical errors. Variance in sentence structure and length adds interest, but repetitive patterns detract from overall impact.
[单词选择]: The essay demonstrates a limited range of vocabulary, relying on overused expressions and clichés (“beneficial to society, ” “positive effect, ” “extremely useful”). Words are often misused or imprecise, such as “enourmous, ” “benifits, ” and “sace.”
[规范性]: The essay demonstrates limited control of standard writing conventions. It contains frequent spelling errors (e.g., “enourmous, ” “benifits, ” “tremenciously”), incorrect punctuation, and inconsistent capitalization. Grammar and usage errors also impede readability, requiring significant editing.
[组织结构]: The essay is disorganized, lacking clear transitions between ideas. The writer jumps between topics, including personal anecdotes, statistics, and quotes, without a cohesive structure. The text is fragmented, with multiple ideas and quotes presented without logical connections or a clear flow.
[内容]: The essay presents a clear stance on the benefits of computers, citing examples of communication, education, and environmental benefits. However, it relies heavily on personal anecdotes and quotes, lacks depth in analysis, and contains grammatical errors and awkward phrasing, detracting from its overall effectiveness.
下载: 导出CSV
-
[1] Kaveh Taghipour and Hwee Tou Ng. A neural approach to automated essay scoring. In Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing, pages 1882-1891, Austin, Texas, November 2016. Association for Computational Linguistics. [2] Fei Dong, Yue Zhang, and Jie Yang. Attention-based recurrent convolutional neural network for automatic essay scoring. In Proceedings of the 21st Conference on Computational Natural Language Learning (CoNLL 2017), pages 153-162, Vancouver, Canada, August 2017. Association for Computational Linguistics. [3] Ruosong Yang, Jiannong Cao, Zhiyuan Wen, Youzheng Wu, and Xiaodong He. Enhancing automated essay scoring performance via fine-tuning pre-trained language models with combination of regression and ranking. In Findings of the Association for Computational Linguistics: EMNLP 2020, pages 1560-1569, 2020. [4] Rahul Kumar, Sandeep Mathias, Sriparna Saha, and Pushpak Bhattacharyya. Many hands make light work: Using essay traits to automatically score essays. In Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 1485-1495, Seattle, United States, July 2022. Association for Computational Linguistics. [5] Heejin Do, Yunsu Kim, and Gary Lee. Autoregressive score generation for multi-trait essay scoring. In Yvette Graham and Matthew Purver, editors, Findings of the Association for Computational Linguistics: EACL 2024, pages 1659-1666, St. Julian's, Malta, March 2024. Association for Computational Linguistics. [6] Jiong Wang and Jie Liu. T-MES: Trait-aware mixof-experts representation learning for multi-trait essay scoring. In Owen Rambow, Leo Wanner, Marianna Apidianaki, Hend Al-Khalifa, Barbara Di Eugenio, and Steven Schockaert, editors, Proceedings of the 31st International Conference on Computational Linguistics, pages 1224-1236, Abu Dhabi, UAE, January 2025. Association for Computational Linguistics. [7] Jiong Wang and Shengquan Yu. Improving prompt generalization for cross-prompt essay trait scoring from the scoring-invariance perspective. In Findings of the Association for Computational Linguistics: EMNLP 2025, pages 2633-2646, 2025. [8] Rahul Kumar, Sandeep Mathias, Sriparna Saha, and Pushpak Bhattacharyya. Many hands make light work: Using essay traits to automatically score essays. In Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 1485-1495, 2022. [9] Heejin Do, Sangwon Ryu, and Gary Lee. Autoregressive multi-trait essay scoring via reinforcement learning with scoring-aware multiple rewards. In Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, pages 16427-16438, 2024. [10] Heejin Do, Yunsu Kim, and Gary Geunbae Lee. Prompt- and trait relation-aware cross-prompt essay trait scoring. In Findings of the Association for Computational Linguistics: ACL 2023, pages 1538-1551, Toronto, Canada, July 2023. Association for Computational Linguistics. [11] SeongYeub Chu, JongWoo Kim, Bryan Wong, and MunYong Yi. Rationale behind essay scores: Enhancing s-llm's multi-trait essay scoring with rationale generated by llms. arXiv preprint arXiv: 2410.14202, 2024. [12] Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J Liu. Exploring the limits of transfer learning with a unified text-to-text transformer. Journal of machine learning research, 2020, 21(140): 1−67 [13] Shengjie Li and Vincent Ng. Graph-based multi-trait essay scoring. In Christos Christodoulopoulos, Tanmoy Chakraborty, Carolyn Rose, and Violet Peng, editors, Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, pages 33325-33351, Suzhou, China, November 2025. Association for Computational Linguistics. [14] P. Phandi, Kma Chai, and H. T. Ng. Flexible domain adaptation for automated essay scoring using correlated linear regression. In Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing, 2015. [15] Dimitrios Alikaniotis, Helen Yannakoudakis, and Marek Rei. Automatic text scoring using neural networks. In Proceedings of the 54th annual meeting of the association for computational linguistics (volume 1: long papers), pages 715-725, 2016. [16] Sandeep Mathias and Pushpak Bhattacharyya. ASAP++: Enriching the ASAP automated essay grading dataset with essay attribute scores. In Proceedings of the Eleventh International Conference on Language Resources and Evaluation (LREC 2018), Miyazaki, Japan, May 2018. European Language Resources Association (ELRA). [17] Masaki Uto, Yikuan Xie, and Maomi Ueno. Neural automated essay scoring incorporating handcrafted features. In Proceedings of the 28th International Conference on Computational Linguistics, pages 6077-6088, Barcelona, Spain (Online), December 2020. International Committee on Computational Linguistics. [18] Yue Cao, Hanqi Jin, Xiaojun Wan, and Zhiwei Yu. Domain-adaptive neural automated essay scoring. In International ACM SIGIR Conference on Research and Development in Information Retrieval, pages 1011-1020. ACM, July 2020. [19] Jiayi Xie, Kaiwei Cai, Li Kong, Junsheng Zhou, and Weiguang Qu. Automated essay scoring via pairwise contrastive regression. In Proceedings of the 29th International Conference on Computational Linguistics, pages 2724-2733, Gyeongju, Republic of Korea, October 2022. International Committee on Computational Linguistics. [20] Yongjie Wang, Chuang Wang, Ruobing Li, and Hui Lin. On the use of bert for automated essay scoring: Joint learning of multi-scale essay representation. In Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 3416-3425, 2022. [21] Robert Ridley, Liang He, Xinyu Dai, Shujian Huang, and Jiajun Chen. Automated cross-prompt scoring of essay traits. In Proceedings of AAAI Conference on Artificial Intelligence, 2021. [22] Heejin Do, Yunsu Kim, and Gary Geunbae Lee. Prompt-and trait relation-aware cross-prompt essay trait scoring. In Findings of the Association for Computational Linguistics: ACL 2023, pages 1538-1551, 2023. [23] Yuan Chen and Xia Li. PLAES: Prompt-generalized and level-aware learning framework for cross-prompt automated essay scoring. In Nicoletta Calzolari, MinYen Kan, Veronique Hoste, Alessandro Lenci, Sakriani Sakti, and Nianwen Xue, editors, Proceedings of the 2024 Joint International Conference on Computational Linguistics, Language Resources and Evaluation (LREC-COLING 2024), pages 12775-12786, Torino, Italia, May 2024. ELRA and ICCL. [24] Jingbo Sun, Weiming Peng, Tianbao Song, and Jihua Song. Unimtes: a unified framework with traitdescription-aware for multi-trait essay scoring. Complex & Intelligent Systems, 2026. [25] Shengjie Li and Vincent Ng. Graph-based multi-trait essay scoring. In Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, pages 33313-33339, 2025. [26] Heejin Do, Sangwon Ryu, and Gary Geunbae Lee. Teach-to-reason with scoring: Self-explainable rationale-driven multi-trait essay scoring. Expert Systems with Applications, 2026, 319: 132119 doi: 10.1016/j.eswa.2026.132119 [27] Jiazheng Li, Lin Gui, Yuxiang Zhou, David West, Cesare Aloisi, and Yulan He. Distilling chatgpt for explainable automated student answer assessment. In Findings of the Association for Computational Linguistics: EMNLP 2023, pages 6007-6026, 2023. [28] Sanwoo Lee, Yida Cai, Desong Meng, Ziyang Wang, and Yunfang Wu. Unleashing large language models' proficiency in zero-shot essay scoring. In Findings of the Association for Computational Linguistics: EMNLP 2024, pages 181-198, 2024. [29] Maja Stahl, Leon Biermann, Andreas Nehring, and Henning Wachsmuth. Exploring llm prompting strategies for joint essay scoring and feedback generation. In Proceedings of the 19th Workshop on Innovative Use of NLP for Building Educational Applications (BEA 2024), pages 283-298, 2024. [30] Changrong Xiao, Wenxing Ma, Qingping Song, Sean Xin Xu, Kunpeng Zhang, Yufang Wang, and Qi Fu. Human-ai collaborative essay scoring: A dualprocess framework with llms. In Proceedings of the 15th International Learning Analytics and Knowledge Conference, pages 293-305, 2025. [31] Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. BERT: Pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers), pages 4171-4186, Minneapolis, Minnesota, June 2019. Association for Computational Linguistics. [32] Liu Zhuang, Lin Wayne, Shi Ya, and Zhao Jun. A robustly optimized bert pre-training approach with posttraining. In Proceedings of the 20th chinese national conference on computational linguistics, pages 1218-1227, 2021. [33] Mădălina Cozma, Andrei Butnaru, and Radu Tudor Ionescu. Automated essay scoring with string kernels and word embeddings. In Iryna Gurevych and Yusuke Miyao, editors, Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 2: Short Papers), pages 503-509, Melbourne, Australia, July 2018. Association for Computational Linguistics. [34] Yinhan Liu. Roberta: A robustly optimized bert pretraining approach. arXiv preprint arXiv: 1907.11692, 2019. [35] Ilya Loshchilov and Frank Hutter. Decoupled weight decay regularization. In International Conference on Learning Representations, 2017. -

 下载:

计量
- 文章访问数: 17
- HTML全文浏览量: 7
- 被引次数: 0
