

Audio-visual Segmentation Network Combining State Space Models and Dynamic Focal Loss
-
摘要: 视听目标分割任务旨在依据音频信号对视频中的发声物体进行像素级分割, 但在处理复杂动态场景时, 现有方法面临跨模态特征交互不充分与像素级样本分布失衡两大挑战. 为此, 提出结合状态空间模型与动态焦点损失的视听分割网络MambaAVS, 构建跨时间音频查询生成与跨模态音视频交互两大核心模块. 首先, 利用跨时间音频查询生成机制提取关键频域信息以增强音频表征; 随后, 通过跨模态音视频交互模块动态捕捉音视频模态间的长距离依赖与语义对应关系, 实现特征的深度对齐与交互. 此外, 针对训练过程中存在的难易样本分布不均问题, 提出动态焦点损失, 通过自适应调节难易样本权重与梯度表征, 有效缓解了模型优化偏差. 在 AVSBench-Object 与 AVSBench-Semantic 数据集上的实验结果表明, 所提 MambaAVS 在单声源、多声源及视听语义分割数据集上的mIoU比分别达到82.86%、62.56%和36.79%; 与同类先进方法 AVSegFormer 相比, MambaAVS在3个数据集上的精度分别提升0.80%、4.20%和0.13%, 验证了其在复杂视听场景下的有效性.Abstract: Audio-visual segmentation task aims to perform pixel-level segmentation of sounding objects in videos by leveraging audio-visual cues. However, existing approaches still suffer from two major challenges in complex dynamic scenarios: Insufficient cross-modal feature interaction and severe pixel-level sample distribution imbalance. To address these issues, this paper proposes MambaAVS, an audio-visual segmentation network built upon a state space model and optimized with a dynamic focal loss. Specifically, MambaAVS introduces two key modules: Cross-temporal audio query generation and cross-modal audio-visual interactive integration. First, the cross-temporal audio query generation module extracts key frequency-domain information to enhance audio representations. Then, the cross-modal audio-visual interactive integration module dynamically captures long-range cross-modal dependencies and semantic correspondences between audio and visual modalities, enabling effective feature alignment and interaction. Furthermore, to alleviate the optimization bias caused by the imbalanced distribution of hard/easy samples during training, a dynamic focal loss is proposed to adaptively adjust sample weights and gradient contributions. Extensive experiments on the AVSBench-Object and AVSBench-Semantic datasets demonstrate that MambaAVS achieves mIoU scores of 82.86%, 62.56%, and 36.79% on the single sound source, multiple sound source, and audio-visual semantic segmentation tasks, respectively. Compared with the state-of-the-art method AVSegFormer, MambaAVS improves mIoU by 0.80%, 4.20%, and 0.13% on the three tasks, respectively, demonstrating its effectiveness in complex audio-visual scenarios.
-
Key words:
- audio-visual segmentation /
- state space model /
- feature interaction /
- dynamic focal loss
-
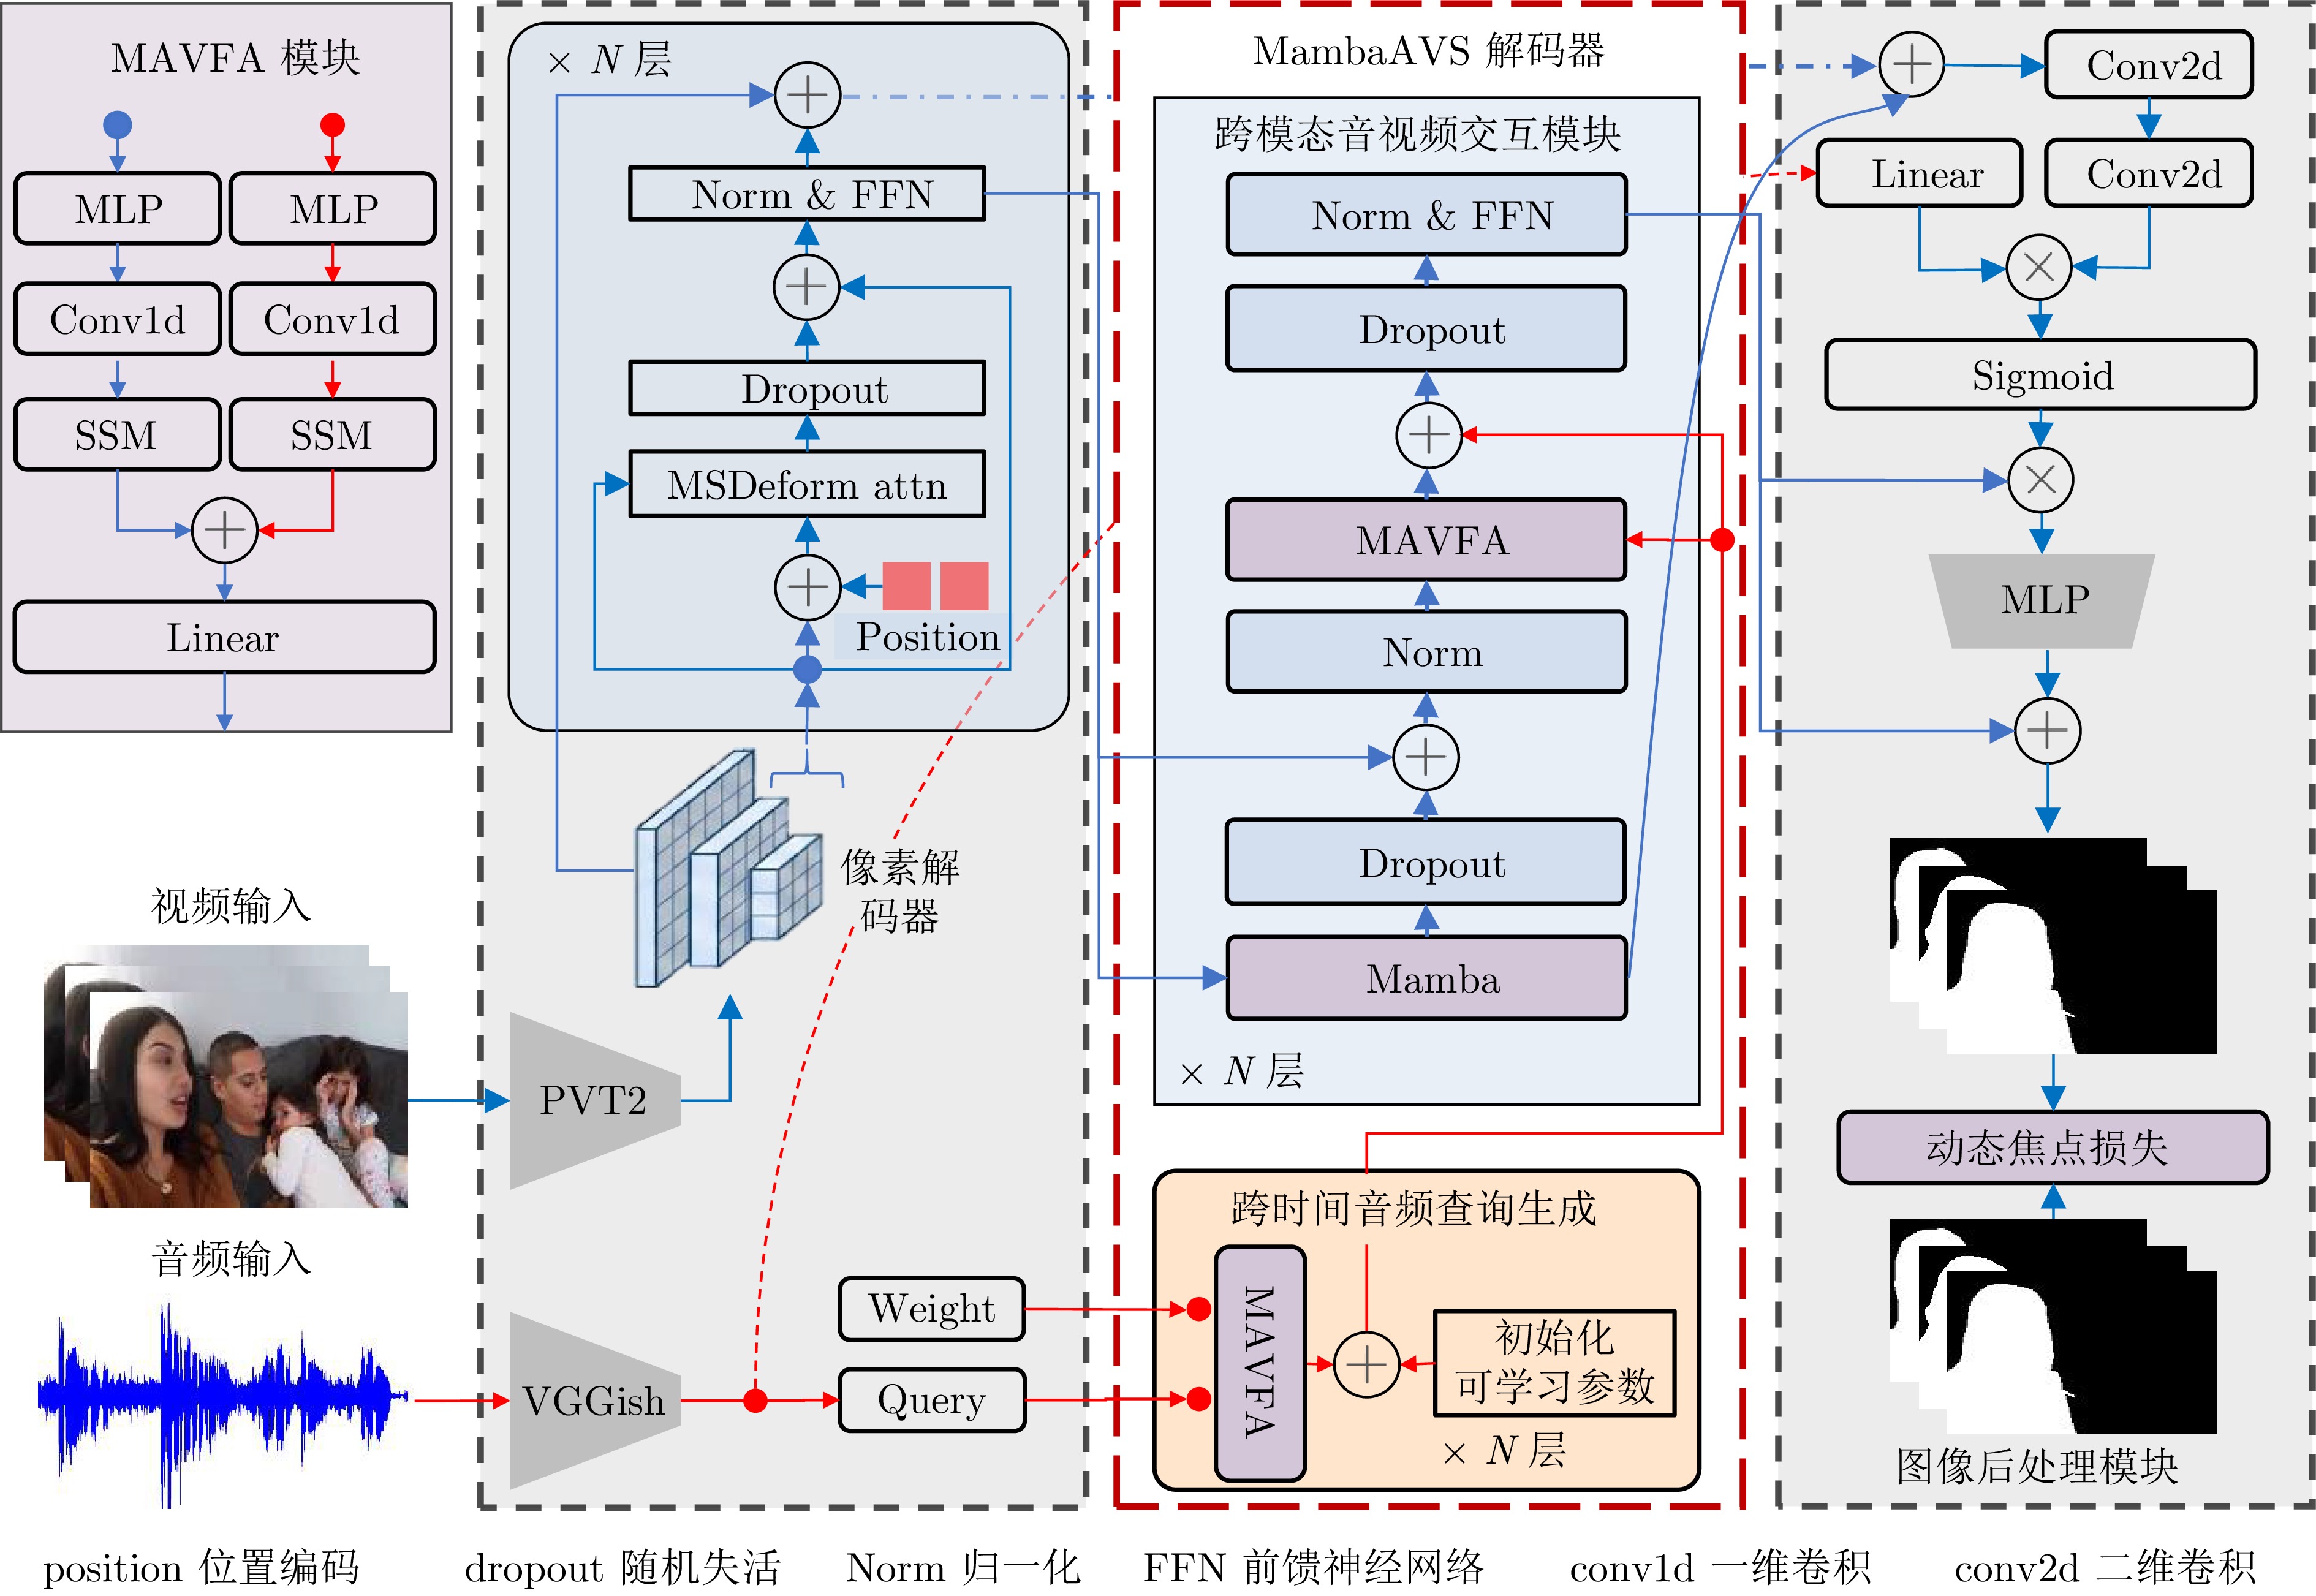
图 2 融合状态空间模型与动态焦点损失的视听目标分割框架
Fig. 2 A audio-visual object segmentation framework integrating state space models and dynamic focal loss
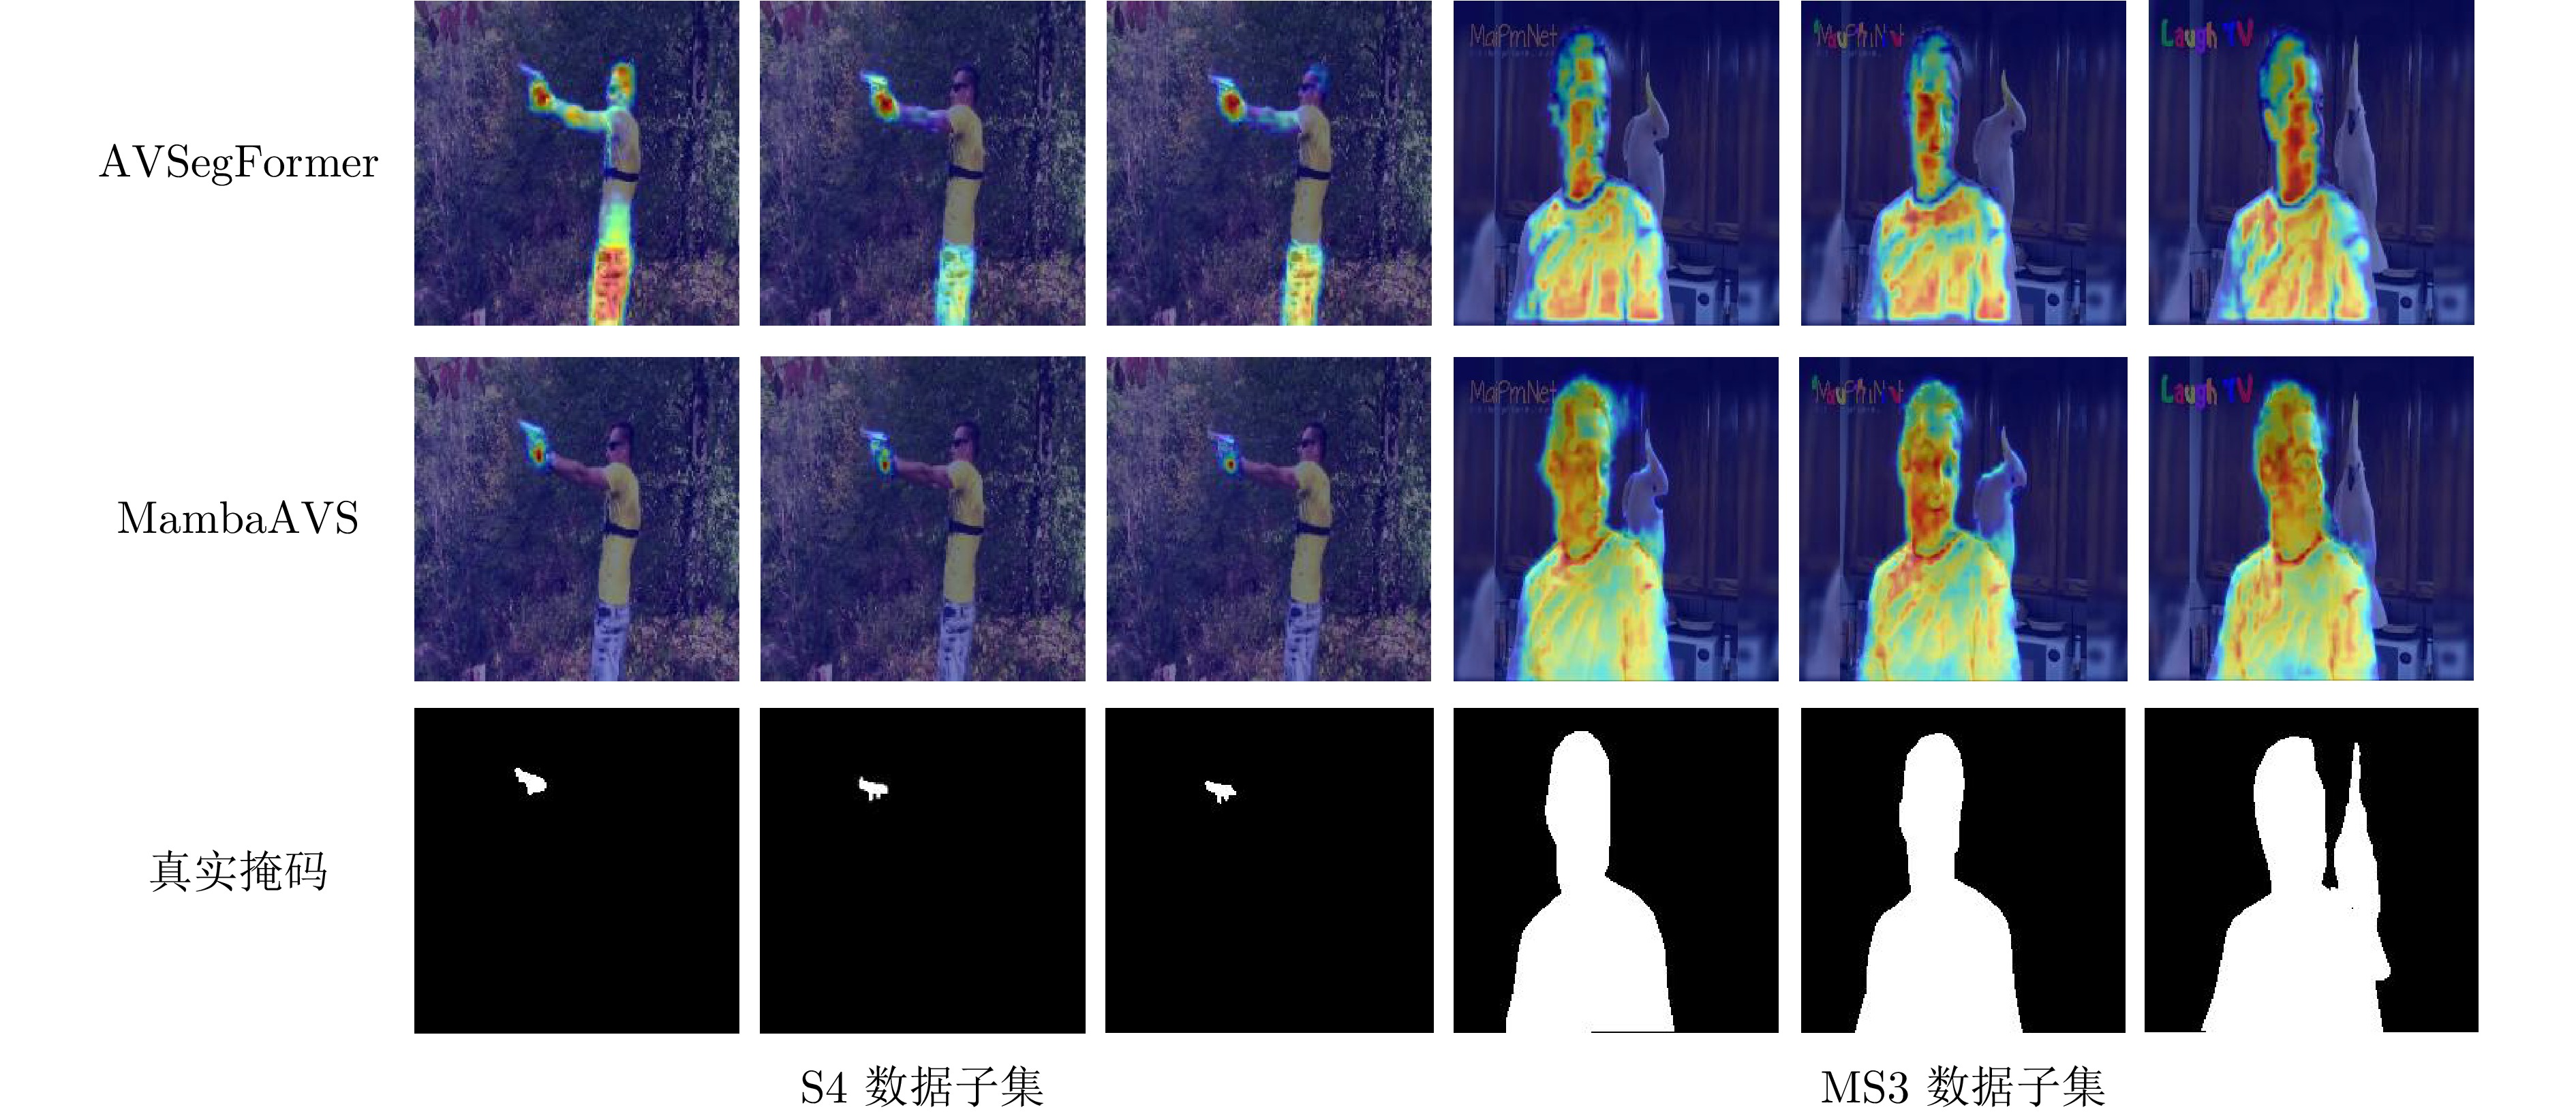
图 4 使用或不使用MambaAVS组件时Grad-CAM可视化结果
Fig. 4 Grad-CAM visualization results with and without the MambaAVS component
表 1 以 ResNet-50 为骨干网络, 所提 MambaAVS 与不同 AVS 方法的分割性能对比 (%)
Table 1 Using ResNet-50 as the backbone network, the segmentation performance comparison of the proposed MambaAVS with various AVS methods (%)
方法 骨干网络 S4 MS3 AVSS F-score mIoU F-score mIoU F-score mIoU MSSL[5] ResNet-50 66.30 44.89 36.30 26.13 — — 3DC[35] ResNet-50 75.90 57.10 50.30 36.92 21.60 17.17 LVS[36] ResNet-50 51.00 37.94 33.00 29.45 — — SST[37] ResNet-50 80.10 66.29 57.20 42.57 — — AVSegFormer[38] ResNet-50 85.21 75.08 62.89 50.37 31.26 26.71 MambaAVS (本文方法) ResNet-50 86.30 76.37 63.75 51.95 33.83 28.59  下载: 导出CSV
表 2 不同骨干网络设置下, 所提 MambaAVS 与不同 AVS 方法的分割性能统计 (%)
Table 2 Segmentation performance statistics for the proposed MambaAVS and various AVS methods across different backbone networks (%)
方法 骨干网络 S4 MS3 AVSS F-score mIoU F-score mIoU F-score mIoU AOT[39] Swin-B — — — — 31.00 25.40 LGVT[40] Swin-T 87.30 74.94 59.30 40.71 — — AVSBench[1] PVTv2 87.90 78.74 64.50 54.00 35.20 29.77 AVSC[26] PVTv2 88.60 81.29 65.70 59.50 — — ECMVAE[2] PVTv2 90.10 81.74 70.80 57.84 — — AVSegFormer[38] PVTv2 89.90 82.06 69.30 58.36 42.00 36.66 CQFormer[41] PVTv2 91.18 83.62 72.67 60.99 43.01 38.09 DiffusionAVS[42] PVTv2 90.30 81.51 71.20 59.62 43.00 38.10 MambaAVS (本文方法) PVTv2 90.78 82.86 73.49 62.56 43.04 36.79
下载: 导出CSV
表 3 使用与不使用 MambaAVS 和 DFL 组件时的性能比较
Table 3 Performance comparison with and without the MambaAVS and DFL components
方法 骨干网络 S4 MS3 参数量(M) 推理速度(FPS) F-score (%) mIoU (%) F-score (%) mIoU (%) 基线 ResNet-50 85.82 75.41 62.89 50.37 150.90 152.22 基线+MambaAVS ResNet-50 85.82 76.03 64.71 52.82 154.68 113.04 基线+DFL ResNet-50 86.07 75.97 63.62 51.73 150.90 152.22 基线+MambaAVS+DFL ResNet-50 86.30 76.37 63.75 51.95 154.68 113.04
下载: 导出CSV
表 4 MambaAVS 组件的消融实验(%)
Table 4 Ablation experiment of the MambaAVS component (%)
方法 骨干网络 S4 MS3 F-score mIoU F-score mIoU 基线 ResNet-50 85.21 75.08 62.89 50.37 基线+CTAQG ResNet-50 85.53 75.42 63.22 50.44 基线+CAVII ResNet-50 85.60 75.70 63.72 51.20 MambaAVS ResNet-50 85.82 76.03 64.71 52.82
下载: 导出CSV
表 5 DFL 组件的消融实验(%)
Table 5 Ablation experiment of the DFL component (%)
方法 骨干网络 S4 MS3 F-score mIoU F-score mIoU 基线 ResNet-50 85.31 74.93 64.05 51.15 基线$+\xi_{a}$ ResNet-50 85.90 75.89 63.67 50.95 基线$+\xi_{{g}}$ ResNet-50 86.02 75.77 62.71 51.98 基线$+\xi_{{l}}$ ResNet-50 85.99 75.79 64.29 51.98 DFL ResNet-50 86.07 75.97 63.62 51.73
下载: 导出CSV
-
[1] Zhou J X, Wang J Y, Zhang J Y, Sun W X, Zhang J, Birchfield S, et al. Audio-visual segmentation. In: Proceedings of the 17th European Conference on Computer Vision. Tel Aviv, Israel: Springer, 2022. 386−403 [2] Mao Y X, Zhang J, Xiang M C, Zhong Y R, Dai Y C. Multimodal variational auto-encoder based audio-visual segmentation. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV). Paris, France: IEEE, 2023. 954−965 [3] Arandjelovic R, Zisserman A. Look, listen and learn. In: Proceedings of the IEEE International Conference on Computer Vision (ICCV). Venice, Italy: IEEE, 2017. 609−617 [4] Liang T, Lin G S, Feng L, Zhang Y, Lv F M. Attention is not enough: Mitigating the distribution discrepancy in asynchronous multimodal sequence fusion. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV). Montreal, Canada: IEEE, 2021. 8128−8136 [5] Qian R, Hu D, Dinkel H, Wu M Y, Xu N, Lin W Y. Multiple sound sources localization from coarse to fine. In: Proceedings of the 16th European Conference on Computer Vision. Glasgow, UK: Springer, 2020. 292−308 [6] Nagrani A, Yang S, Arnab A, Jansen A, Schmid C, Sun C. Attention bottlenecks for multimodal fusion. In: Proceedings of the 35th International Conference on Neural Information Processing Systems. Virtual Event: Curran Associates Inc., 2021. 14200−14213 [7] Gong S T, Zhuge Y Z, Zhang L, Wang Y F, Zhang P P, Wang L J, et al. AVS-Mamba: Exploring temporal and multi-modal Mamba for audio-visual segmentation. IEEE Transactions on Multimedia, 2025, 27: 5413−5425 doi: 10.1109/TMM.2025.3542995 [8] 王锋, 银莹, 王佳炎, 唐勇, 李胜, 赵静. 基于高斯泼溅的轻量级重建场景分割方法. 计算机学报, 2025, 48(5): 1232−1243 doi: 10.11897/SP.J.1016.2025.01232Wang Feng, Yin Ying, Wang Jia-Yan, Tang Yong, Li Sheng, Zhao Jing. Object segmentation in 3D reconstructed scenes based on Gaussian splatting. Chinese Journal of Computers, 2025, 48(5): 1232−1243 doi: 10.11897/SP.J.1016.2025.01232 [9] Lin J C, Xiao Z Q, Wei X H, Duan P H, He X, Dian R W, et al. Click-pixel cognition fusion network with balanced cut for interactive image segmentation. IEEE Transactions on Image Processing, 2024, 33: 177−190 doi: 10.1109/TIP.2023.3338003 [10] 林家丞, 陈嘉俊, 李智勇, 王耀南. 基于语义概念关联的参考多目标跟踪方法. 自动化学报, 2025, 51(12): 2664−2678 doi: 10.16383/j.aas.c250118Lin Jia-Cheng, Chen Jia-Jun, Li Zhi-Yong, Wang Yao-Nan. Semantic conceptual association-based method for referring multi-object tracking. Acta Automatica Sinica, 2025, 51(12): 2664−2678 doi: 10.16383/j.aas.c250118 [11] Lin J C, Chen J J, Peng K Y, He X, Li Z Y, Stiefelhagen R, et al. EchoTrack: Auditory referring multi-object tracking for autonomous driving. IEEE Transactions on Intelligent Transportation Systems, 2024, 25(11): 18964−18977 doi: 10.1109/TITS.2024.3437645 [12] 刘袁缘, 刘树阳, 刘云娇, 袁雨晨, 唐厂, 罗威. 提示学习在计算机视觉中的分类、应用及展望. 自动化学报, 2025, 51(5): 1021−1040 doi: 10.16383/j.aas.c240177Liu Yuan-Yuan, Liu Shu-Yang, Liu Yun-Jiao, Yuan Yu-Chen, Tang Chang, Luo Wei. The classification, applications, and prospects of prompt learning in computer vision. Acta Automatica Sinica, 2025, 51(5): 1021−1040 doi: 10.16383/j.aas.c240177 [13] Sofiiuk K, Petrov I, Barinova O, Konushin A. F-BRS: Rethinking backpropagating refinement for interactive segmentation. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). Seattle, USA: IEEE, 2020. 8620−8629 [14] 封筠, 张天, 史屹琛, 王辉, 胡晶晶. 融合双阶段特征与Transformer编码的交互式图像分割. 计算机辅助设计与图形学学报, 2024, 36(6): 831−843Feng Jun, Zhang Tian, Shi Yi-Chen, Wang Hui, Hu Jing-Jing. Interactive image segmentation based on fusion of two-stage feature and Transformer encoder. Journal of Computer-aided Design & Computer Graphics, 2024, 36(6): 831−843 [15] Kirillov A, Mintun E, Ravi N, Mao H Z, Rolland C, Gustafson L, et al. Segment anything. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV). Paris, France: IEEE, 2023. 3992−4003 [16] Liu D Q, Zhang H W, Zha Z J, Wu F. Learning to assemble neural module tree networks for visual grounding. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV). Seoul, South Korea: IEEE, 2019. 4672−4681 [17] Miao B, Bennamoun M, Gao Y S, Mian A. Spectrum-guided multi-granularity referring video object segmentation. In: Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV). Paris, France: IEEE, 2023. 920−930 [18] Wu D M, Han W C, Wang T C, Dong X P, Zhang X Y, Shen J B. Referring multi-object tracking. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). Vancouver, Canada: IEEE, 2023. 14633−14642 [19] Cheng M J, Sun Y P, Wang L C, Zhu X W, Yao K, Chen J, et al. ViSTA: Vision and scene text aggregation for cross-modal retrieval. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). New Orleans, USA: IEEE, 2022. 5174−5183 [20] Wang Y T, Liu W S, Li G Y, Ding J, Hu D, Li X. Prompting segmentation with sound is generalizable audio-visual source localizer. In: Proceedings of the 38th AAAI Conference on Artificial Intelligence. Vancouver, Canada: AAAI Press, 2024. 5669−5677 [21] Chen J J, Lin J C, Zhong G J, Fu H L, Nai K L, Yang K L, et al. Expression prompt collaboration Transformer for universal referring video object segmentation. Knowledge-based Systems, 2025, 311: Article No. 113006 doi: 10.1016/j.knosys.2025.113006 [22] Ling Y H, Li Y X, Gan Z Y, Zhang J N, Chi M M, Wang Y B. TransAVS: End-to-end audio-visual segmentation with Transformer. In: Proceedings of the IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP). Seoul, South Korea: IEEE, 2024. 7845−7849 [23] Li K X, Yang Z X, Chen L, Yang Y, Xiao J. CATR: Combinatorial-dependence audio-queried Transformer for audio-visual video segmentation. In: Proceedings of the 31st ACM International Conference on Multimedia. Ottawa, Canada: Association for Computing Machinery, 2023. 1485−1494 [24] Liu J X, Ju C, Ma C F, Wang Y F, Wang Y, Zhang Y. Audio-aware query-enhanced Transformer for audio-visual segmentation. arXiv preprint arXiv: 2307.13236, 2023. [25] Huang S F, Li H, Wang Y Q, Zhu H J, Dai J, Han J Z, et al. Discovering sounding objects by audio queries for audio visual segmentation. In: Proceedings of the 32nd International Joint Conference on Artificial Intelligence. Macao, China: ijcai.org, 2023. Article No. 97 [26] Liu C, Li P P, Qi X Q, Zhang H, Li L C, Wang D D, et al. Audio-visual segmentation by exploring cross-modal mutual semantics. In: Proceedings of the 31st ACM International Conference on Multimedia. Ottawa, Canada: ACM, 2023. 7590−7598 [27] Yang Q, Nie X, Li T, Gao P F, Guo Y, Zhen C, et al. Cooperation does matter: Exploring multi-order bilateral relations for audio-visual segmentation. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). Seattle, USA: IEEE, 2024. 27134−27143 [28] Liu J X, Wang Y, Ju C, Ma C F, Zhang Y, Xie W D. Annotation-free audio-visual segmentation. In: Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV). Waikoloa, USA: IEEE, 2024. 5592−5602 [29] Islam M, Bertasius G. Long movie clip classification with state-space video models. In: Proceedings of the 17th European Conference on Computer Vision. Tel Aviv, Israel: Springer, 2022. 87−104 [30] Gu A, Dao T. Mamba: Linear-time sequence modeling with selective state spaces. arXiv preprint arXiv: 2312.00752, 2024. [31] Zhu L H, Liao B C, Zhang Q, Wang X L, Liu W Y, Wang X G. Vision Mamba: Efficient visual representation learning with bidirectional state space model. arXiv preprint arXiv: 2401.09417, 2024. [32] Yang Y H, Ma C F, Yao J C, Zhong Z, Zhang Y, Wang Y F. ReMamber: Referring image segmentation with Mamba twister. In: Proceedings of the 18th European Conference on Computer Vision. Milan, Italy: Springer, 2025. 108−126 [33] Zeng K, Shi H, Lin J C, Li S Y, Cheng J T, Wang K W, et al. MambaMOS: LiDAR-based 3D moving object segmentation with motion-aware state space model. In: Proceedings of the 32nd ACM International Conference on Multimedia. Melbourne, Australia: ACM, 2024. 1505−1513 [34] Lin J C, Chen J J, Yang K L, Roitberg A, Li S Y, Li Z Y, et al. AdaptiveClick: Click-aware Transformer with adaptive focal loss for interactive image segmentation. IEEE Transactions on Neural Networks and Learning Systems, 2025, 36(3): 5759−5773 doi: 10.1109/TNNLS.2024.3378295 [35] Mahadevan S, Athar A, Osep A, Leal-Taixé L, Leibe B, Hennen S. Making a case for 3D convolutions for object segmentation in videos. In: Proceedings of the 31st British Machine Vision Conference. Virtual Event: BMVA Press, 2020. [36] Chen H L, Xie W D, Afouras T, Nagrani A, Vedaldi A, Zisserman A. Localizing visual sounds the hard way. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). Nashville, USA: IEEE, 2021. 16862−16871 [37] Duke B, Ahmed A, Wolf C, Aarabi P, Taylor G W. SSTVOS: Sparse spatiotemporal Transformers for video object segmentation. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR). Nashville, USA: IEEE, 2021. 5908−5917 [38] Gao S Y, Chen Z, Chen G, Wang W H, Lu T. AVSegFormer: Audio-visual segmentation with Transformer. In: Proceedings of the 38th AAAI Conference on Artificial Intelligence. Vancouver, Canada: AAAI Press, 2024. 12155−12163 [39] Yang Z X, Wei Y C, Yang Y. Associating objects with Transformers for video object segmentation. In: Proceedings of the 35th International Conference on Neural Information Processing Systems. Virtual Event: Curran Associates Inc., 2021. 2491−2502 [40] Zhang J, Xie J W, Barnes N, Li P. Learning generative vision Transformer with energy-based latent space for saliency prediction. In: Proceedings of the 35th International Conference on Neural Information Processing Systems. Virtual Event: Curran Associates Inc., 2021. 15448−15463 [41] Lv Y, Liu Z, Chang X J. Consistency-queried Transformer for audio-visual segmentation. IEEE Transactions on Image Processing, 2025, 34: 2616−2627 doi: 10.1109/TIP.2025.3563076 [42] Mao Y X, Zhang J, Xiang M C, Lv Y Q, Li D, Zhong Y R, et al. Contrastive conditional latent diffusion for audio-visual segmentation. IEEE Transactions on Image Processing, 2025, 34: 4108−4119 doi: 10.1109/TIP.2025.3580269 -

 下载:

计量
- 文章访问数: 156
- HTML全文浏览量: 58
- 被引次数: 0
