

-
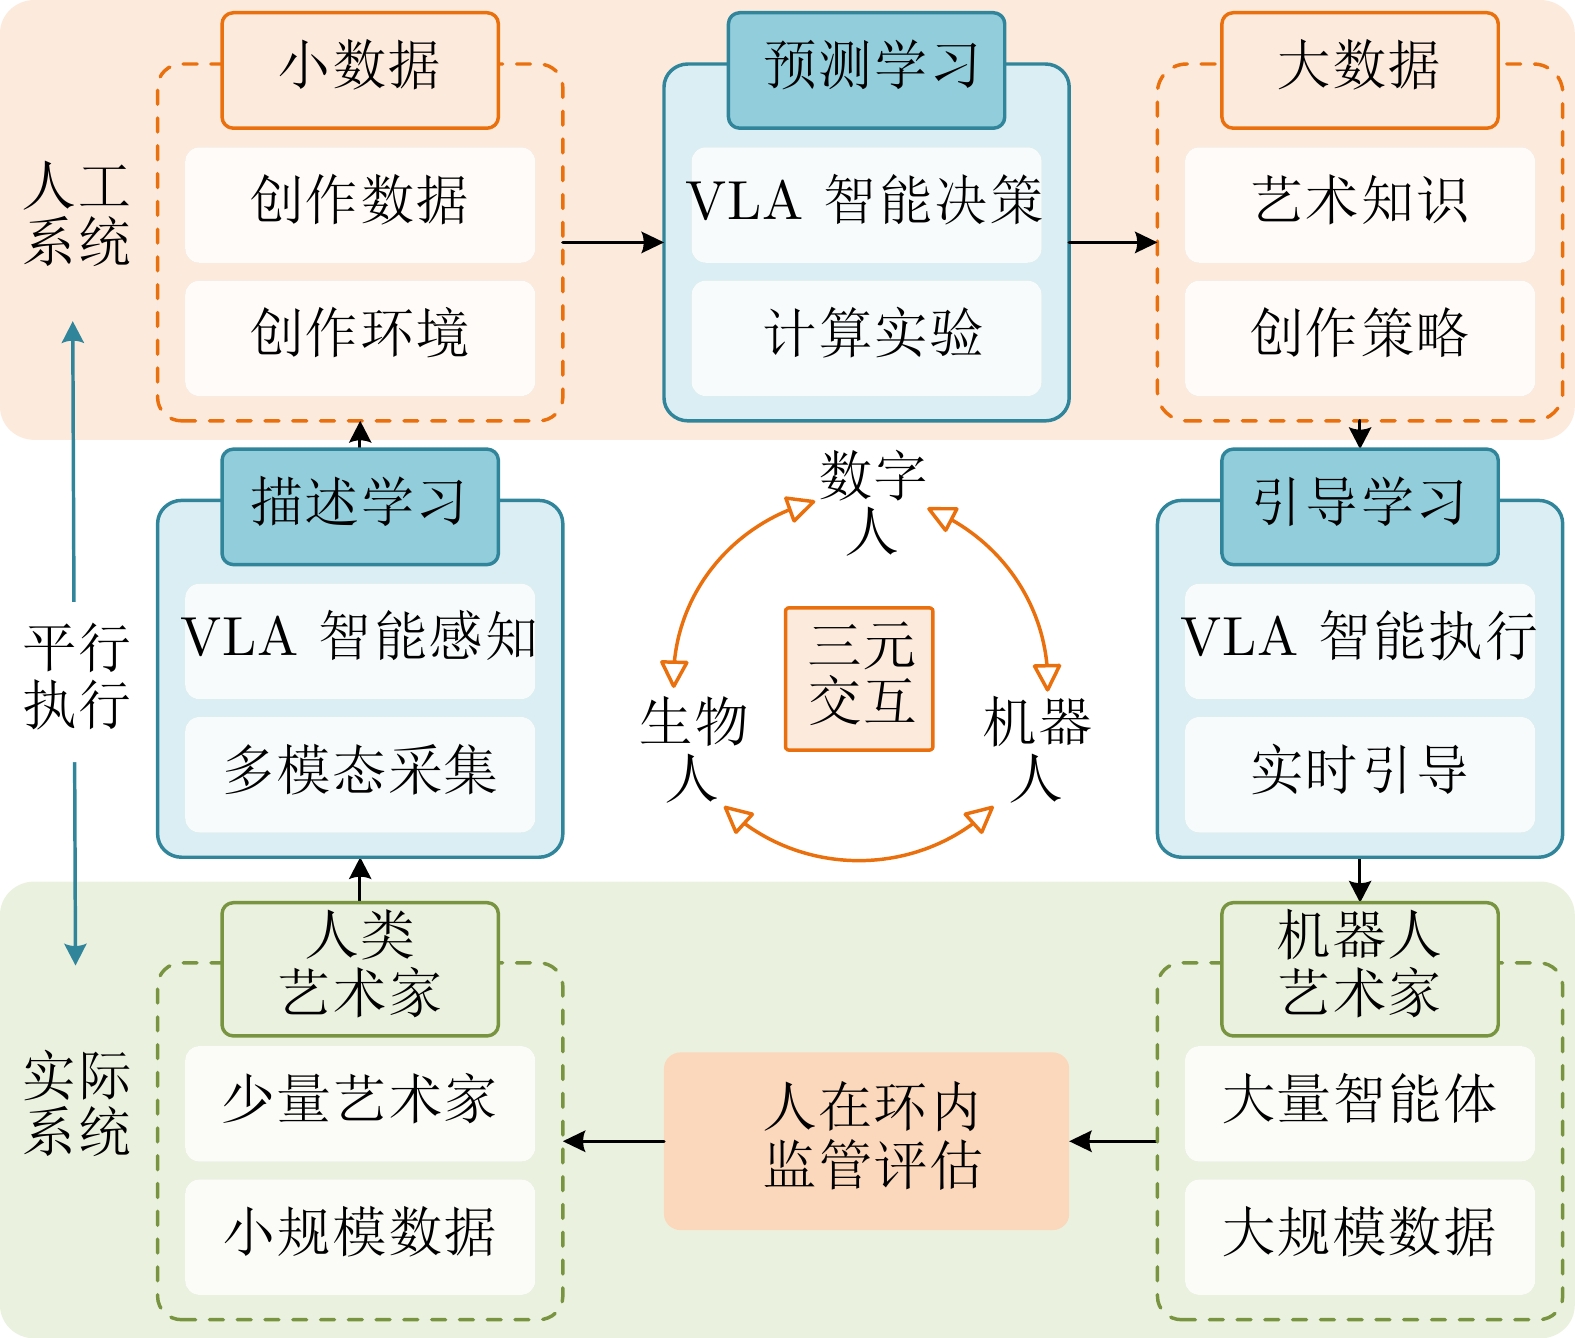
摘要: 近年来, 大模型等技术的迅速发展推动了人工智能与艺术创作的深度融合, 机器辅助乃至自主创作系统相继涌现, 在人类艺术创作中发挥日益重要的作用. 然而, 现有的主流艺术创作方法多停留在创作结果直接生成, 与人类艺术家逐步塑造的动态创作过程存在显著差距, 制约了机器艺术创作的进一步发展. 为提升人工智能创作系统对人类创作思维与过程的模拟能力, 本文基于平行系统理论与ACP方法, 提出视觉−语言−动作大模型驱动的平行艺术创作架构. 该架构依托平行系统的描述学习、预测学习与引导学习, 进行艺术创作全流程建模, 构建具备跨模态感知、语义理解与具身执行能力的创作智能体, 为人工智能创作系统的类人化演进提供新范式, 推动机器艺术创作由单一结果生成迈向创作过程自主完成. 文中阐述所提方法的总体结构、核心组成与主要特征, 并结合典型案例进行分析讨论, 最后总结全文并展望平行艺术的未来发展方向.
-
关键词:
- 人工智能艺术创作 /
- 视觉−语言−动作大模型 /
- 平行艺术 /
- 平行系统
Abstract: In recent years, the rapid advancement of large models has driven a deep integration between artificial intelligence (AI) and artistic creation. Machine-assisted and even autonomous creation systems have emerged successively, playing an increasingly significant role in human artistic production. However, most existing approaches to artistic creation remain focused on directly producing visual outcomes, exhibiting a notable gap from the dynamic creative processes of human artists characterized by progressive construction. This limitation constrains the further development of machine-based artistic creation. To improve the capability of AI creation systems in modeling human creative thinking and processes, this paper proposes a parallel artistic creation system driven by large vision-language-action (VLA) models, grounded in parallel systems theory and the ACP (artificial systems, computational experiments, and parallel execution) approach. The proposed framework employs the Descriptive Learning, Predictive Learning, and Prescriptive Learning of parallel systems to achieve full-process modeling of artistic creation, thereby constructing a creative agent with integrated cross-modal perception, semantic understanding, and embodied execution capabilities. This framework provides a new paradigm for the human-like evolution of AI art systems, advancing machine artistic creation from result-oriented generation toward autonomous realization of the entire creative process. The paper elaborates on the overall architecture, core components, and primary features of the proposed system, presents analyses through representative case studies, and concludes with a summary and outlook on the future development of parallel art. -
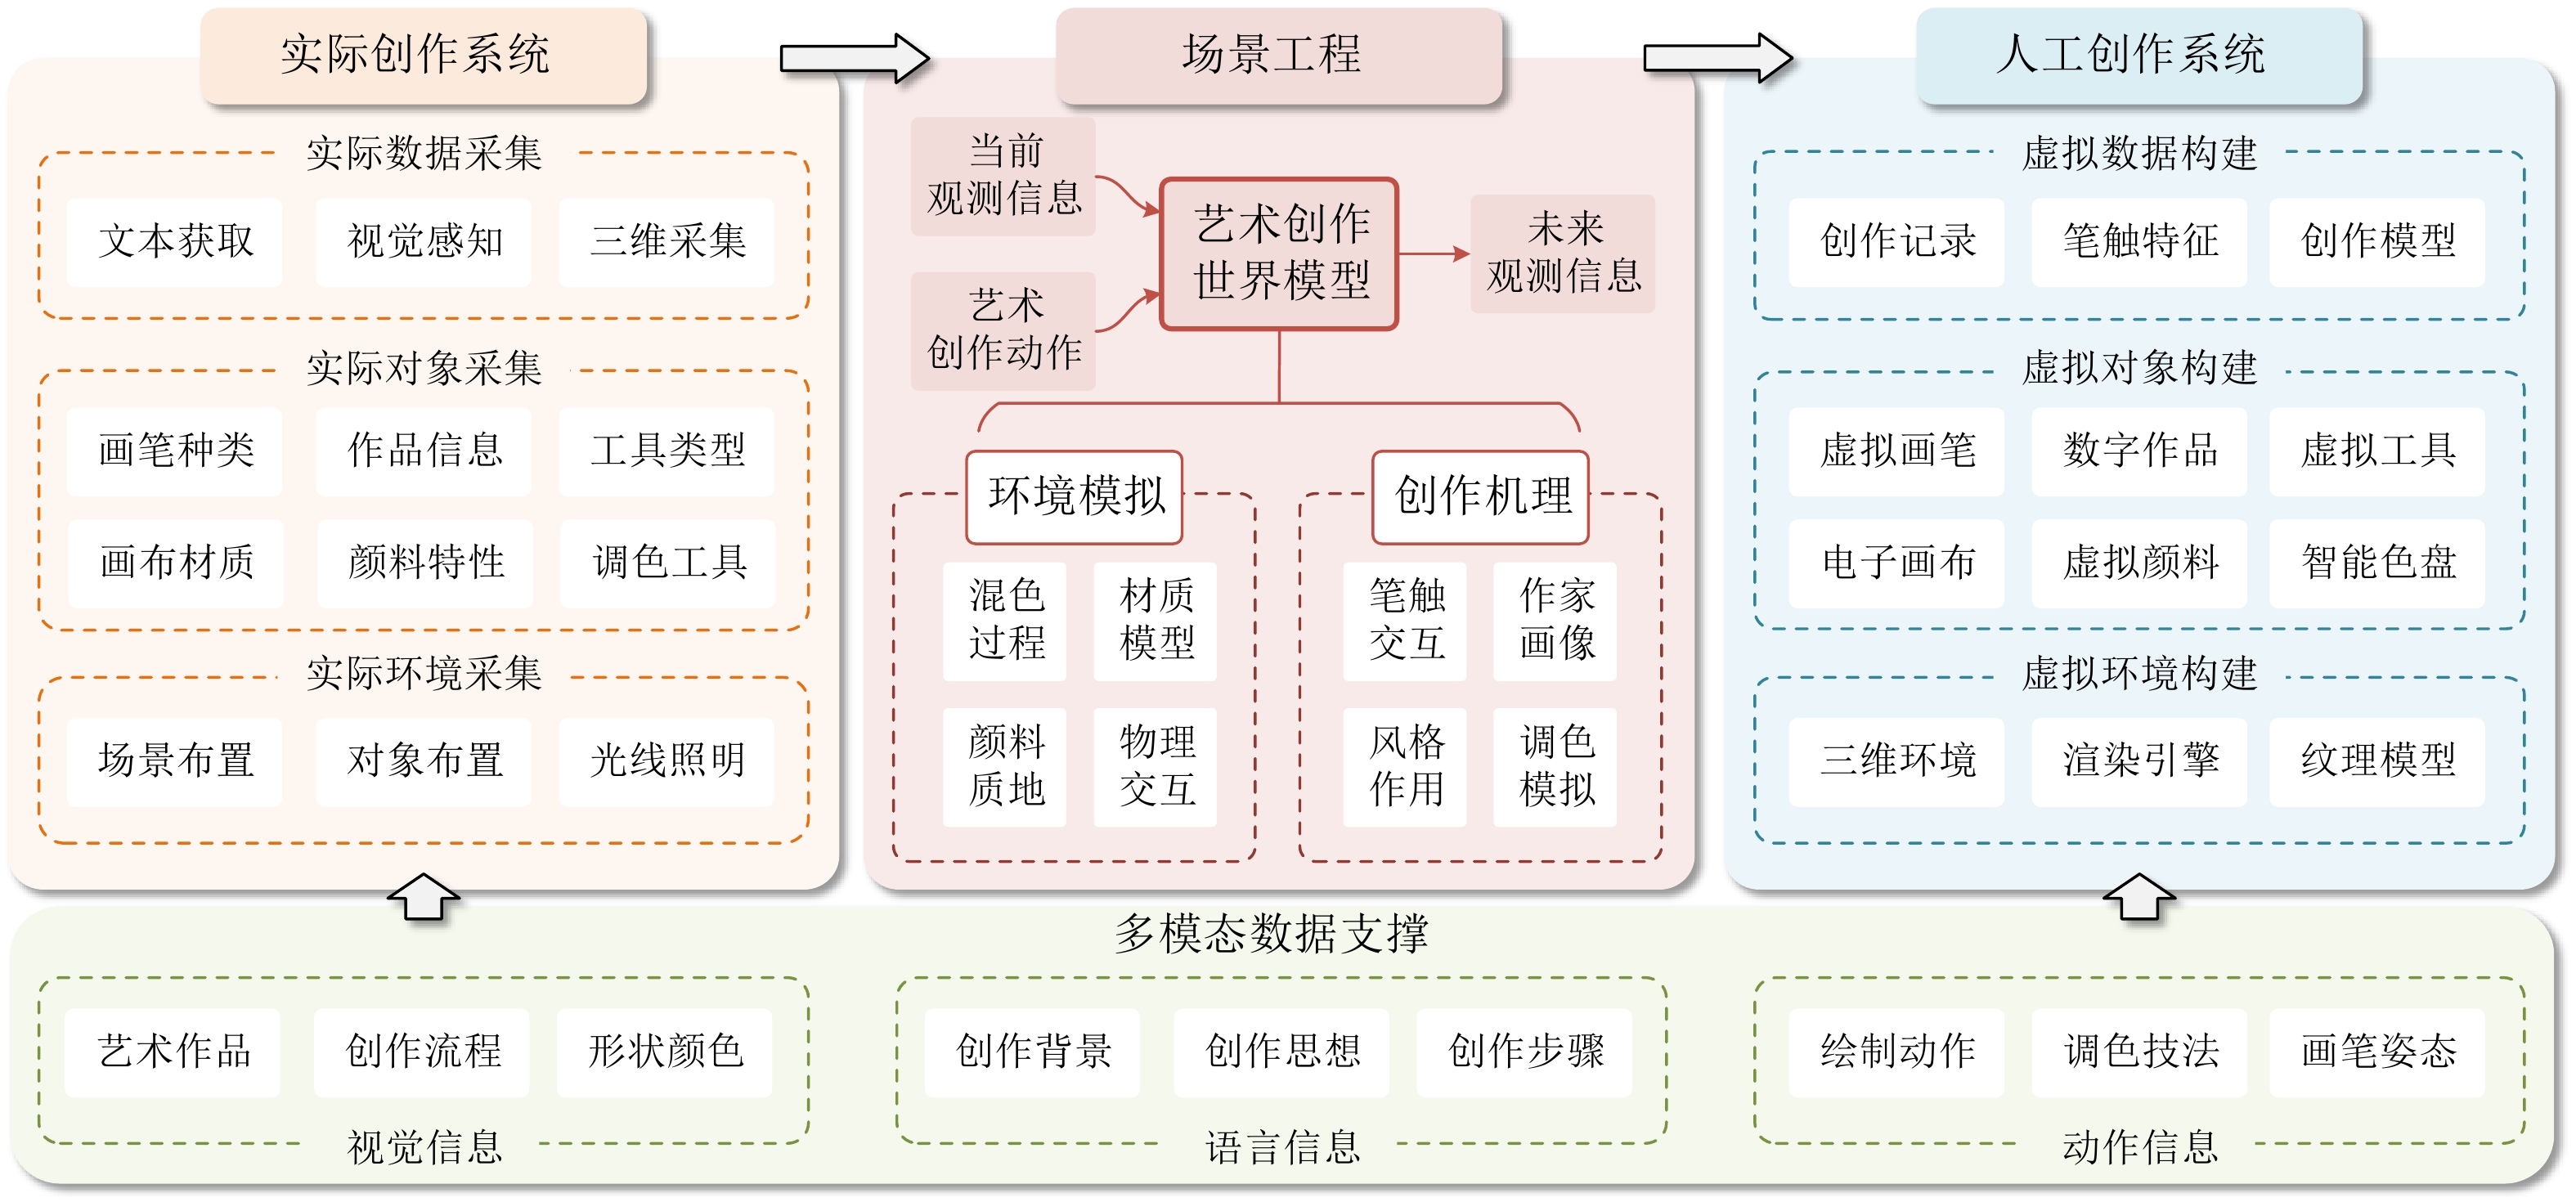
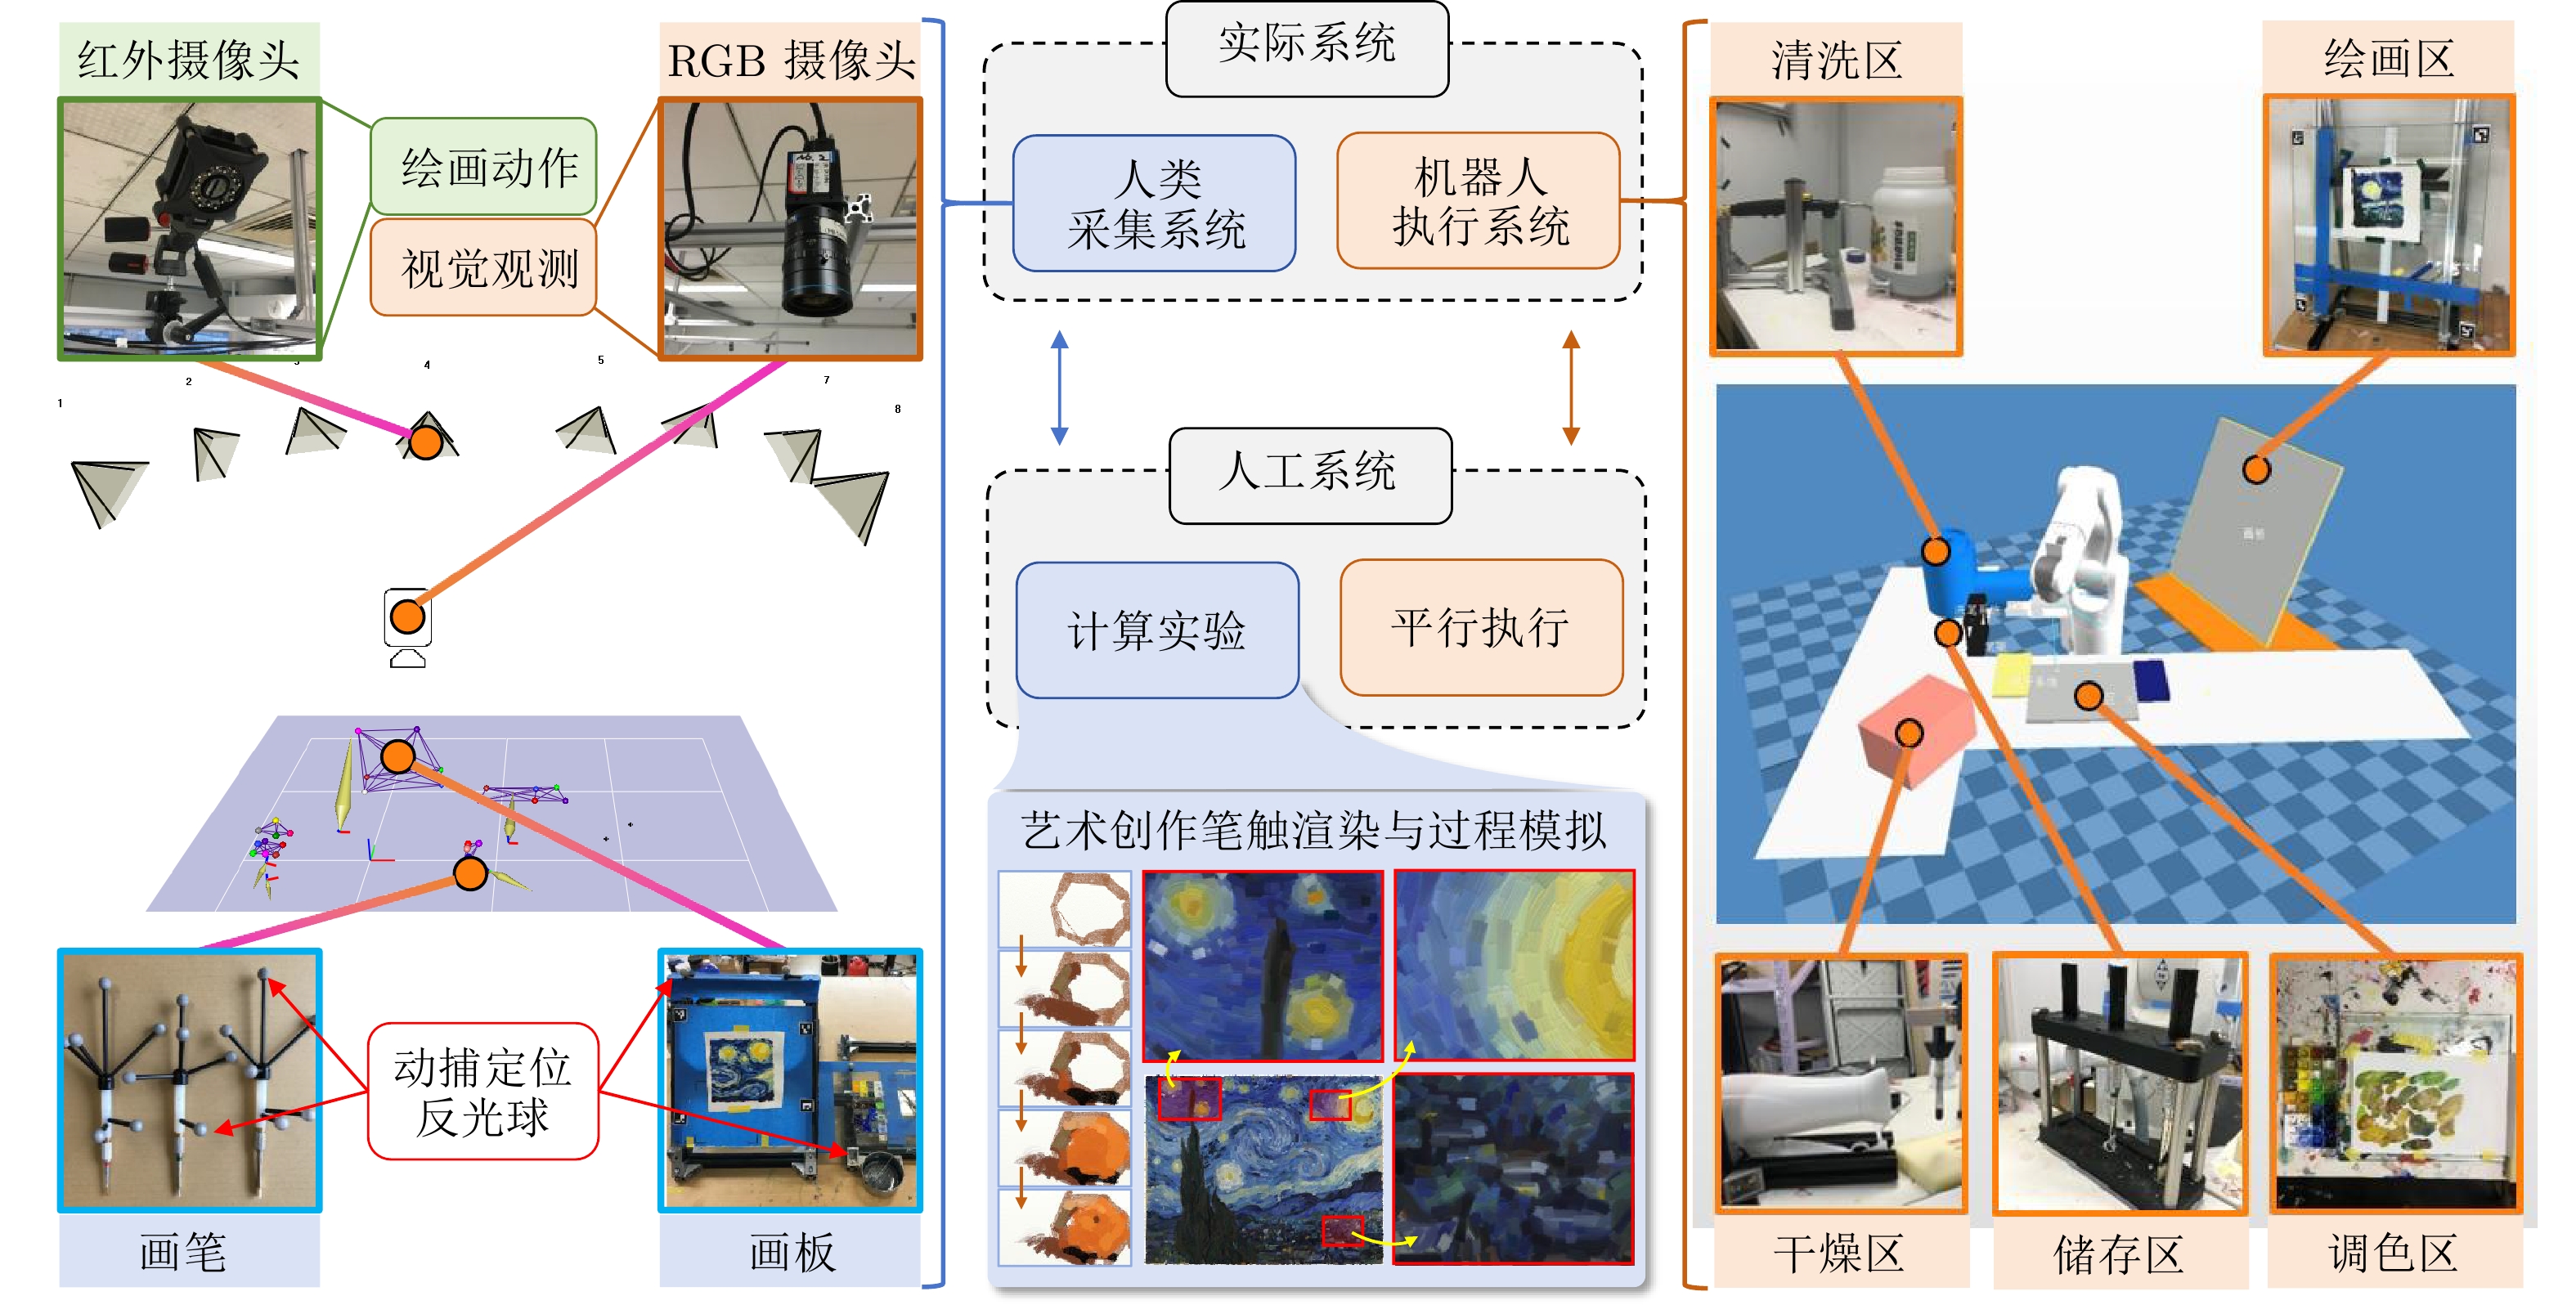
图 2 VLA大模型驱动的平行艺术创作系统描述智能
Fig. 2 Descriptive Intelligence in the large VLA model-driven parallel art creation system
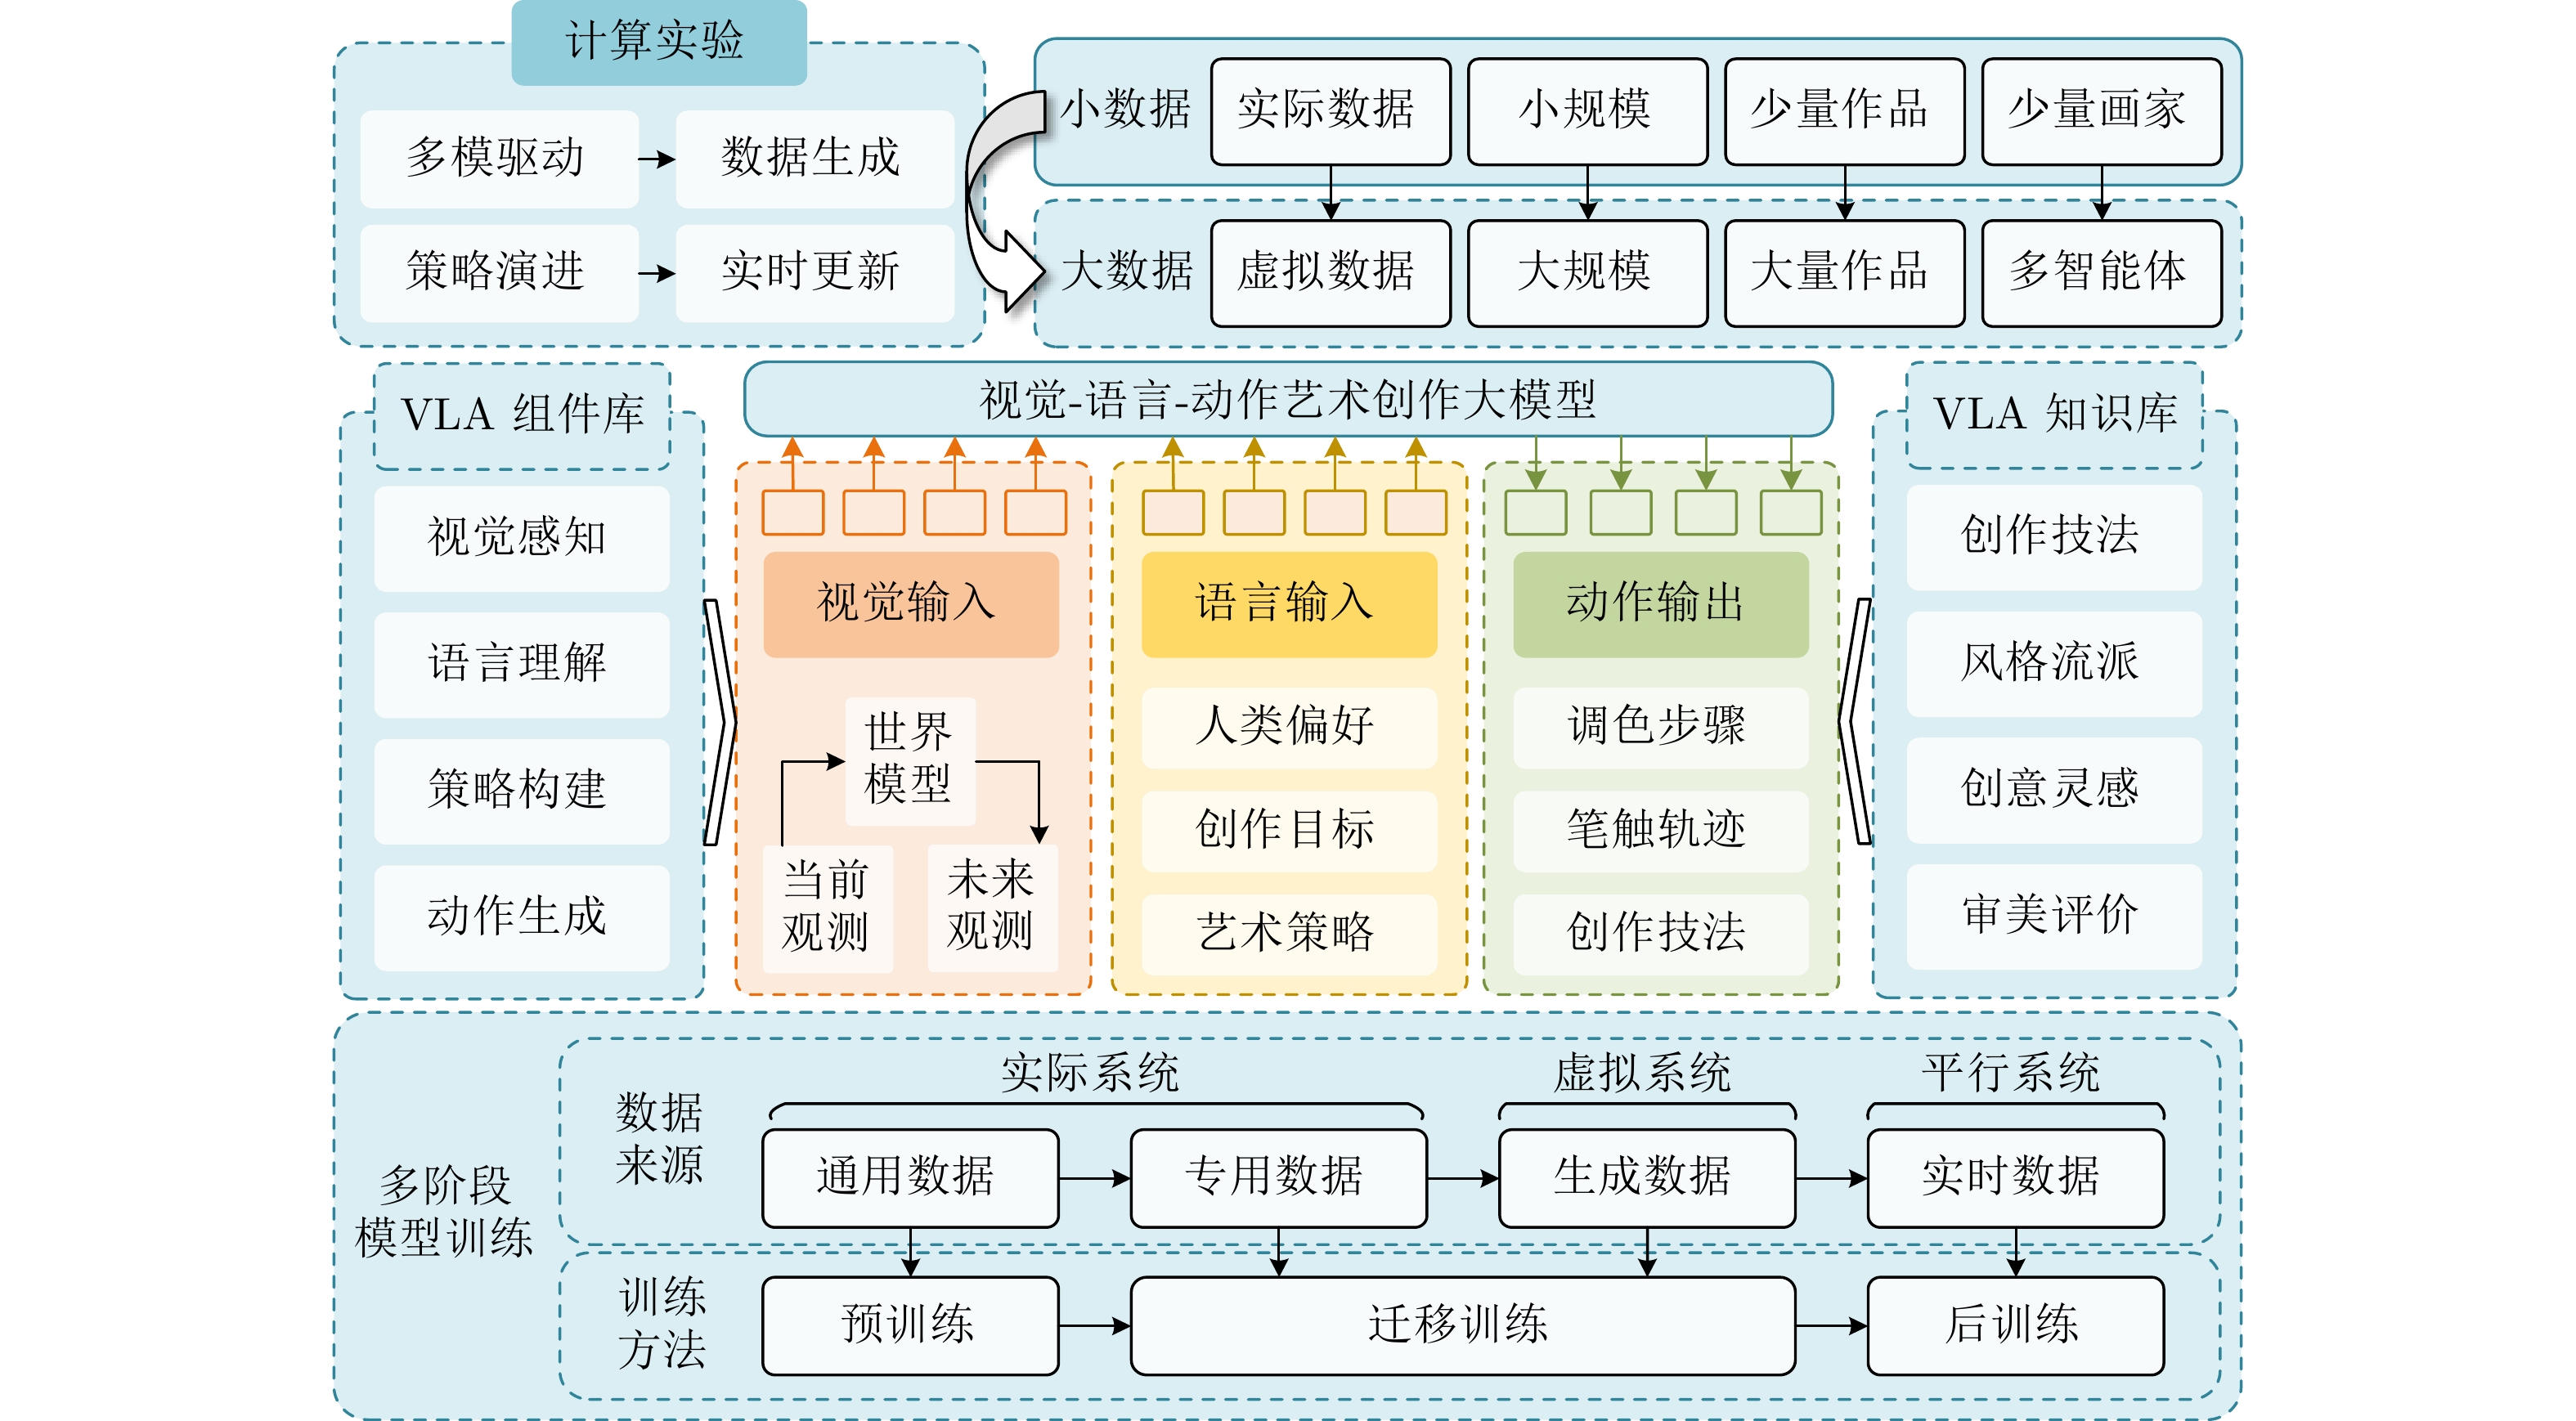
图 3 VLA大模型驱动的平行艺术创作系统预测学习
Fig. 3 Predictive Learning in the large VLA model-driven parallel art creation system
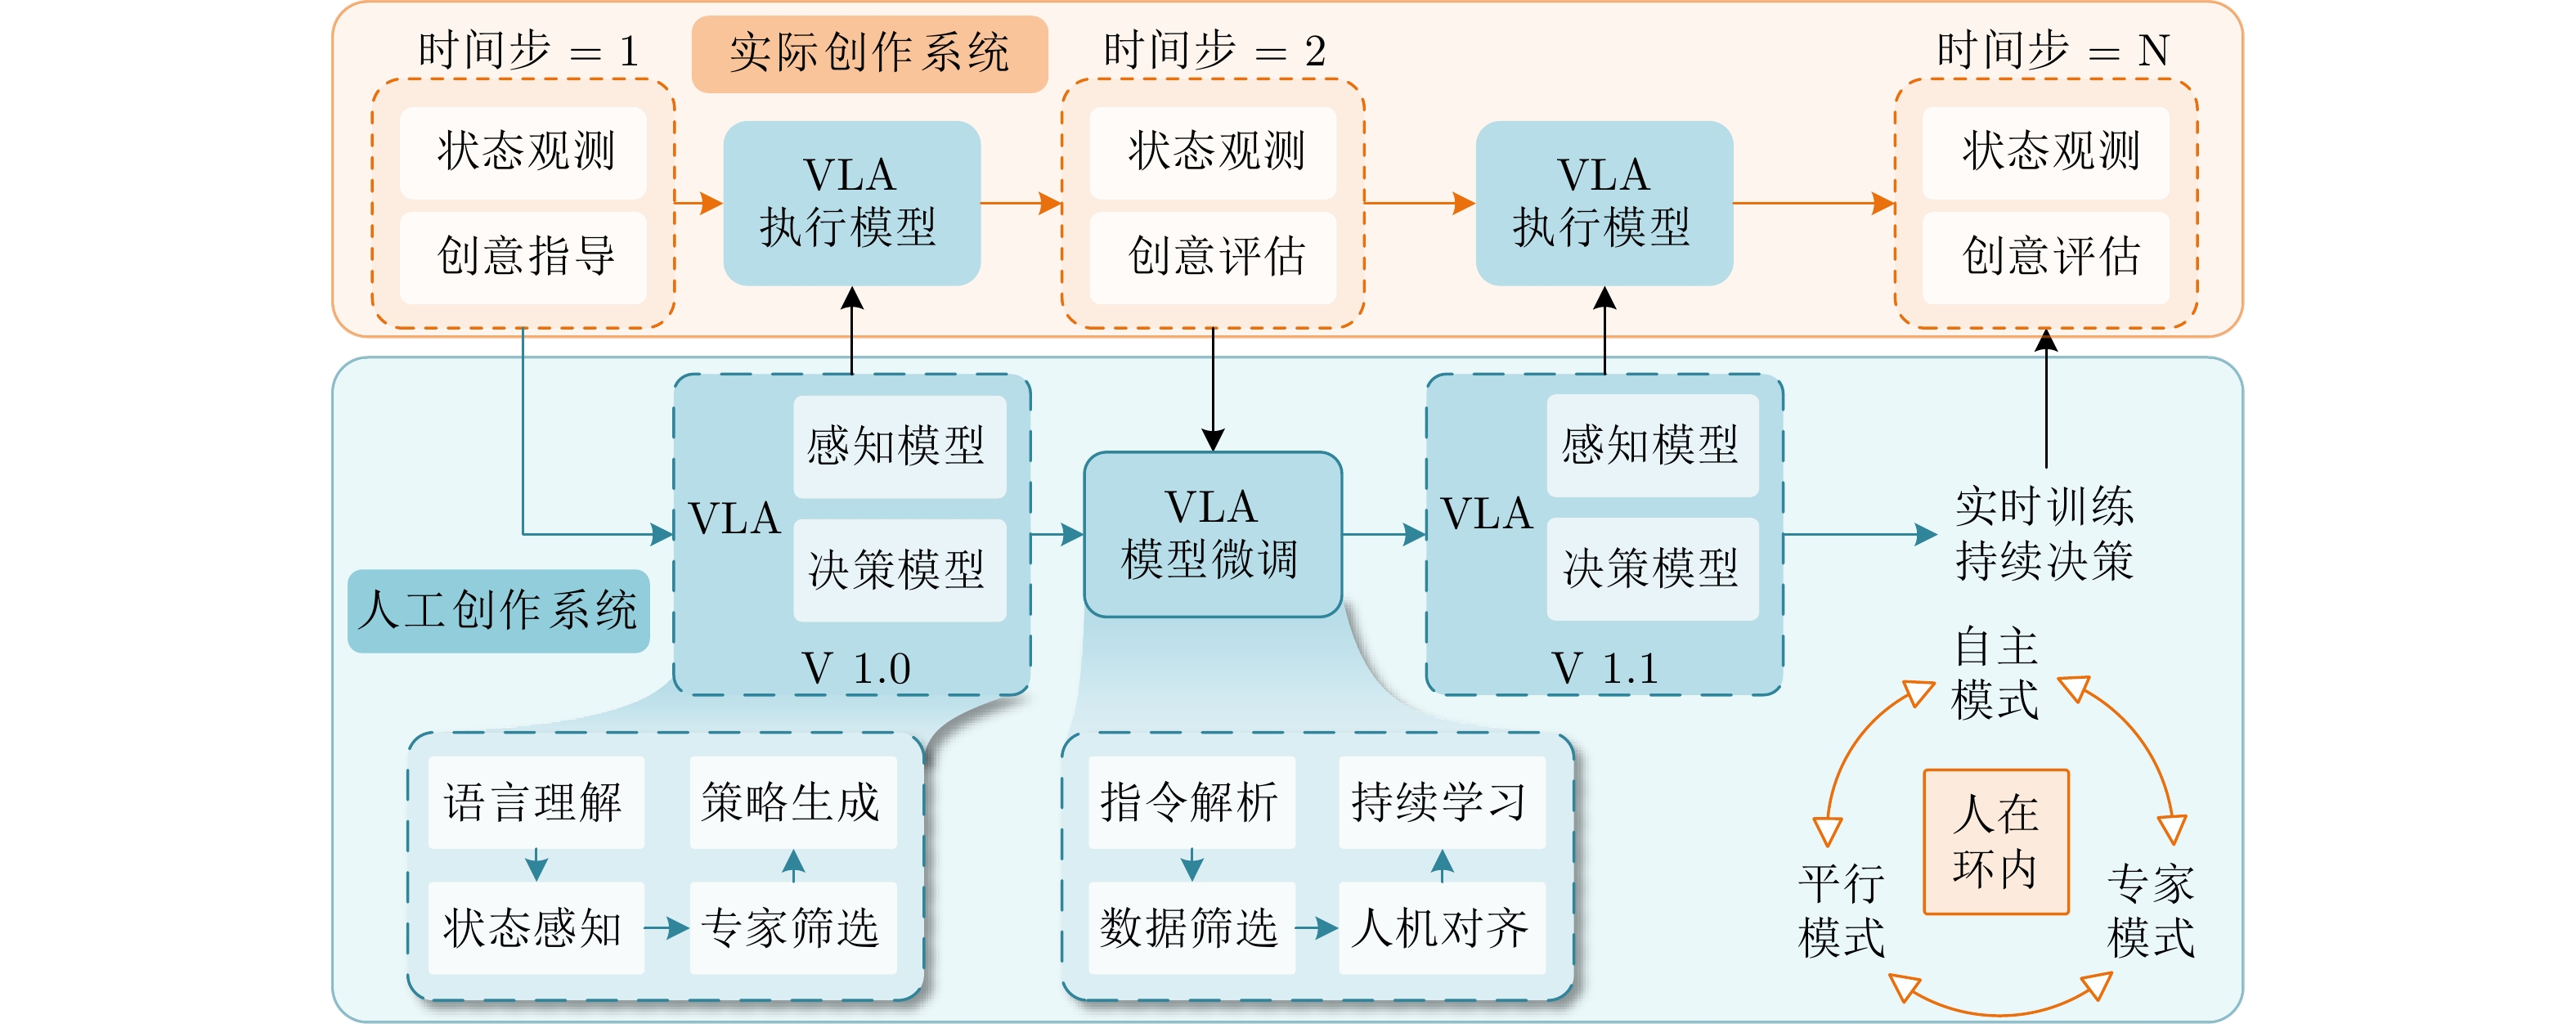
图 4 VLA大模型驱动的平行艺术创作系统引导学习
Fig. 4 Prescriptive Learning in the large VLA model-driven parallel art creation system
-
[1] Wang F Y. From Plant Modeling to Narrative Science: Growing and Enjoying Scientific Fruits Naturally and Humanistically. IEEE/CAA Journal of Automatica Sinica, 2024, 11(12): 2522−2524. doi: 10.1109/JAS.2024.124959 [2] Wang X, Jiang H, Yu Y, et al. Building intelligence identification system via large language model watermarking: a survey and beyond. Artificial Intelligence Review, 2025, 58(8): 249. doi: 10.1007/s10462-025-11222-w [3] Brooks R A. Intelligence without representation. Artificial intelligence, 1991, 47(3): 139−159. [4] Anderson P, Wu Q, Teney D, et al. Vision-and-language navigation: Interpreting visually-grounded navigation instructions in real environments[C]// Proceedings of the IEEE conference on computer vision and pattern recognition, 2018: 3674-3683. [5] Chi C, Xu Z, Feng S, et al. Diffusion policy: Visuomotor policy learning via action diffusion[J]. The International Journal of Robotics Research, 2023: 3668. [6] Garcia M B. The paradox of artificial creativity: Challenges and opportunities of generative AI artistry[J]. Creativity Research Journal, 2024: 1-14. [7] Park S. The work of art in the age of generative AI: aura, liberation, and democratization. AI & society, 2025, 40(3): 1807−1816. doi: 10.1007/s00146-024-01948-6 [8] Du X, An P, Leung J, Li A, Chapman L E, Zhao J. DeepThInk: Designing and probing human-AI co-creation in digital art therapy. International journal of human-computer studies, 2024, 181: 103139. doi: 10.1016/j.ijhcs.2023.103139 [9] Lu Y, Guo C, Dai X, Wang F Y. Generating emotion descriptions for fine art paintings via multiple painting representations. IEEE Intelligent Systems, 2023, 38(3): 31−40. doi: 10.1109/MIS.2023.3260992 [10] El Ardeliya V, Taylor J, Wolfson J. Exploration of artificial intelligence in creative fields: Generative art, music, and design. International Journal of Cyber and IT Service Management, 2024, 4(1): 40−46. doi: 10.34306/ijcitsm.v4i1.149 [11] 张慧, 梁姝彤, 李明轩, 等. 视觉–语言–动作模型综述: 从前史到前沿. 自动化学报, 2025, 51(9): 1922−1950. doi: 10.16383/j.aas.c250417Zhang Hui, Liang Shu-Tong, Li Ming-Xuan, et al. Vision-Language-Action models: From the early foundations to the state-of-the-art. Acta Automatica Sinica, 2025, 51(9): 1922−1950. doi: 10.16383/j.aas.c250417 [12] Shridhar M, Manuelli L, Fox D. Cliport: What and where pathways for robotic manipulation[C]// Conference on robot learning. PMLR, 2022: 894-906. [13] Ouyang L, Wu J, Jiang X, et al. Training language models to follow instructions with human feedback. Advances in neural information processing systems, 2022, 35: 27730−27744. [14] 李柏, 郝金第, 孙跃硕, 等. 平行智能范式视角下的视觉−语言−动作模型发展现状与展望. 智能科学与技术学报, 2025, 03(07): 290−303. doi: 10.11959/j.issn.2096-6652.202536Li Bai, Hao Jin-Di, Sun Yue-Shuo, et al. Vision-language-action models under parallel intelligence paradigm: the state of the art and future perspectives. Chinese Journal of Intelligent Science and Technology, 2025, 03(07): 290−303. doi: 10.11959/j.issn.2096-6652.202536 [15] Jiang Y, Gupta A, Zhang Z, et al. VIMA: General robot manipulation with multimodal prompts[J]. arXiv preprint arXiv: 2210.03094, 2022. [16] 郭超, 鲁越, 林懿伦, 卓凡, 王飞跃. 平行艺术: 人机协作的艺术创作. 智能科学与技术学报, 2019, 1(04): 335−341. doi: 10.11959/j.issn.2096-6652.201938Guo Chao, Lu Yue, Lin Yi-Lun, Zhuo Fan, Wang Fei-Yue. Parallel art: Artistic creation under human-machine collaboration. Chinese Journal of Intelligent Science and Technology, 2019, 1(04): 335−341. doi: 10.11959/j.issn.2096-6652.201938 [17] Guo C, Dou Y, Bai T, Dai X, Wang C, Wen Y. ArtVerse: A paradigm for parallel human-machine collaborative painting creation in metaverses. IEEE Transactions on Systems, Man, and Cybernetics: Systems, 2023, 53(4): 2200−2208. doi: 10.1109/TSMC.2022.3230406 [18] Yu H, Liu X, Tian Y, Wang Y, Gou C, Wang F Y. Sora-based parallel vision for smart sensing of intelligent vehicles: From foundation models to foundation intelligence. IEEE Transactions on Intelligent Vehicles, 2024, 9(2): 3123−3126. doi: 10.1109/tiv.2024.3376575 [19] Zhang J, Huang J, Jin S, Lu S. Vision-language models for vision tasks: A survey. IEEE transactions on pattern analysis and machine intelligence, 2024, 46(8): 5625−5644. doi: 10.1109/tpami.2024.3369699 [20] Zitkovich B, Yu T, Xu S, et al. Rt-2: Vision-language-action models transfer web knowledge to robotic control[C]// Conference on Robot Learning. PMLR, 2023: 2165-2183. [21] Kim M J, Finn C, Liang P. Fine-tuning vision-language-action models: Optimizing speed and success[J]. arXiv preprint arXiv: 2502.19645, 2025. [22] Chen Y, Tian S, Liu S, Zhou Y, Li H, Zhao D. Conrft: A reinforced fine-tuning method for vla models via consistency policy[J]. arXiv preprint arXiv: 2502.05450, 2025. [23] Kim M J, Pertsch K, Karamcheti S, et al. OpenVLA: An open-source vision-language-action model[J]. arXiv preprint arXiv: 2406.09246, 2024. [24] Belkhale S, Ding T, Xiao T, et al. RT-H: Action hierarchies using language[J]. arXiv preprint arXiv: 2403.01823, 2024. [25] Arai H, Miwa K, Sasaki K, et al. Covla: Comprehensive vision-language-action dataset for autonomous driving[C]// 2025 IEEE/CVF Winter Conference on Applications of Computer Vision (WACV). IEEE, 2025: 1933--1943. [26] Ma Y, Song Z, Zhuang Y, Hao J, King I. A survey on vision-language-action models for embodied ai[J]. arXiv preprint arXiv: 2405.14093, 2024. [27] Sapkota R, Cao Y, Roumeliotis K I, Karkee M. Vision-language-action models: Concepts, progress, applications and challenges[J]. arXiv preprint arXiv: 2505.04769, 2025. [28] Wang X, Yang J, Liu Y, et al. Parallel intelligence in three decades: A historical review and future perspective on ACP and cyber-physical-social systems. Artificial Intelligence Review, 2024, 57(9): 255. doi: 10.1007/s10462-024-10861-9 [29] Li J, Qin R, Olaverri-Monreal C, Prodan R, Wang F Y. Logistics 5.0: From intelligent networks to sustainable ecosystems. IEEE Transactions on Intelligent Vehicles, 2023, 8(7): 3771−3774. doi: 10.1109/TIV.2023.3295796 [30] Yang J, Dai X, Zheng N, Ye P, Lv Y, Wang F Y. TrafficRAG for Transportation 5.0: Building “6S” Parallel Transportation Systems via Retrieval-Augmented Generation[J]. IEEE Intelligent Transportation Systems Magazine, 2025. [31] Lv Y. From Cold Algorithms to Warm Intelligence: Infusing Autonomous Driving Systems With Humanistic Care. IEEE Intelligent Transportation Systems Magazine, 2025, 17(4): 2−3. doi: 10.1109/mits.2025.3570413 [32] Li Z, Li Z, Hu X, et al. VisionTraj: a noise-robust trajectory recovery framework based on large-scale camera network[J]. IEEE Transactions on Intelligent Transportation Systems, 2025. [33] Du Q, Xu L, Wu Q, et al. SafeCrossNet: Multi-modal fusion with social-aware for pedestrian crossing intention prediction[J]. Information Fusion, 2025: 103609. [34] Zhang H, Jia X, Luo G, Tian Y, Liang S, Hong D. Parallel Images: Knowledge and Data-Driven Multi-Modal Information Intelligent Analysis. The International Journal of Intelligent Control and Systems, 2025, 30(2): 93−107. doi: 10.62678/ijics202506.10175 [35] 倪清桦, 郭超, 王飞跃. 平行戏剧: 新时代戏剧的人机协同创作与智能管理. 智能科学与技术学报, 2023, 5(4): 436−445. doi: 10.11959/j.issn.2096-6652.202344Ni Qing-Hua, Guo Chao, Wang Fei-Yue. Parallel theaters: human-machine collaborative creation and intelligent management for theatrical art. Chinese Journal of Intelligent Science and Technology, 2023, 5(4): 436−445. doi: 10.11959/j.issn.2096-6652.202344 [36] Bai T, Guo C, Liu Y, Lu Y, Dai X, Wang F. Parallel calligraphy robot: Framework and system implementation. IEEE Journal of Radio Frequency Identification, 2022, 7: 163−167. doi: 10.1109/jrfid.2022.3212589 [37] 倪清桦, 鲁越, 林飞, 等. 平行音乐: 大模型时代的人机混合音乐创演. 智能科学与技术学报, 2024, 6(2): 150−163. doi: 10.11959/j.issn.2096-6652.202423Ni Qing-Hua, Lu Yue, Lin Fei, et al. Parallel music: human-machine hybrid music creation and performance in the era of large models. Chinese Journal of Intelligent Science and Technology, 2024, 6(2): 150−163. doi: 10.11959/j.issn.2096-6652.202423 [38] Ni Q, Vikt O Ria B, Lin F, et al. Parallel Theaters in CPSS: From Shadows of ISDOS to Intelligence of Decision Theaters. IEEE/CAA Journal of Automatica Sinica, 2025, 12(6): 1059−1062. doi: 10.1109/JAS.2025.125567 [39] Lu Y, Guo C, Dou Y, Dai X, Wang F Y. Could ChatGPT imagine: Content control for artistic painting generation via large language models. Journal of Intelligent & Robotic Systems, 2023, 109(2): 39. doi: 10.1007/s10846-023-01956-6 [40] 郭超, 鲁越, 王晓, 易达, 王虓, 王飞跃. 人机物CPSS智能融合的平行创作架构与关键技术研究. 智能科学与技术学报, 2022, 4(3): 344−354. doi: 10.11959/j.issn.2096−6652.202246Guo Chao, Lu Yue, Wang Xiao, Yi Da, Wang Xiao, Wang Fei-Yue. Architecture and key techniques of parallel creation through the fusion of human-cyber-physical intelligence in CPSS. Chinese Journal of Intelligent Science and Technology, 2022, 4(3): 344−354. doi: 10.11959/j.issn.2096−6652.202246 [41] Lu Y, Guo C, Dai X, Wang F Y. Data-efficient image captioning of fine art paintings via virtual-real semantic alignment training. Neurocomputing, 2022, 490: 163−180. doi: 10.1016/j.neucom.2022.01.068 [42] Yi D, Guo C, Bai T. Exploring painting synthesis with diffusion models[C]// 2021 IEEE 1st International Conference on Digital Twins and Parallel Intelligence (DTPI). IEEE, 2021: 332-335. [43] 王春法, 王飞跃, 鲁越, 李华飙, 郭超. 平行博物馆: 新时代博物馆运营的智能管理与控制. 智能科学与技术学报, 2021, 3(02): 125−136. doi: 10.11959/j.issn.2096−6652.202113Wang Chun-Fa, Wang Fei-Yue, Lu Yue, Li Hua-Biao. Parallel museums: Intelligent management and control of museum operations in the new era. Chinese Journal of Intelligent Science and Technology, 2021, 3(02): 125−136. doi: 10.11959/j.issn.2096−6652.202113 [44] 鲁越, 郭超, 潘晴, 等. 平行博物馆系统: 框架、平台、方法及应用. 模式识别与人工智能, 2023, 36(07): 575−589. doi: 10.16451/j.cnki.issn1003-6059.202307001Lu Yue, Guo Chao, Pan Qing, et al. Parallel museum systems: Framework, platform, methods and applications. Pattern Recognition and Artificial Intelligence, 2023, 36(07): 575−589. doi: 10.16451/j.cnki.issn1003-6059.202307001 [45] 鲁越, 郭超, 倪清桦, 李华飙, 王春法, 王飞跃. 人工智能代理驱动的平行博物馆智慧管控. 智能科学与技术学报, 2024, 6(2): 134−149. doi: 10.11959/j.issn.2096-6652.202415Lu Yue, Guo Chao, Ni Qing-Hua, Li Hua-Biao, Wang Chun-Fa, Wang Fei-Yue. AI agent-driven intelligent management and control of parallel museums. Chinese Journal of Intelligent Science and Technology, 2024, 6(2): 134−149. doi: 10.11959/j.issn.2096-6652.202415 [46] Bai J, Fang J, Lv Y, Lv C, Xue J, Li Z. Gating Syn-to-Real Knowledge for Pedestrian Crossing Prediction in Safe Driving[J]. IEEE Transactions on Intelligent Transportation Systems, 2025. [47] Lu B, Miao Q, Liu Y, et al. A Diffusion Model for Traffic Data Imputation. IEEE/CAA Journal of Automatica Sinica, 2025, 12(3): 606−617. doi: 10.1109/JAS.2024.124611 [48] Du Q, Wang X, Yin S, Li L, Ning H. Social force embedded mixed graph convolutional network for multi-class trajectory prediction. IEEE Transactions on Intelligent Vehicles, 2024, 9(9): 5571−5580. doi: 10.1109/TIV.2024.3352180 [49] Dai X, Guo C, Tang Y, et al. VistaRAG: Toward safe and trustworthy autonomous driving through retrieval-augmented generation. IEEE Transactions on Intelligent Vehicles, 2024, 9(4): 4579−4582. doi: 10.1109/TIV.2024.3396450 [50] Dai X, Vallati M, Guo R, Wang Y, Han S, Lin Y. The road ahead: DAO-secured V2X infrastructures for safe and smart vehicular management. IEEE Transactions on Intelligent Vehicles, 2023, 8(12): 4674−4677. doi: 10.1109/TIV.2023.3337993 [51] Miao Q, Wang F Y, Artificial Intelligence for Science (AI4S): Frontiers and Perspectives Based on Parallel Intelligence. 2024: Springer Nature. [52] 郭超, 戴星原, 廖玮珑, 等. 智能艺术工厂: 基于平行艺术智能体的创作自动化. 智能科学与技术学报, 2024, 6(02): 179−188. doi: 10.11959/j.issn.2096-6652.202421Guo Chao, Dai Xing-Yuan, Liao Wei-Long, et al. Intelligent art factory: achieving creative automation through parallel art agents. Chinese Journal of Intelligent Science and Technology, 2024, 6(02): 179−188. doi: 10.11959/j.issn.2096-6652.202421 [53] Guo C, Bai T, Lu Y, et al. Skywork-daVinci: A novel CPSS-based painting support system[C]// Proceedings of the IEEE International Conference on Automation Science and Engineering. Piscataway: IEEE Press, 2020: 673-678. [54] Lu Y, Guo C, Dai X, Wang F Y. ArtCap: A dataset for image captioning of fine art paintings. IEEE Transactions on Computational Social Systems, 2024, 11(1): 576−587. doi: 10.1109/TCSS.2022.3223539 [55] Guo C, Lu Y, Dou Y, Wang F Y. Can ChatGPT boost artistic creation: The need of imaginative intelligence for parallel art. IEEE/CAA Journal of Automatica Sinica, 2023, 10(4): 835−838. doi: 10.1109/JAS.2023.123555 [56] Xie W, Guo C, Wang Y J, Lv Y, Wang F Y, Others. Plug-and-Play Dramaturge: A Divide-and-Conquer Approach for Iterative Narrative Script Refinement via Collaborative LLM Agents[J]. arXiv preprint arXiv: 2510.05188, 2025. [57] Lu Y, Guo C, Dai X, Wang F Y. Image captioning on fine art paintings via virtual paintings[C]// Proceedings of the International Conference on Digital Twins and Parallel Intelligence. Piscataway: IEEE Press, 2021: 156-159. [58] Guo C, Bai T, Wang X, et al. ShadowPainter: Active learning enabled robotic painting through visual measurement and reproduction of the artistic creation process. Journal of Intelligent & Robotic Systems, 2022, 105(3): 61. doi: 10.1007/s10846-022-01616-1 [59] 鲁越, 郭超, 林懿伦, 卓凡, 王飞跃. 绘画艺术图像的计算美学: 研究前沿与展望. 自动化学报, 2020, 46(11): 2239−2259. doi: 10.16383/j.aas.c200358Lu Yue, Guo Chao, Lin Yi-Lun, Zhuo Fan, Wang Fei-Yue. Computational aesthetics of fine art paintings: The state of the art and outlook. Acta Automatica Sinica, 2020, 46(11): 2239−2259. doi: 10.16383/j.aas.c200358 [60] Li X, Liu E, Shen T, Huang J, Wang F Y. ChatGPT-based scenario engineer: A new framework on scenario generation for trajectory prediction[J]. IEEE Transactions on Intelligent Vehicles, 2024. [61] Li X, Miao Q, Li L, et al. Sora for senarios engineering of intelligent vehicles: V&V, C&C, and beyonds[J]. IEEE Transactions on Intelligent Vehicles, 2024: 1-6. -

 下载:

计量
- 文章访问数: 1
- HTML全文浏览量: 0
- 被引次数: 0
